

Publish corrected qualification card and evidence
Browse files- .gitattributes +4 -0
- DOCS-SHA256SUMS +15 -2
- README.md +81 -51
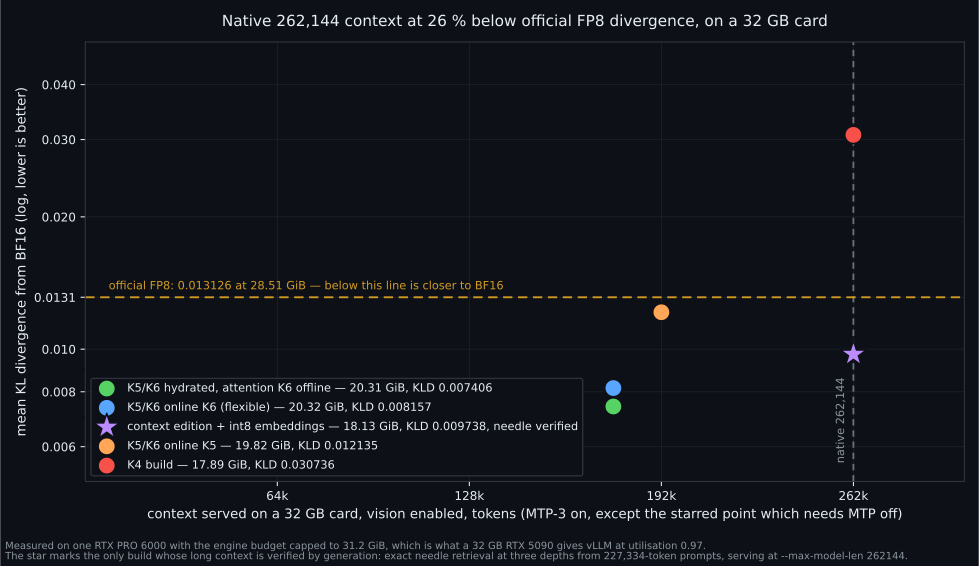
- assets/context-frontier-dark.png +2 -2
- assets/context-frontier-dark.svg +0 -0
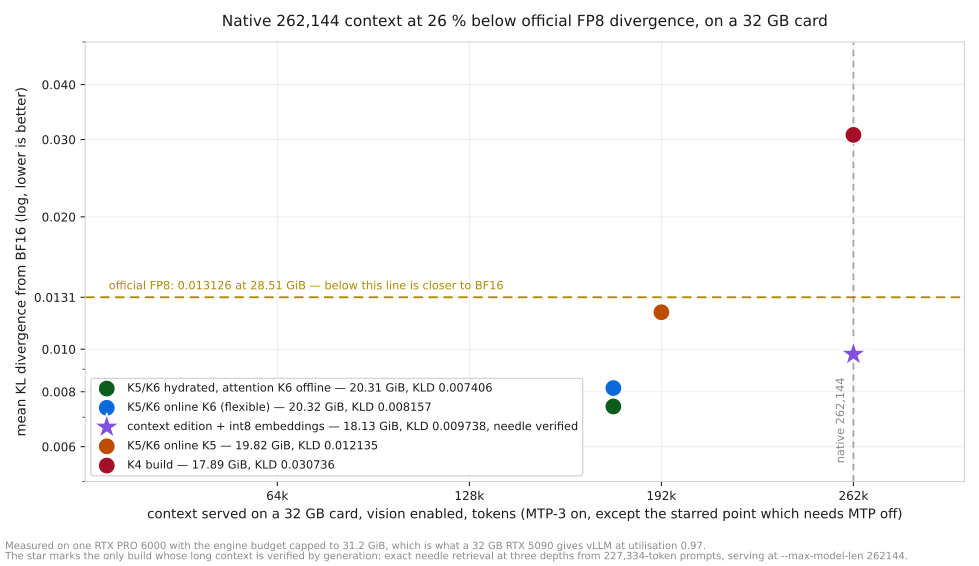
- assets/context-frontier-light.png +2 -2
- assets/context-frontier-light.svg +0 -0
- assets/context-per-card-dark.png +3 -0
- assets/context-per-card-dark.svg +0 -0
- assets/context-per-card-light.png +3 -0
- assets/context-per-card-light.svg +0 -0
- assets/fidelity-vs-size-dark.png +3 -0
- assets/fidelity-vs-size-dark.svg +0 -0
- assets/fidelity-vs-size-light.png +3 -0
- assets/fidelity-vs-size-light.svg +0 -0
- release-evidence.json +48 -12
.gitattributes
CHANGED
|
@@ -36,3 +36,7 @@ saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
|
| 36 |
tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
| 37 |
assets/context-frontier-dark.png filter=lfs diff=lfs merge=lfs -text
|
| 38 |
assets/context-frontier-light.png filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 36 |
tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
| 37 |
assets/context-frontier-dark.png filter=lfs diff=lfs merge=lfs -text
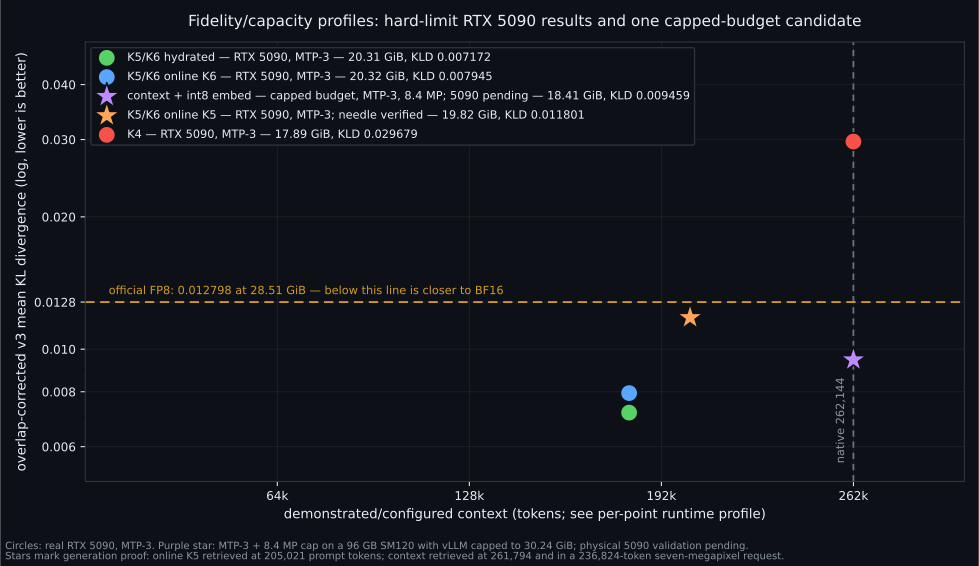
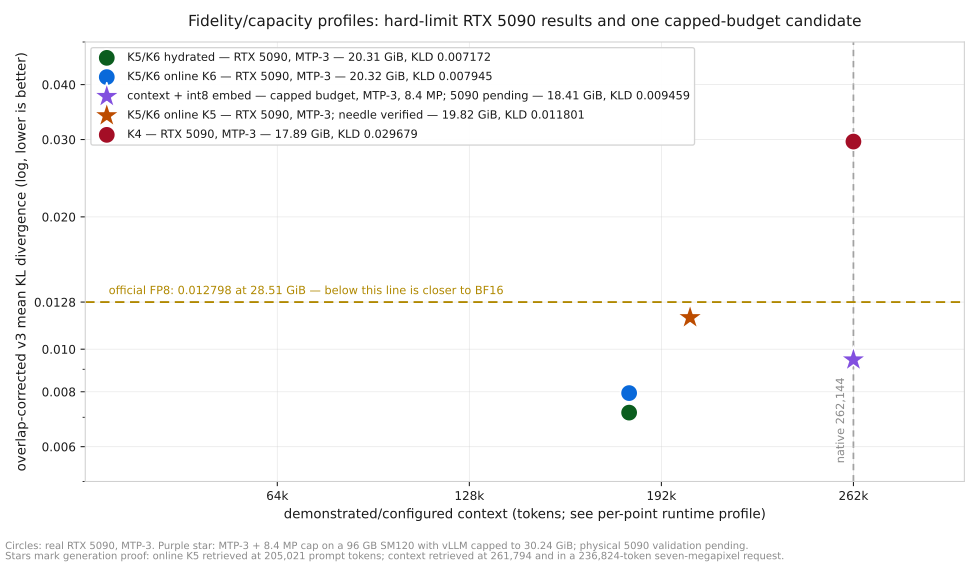
|
| 38 |
assets/context-frontier-light.png filter=lfs diff=lfs merge=lfs -text
|
| 39 |
+
assets/context-per-card-dark.png filter=lfs diff=lfs merge=lfs -text
|
| 40 |
+
assets/context-per-card-light.png filter=lfs diff=lfs merge=lfs -text
|
| 41 |
+
assets/fidelity-vs-size-dark.png filter=lfs diff=lfs merge=lfs -text
|
| 42 |
+
assets/fidelity-vs-size-light.png filter=lfs diff=lfs merge=lfs -text
|
DOCS-SHA256SUMS
CHANGED
|
@@ -1,2 +1,15 @@
|
|
| 1 |
-
34448b82c17d60fec9b65b1f093c115ddbaadc04beb1b0140b6bfed2e012a930
|
| 2 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
34448b82c17d60fec9b65b1f093c115ddbaadc04beb1b0140b6bfed2e012a930 .gitattributes
|
| 2 |
+
264d838d7f2fef99be8e12c1166e80273f531f94419622efd940c438cd30fc5c README.md
|
| 3 |
+
d71eb992953ffd25e07d268a268dbf4953cae40eb14e35ef0d3d7e12f32709c2 assets/context-frontier-dark.png
|
| 4 |
+
df4d8cfdb5ded9e330edbc16223d83ca524f3b67e7bcea910c5a7b4530f11b1b assets/context-frontier-dark.svg
|
| 5 |
+
bafed8e1de217f9311dbf604ab69950adb00e8f3d23a9c2a3ea12184cb47ac8a assets/context-frontier-light.png
|
| 6 |
+
b2b897b7429e517aa0e91ca12a63285672e23eeb8db5ffd4effbb45e50327c62 assets/context-frontier-light.svg
|
| 7 |
+
6339e328f0b865cf03a7d1c608a8e0da555af0b2c30e618733db2d9c8a8ce369 assets/context-per-card-dark.png
|
| 8 |
+
0c34a0701922ddcffdc80f7a3c1105154dd3c9cd773d26fbedc8a9660d14265b assets/context-per-card-dark.svg
|
| 9 |
+
605d513b38a88f16d42c437ebe2c827cb6e3c2973ea7e6c3af6ff1f7df5b3073 assets/context-per-card-light.png
|
| 10 |
+
0df334eec3108065d383674d50789d4d0956e655954b2cf6c55ecdcf46493f65 assets/context-per-card-light.svg
|
| 11 |
+
f8c77a2822223f012b48c6d52aa19caef5b317b515a1ba49ab5d406d963a2ab9 assets/fidelity-vs-size-dark.png
|
| 12 |
+
c01fd0ae8986a68081413ae0d63b4d20853788f07eb0c9816c34655e6cd62b2c assets/fidelity-vs-size-dark.svg
|
| 13 |
+
eeb68bfb3cdeef240bc4a19368cdb7f0cb29493bc3570dfddda519af0a41e1ea assets/fidelity-vs-size-light.png
|
| 14 |
+
61ef12b7b07ae57914ba73199614341fa68fce0149d74851e14b4a878aba03df assets/fidelity-vs-size-light.svg
|
| 15 |
+
0602ce8b2ba9e95b84adc5933ab1138faec605a6c0b12af935bbcd91d94d6aff release-evidence.json
|
README.md
CHANGED
|
@@ -35,8 +35,8 @@ every cold start. Measured consequences:
|
|
| 35 |
| first load, cold | 957 s (encodes 208 projections) | **178 s** (5.4x faster) |
|
| 36 |
| restart with a warm cache | 173 s | 178 s (same) |
|
| 37 |
| persistent encode cache | required, and must be writable | **not used** |
|
| 38 |
-
| mean KL divergence from BF16 (body-only) | 0.
|
| 39 |
-
| mean KL divergence, as served | 0.
|
| 40 |
| attention width | K6 / K5 / K4, chosen at launch | fixed at K6 |
|
| 41 |
|
| 42 |
**Choose this build** for the smaller download, the best fidelity in the family, and a start
|
|
@@ -48,24 +48,26 @@ fidelity for KV room, and on a 32 GB card that difference matters (see
|
|
| 48 |
|
| 49 |
## Which of the four builds
|
| 50 |
|
| 51 |
-
Same architecture and tokenizer;
|
| 52 |
-
|
|
|
|
|
|
|
| 53 |
([collection](https://huggingface.co/collections/qwen38-27b-mixed-precision-exl3-measured-6a7fe0cb27817c23e4a57025)).
|
| 54 |
|
| 55 |
<picture>
|
| 56 |
<source media="(prefers-color-scheme: dark)" srcset="assets/context-frontier-dark.svg">
|
| 57 |
-
<img alt="
|
| 58 |
</picture>
|
| 59 |
|
| 60 |
-
| build | download | resident | mean KLD | context
|
| 61 |
|---|---:|---:|---:|---:|---|
|
| 62 |
-
| [-hydrated](https://huggingface.co/malaiwah/Qwen3.8-27B-EXL3-K5K6-hydrated) | 21.61 GB | 20.31 GiB | **0.
|
| 63 |
-
| [-EXL3-K5K6](https://huggingface.co/malaiwah/Qwen3.8-27B-EXL3-K5K6) | 30.57 GB | 20.32 GiB | 0.
|
| 64 |
-
| [-context](https://huggingface.co/malaiwah/Qwen3.8-27B-EXL3-K5K6-context) | 20.70 GB | **18.
|
| 65 |
-
| [-K4](https://huggingface.co/malaiwah/Qwen3.8-27B-K4) | 28.31 GB | 17.89 GiB | 0.
|
| 66 |
|
| 67 |
-
Official `Qwen/Qwen3.8-27B-FP8` is 28.51 GiB resident at 0.
|
| 68 |
-
stock vLLM, which none of these do.
|
| 69 |
|
| 70 |
## Recipe
|
| 71 |
|
|
@@ -115,6 +117,11 @@ operands, source-cluster bootstrap. Same suite, reference and head as every comp
|
|
| 115 |
| `Qwen/Qwen3.8-27B-FP8` | 28.51 GiB | 0.013126 | [0.00981, 0.01709] | 0.002343 | 96.22 % |
|
| 116 |
| `unsloth/Qwen3.8-27B-NVFP4` | 21.34 GiB | 0.094978 | [0.06858, 0.12688] | 0.012911 | 90.53 % |
|
| 117 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 118 |
Paired on identical contexts:
|
| 119 |
|
| 120 |
- versus the BF16-attention sibling: **−0.000751**, 95 % CI [−0.000977, −0.000572],
|
|
@@ -131,7 +138,10 @@ head, so no candidate's own head quantization is counted — that is what makes
|
|
| 131 |
since official FP8 serves a BF16 head. Measured directly on **this** checkpoint with asymmetric
|
| 132 |
heads (reference through the true BF16 head, candidate through this build's dequantized K6
|
| 133 |
head): the head costs **+0.000125** (95 % CI [+0.000107, +0.000144], 9/136 contexts favour it),
|
| 134 |
-
so **as served this build is 0.007532** with 97.08 % top-1.
|
|
|
|
|
|
|
|
|
|
| 135 |
body-only 0.013126.
|
| 136 |
|
| 137 |
**Weakest control:** live-versus-replayed logit qualification is 6.54e-04 on this harness,
|
|
@@ -140,9 +150,9 @@ so differences below ~1e-3 are not resolvable. The −0.000751 offline-versus-on
|
|
| 140 |
direction, but treat the magnitude as a point estimate. The FP8 gap, at 7.6x the floor, is
|
| 141 |
not in question.
|
| 142 |
|
| 143 |
-
**Development-set caveat:** the recipe was chosen with
|
| 144 |
-
|
| 145 |
-
|
| 146 |
|
| 147 |
## Post-selection qualification
|
| 148 |
|
|
@@ -151,20 +161,33 @@ not: **160 new contexts from 100 documents with zero intersection with the devel
|
|
| 151 |
(context token hashes 0/160, document names 0/100, content hashes 0/100), partitioned by whole
|
| 152 |
source cluster, run **once**, with no recipe changed afterwards.
|
| 153 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 154 |
| candidate | mean KLD | 95 % CI | top-1 | paired vs FP8 |
|
| 155 |
|---|---:|---|---:|---|
|
| 156 |
-
| [hydrated](https://huggingface.co/malaiwah/Qwen3.8-27B-EXL3-K5K6-hydrated) | **0.
|
| 157 |
-
| [K5/K6 online K6](https://huggingface.co/malaiwah/Qwen3.8-27B-EXL3-K5K6) | 0.
|
| 158 |
-
| [context edition](https://huggingface.co/malaiwah/Qwen3.8-27B-EXL3-K5K6-context) | 0.
|
| 159 |
-
| `Qwen/Qwen3.8-27B-FP8` | 0.
|
| 160 |
-
|
| 161 |
-
The
|
| 162 |
-
|
| 163 |
-
|
| 164 |
-
|
| 165 |
-
|
| 166 |
-
|
| 167 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 168 |
|
| 169 |
## Context capacity
|
| 170 |
|
|
@@ -178,13 +201,15 @@ graphs, vision enabled):
|
|
| 178 |
| K6 attention, seqs 8, util 0.95 | 187,050 tok / 6.71 GiB | **185,600 run** | stable, multimodal-safe |
|
| 179 |
| K6 attention, seqs 8, util 0.98 | 202,185 tok / 7.55 GiB | — | text fine, **a 3,264-token image OOMed** with 33 MiB free |
|
| 180 |
|
| 181 |
-
**Native 262,144 does not fit
|
| 182 |
-
|
| 183 |
-
|
| 184 |
-
|
| 185 |
-
|
| 186 |
-
|
| 187 |
-
|
|
|
|
|
|
|
| 188 |
|
| 189 |
Keep utilisation at **0.95** if you serve images: 0.98 leaves no vision headroom.
|
| 190 |
|
|
@@ -196,18 +221,22 @@ overstated usable VRAM, which produced an overclaim that the tester correctly re
|
|
| 196 |
## Serving
|
| 197 |
|
| 198 |
```bash
|
| 199 |
-
docker run --rm --gpus '"device=0"' --ipc host -p 8000:8000 \
|
| 200 |
-v /models:/models:ro \
|
| 201 |
--entrypoint /opt/venv/bin/vllm \
|
| 202 |
voipmonitor/vllm@sha256:820181fbbc975cd5291c411cda9771d58fecee1636d916f508f47230df20592b \
|
| 203 |
serve /models/Qwen3.8-27B-EXL3-K5K6-hydrated \
|
| 204 |
--served-model-name qwen38 --quantization exl3 --enforce-eager \
|
| 205 |
-
--quantization-config '{"linear":{"weight":"mxfp8"},"ignore":["re:.*visual\\..*","re:.*in_proj_a$","re:.*in_proj_b$","re:.*in_proj_ba$","lm_head"]}' \
|
| 206 |
--mm-processor-kwargs '{"truncation":false}' \
|
| 207 |
--reasoning-parser qwen3 --enable-auto-tool-choice --tool-call-parser qwen3_coder \
|
| 208 |
--max-model-len 8192 --gpu-memory-utilization 0.95 --max-num-seqs 8 \
|
| 209 |
--host 0.0.0.0 --port 8000
|
| 210 |
```
|
|
|
|
|
|
|
|
|
|
|
|
|
| 211 |
|
| 212 |
No `VLLM_EXL3_ONLINE_TRELLIS_BITS`, no `VLLM_EXL3_ONLINE_CACHE_DIR`: nothing is encoded at
|
| 213 |
load, which is the point of this build. Three notes carry over from the sibling:
|
|
@@ -217,32 +246,33 @@ load, which is the point of this build. Three notes carry over from the sibling:
|
|
| 217 |
`model.`, so `re:.*visual\..*` matches while `re:.*\.visual\..*` silently does not, and the
|
| 218 |
wrong pattern **crashes** startup
|
| 219 |
([#311](https://github.com/local-inference-lab/vllm/issues/311), fixed by
|
| 220 |
-
[PR #312](https://github.com/local-inference-lab/vllm/pull/312)).
|
| 221 |
-
|
|
|
|
| 222 |
3. **`--mm-processor-kwargs '{"truncation":false}'` is required for images** whose expanded
|
| 223 |
token sequence exceeds 2,048, or requests fail with HTTP 400
|
| 224 |
([#313](https://github.com/local-inference-lab/vllm/issues/313)).
|
| 225 |
|
| 226 |
The command above is what the **pinned image runs unmodified**, so it is eager-only. CUDA-graph
|
| 227 |
-
decode (+46-50 %) and the prefill
|
| 228 |
-
([#314](https://github.com/local-inference-lab/vllm/pull/314),
|
| 229 |
-
[#316](https://github.com/local-inference-lab/vllm/pull/316)
|
| 230 |
-
|
|
|
|
| 231 |
|
| 232 |
## What is not verified
|
| 233 |
|
| 234 |
-
|
| 235 |
-
|
| 236 |
-
|
|
|
|
| 237 |
Throughput was not re-measured here: this build shares the sibling's kernels and resident
|
| 238 |
footprint, so its decode and prefill figures should carry over — that is an inference, not a
|
| 239 |
measurement.
|
| 240 |
|
| 241 |
-
Evaluation captures for this build are
|
| 242 |
-
[fidelity dataset](https://huggingface.co/datasets/malaiwah/qwen38-27b-fidelity-suite-v3)
|
| 243 |
-
|
| 244 |
-
[receipts](https://github.com/malaiwah/qwen38-27b-exl3/tree/main/receipts) let a third party
|
| 245 |
-
check the arithmetic but not recompute the row independently.
|
| 246 |
|
| 247 |
## Machine-readable evidence
|
| 248 |
|
|
|
|
| 35 |
| first load, cold | 957 s (encodes 208 projections) | **178 s** (5.4x faster) |
|
| 36 |
| restart with a warm cache | 173 s | 178 s (same) |
|
| 37 |
| persistent encode cache | required, and must be writable | **not used** |
|
| 38 |
+
| mean KL divergence from BF16 (body-only) | 0.007945 | **0.007172** (−9.7 %, but see the floor caveat) |
|
| 39 |
+
| mean KL divergence, as served | 0.008078 | **0.007300** (measured, not estimated) |
|
| 40 |
| attention width | K6 / K5 / K4, chosen at launch | fixed at K6 |
|
| 41 |
|
| 42 |
**Choose this build** for the smaller download, the best fidelity in the family, and a start
|
|
|
|
| 48 |
|
| 49 |
## Which of the four builds
|
| 50 |
|
| 51 |
+
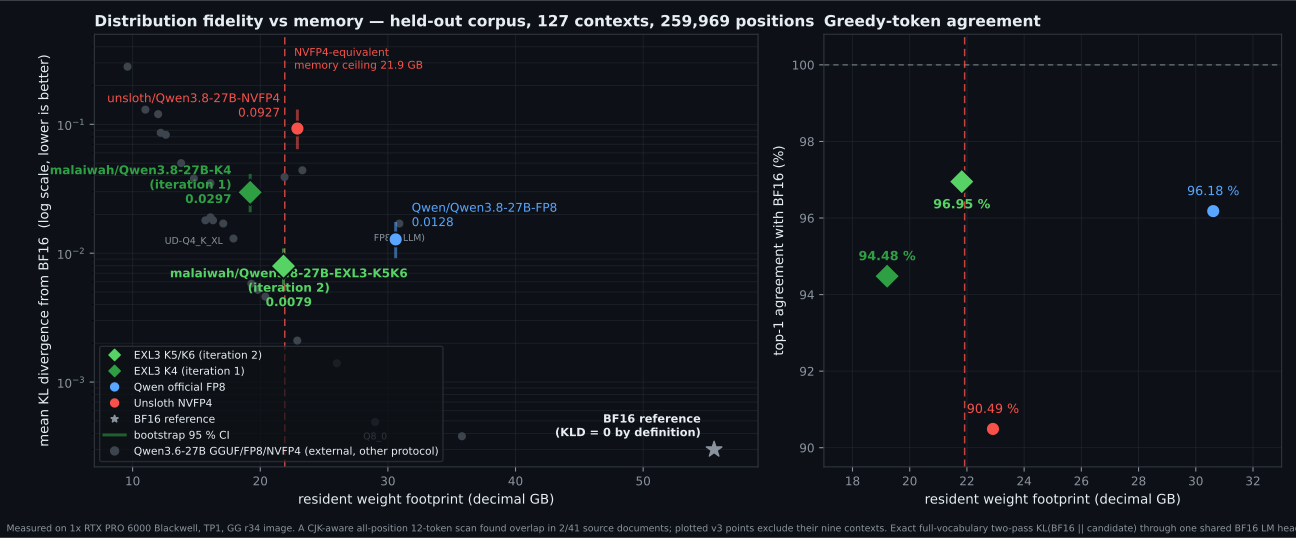
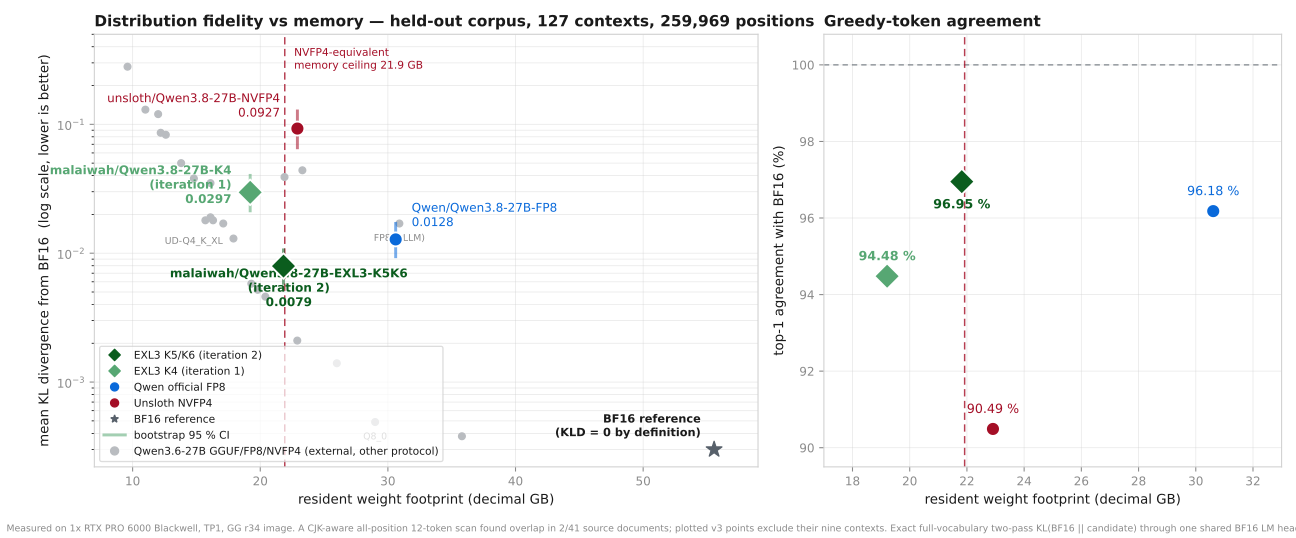
Same architecture and tokenizer; the KLD column is the overlap-corrected 127-context v3
|
| 52 |
+
subset. Capacity uses each card's documented profile: hydrated, online and K4 are real RTX
|
| 53 |
+
5090 MTP-3 tests; context is MTP-3 with an 8.4 MP cap on a budget-capped RTX PRO 6000.
|
| 54 |
+
These profiles are not interchangeable
|
| 55 |
([collection](https://huggingface.co/collections/qwen38-27b-mixed-precision-exl3-measured-6a7fe0cb27817c23e4a57025)).
|
| 56 |
|
| 57 |
<picture>
|
| 58 |
<source media="(prefers-color-scheme: dark)" srcset="assets/context-frontier-dark.svg">
|
| 59 |
+
<img alt="Overlap-corrected v3 mean KL divergence versus demonstrated or configured context. Circles are real RTX 5090 MTP-3 results: hydrated and online K6 at 185,600, K4 at 262,144. Stars have generation proof: online K5 at 206,400 on the 5090, and the context edition at 262,144 with MTP-3 and an 8.4 MP image cap under a 30.24 GiB engine budget; the latter's hard-limit 5090 rerun is pending." src="assets/context-frontier-light.svg">
|
| 60 |
</picture>
|
| 61 |
|
| 62 |
+
| build | download | resident | corrected v3 mean KLD | context profile | pick it when |
|
| 63 |
|---|---:|---:|---:|---:|---|
|
| 64 |
+
| [-hydrated](https://huggingface.co/malaiwah/Qwen3.8-27B-EXL3-K5K6-hydrated) | 21.61 GB | 20.31 GiB | **0.007172** | ~180k | fidelity first, smallest download |
|
| 65 |
+
| [-EXL3-K5K6](https://huggingface.co/malaiwah/Qwen3.8-27B-EXL3-K5K6) | 30.57 GB | 20.32 GiB | 0.007945 | ~180k | you want the attention width knob at launch |
|
| 66 |
+
| [-context](https://huggingface.co/malaiwah/Qwen3.8-27B-EXL3-K5K6-context) | 20.70 GB | **18.41 GiB** | 0.009459 | **262,144, MTP-3, 8.4 MP cap** | native window; hard-limit RTX 5090 check pending |
|
| 67 |
+
| [-K4](https://huggingface.co/malaiwah/Qwen3.8-27B-K4) | 28.31 GB | 17.89 GiB | 0.029679 | 262,144 | smallest footprint, native context without any overlay |
|
| 68 |
|
| 69 |
+
Official `Qwen/Qwen3.8-27B-FP8` is 28.51 GiB resident at 0.012798 on the same subset and runs
|
| 70 |
+
on stock vLLM, which none of these do.
|
| 71 |
|
| 72 |
## Recipe
|
| 73 |
|
|
|
|
| 117 |
| `Qwen/Qwen3.8-27B-FP8` | 28.51 GiB | 0.013126 | [0.00981, 0.01709] | 0.002343 | 96.22 % |
|
| 118 |
| `unsloth/Qwen3.8-27B-NVFP4` | 21.34 GiB | 0.094978 | [0.06858, 0.12688] | 0.012911 | 90.53 % |
|
| 119 |
|
| 120 |
+
**Overlap-corrected subset:** a later all-position 12-token scan found exact calibration
|
| 121 |
+
overlap in 2/41 source documents that the original fixed-stride scan missed. Conservatively
|
| 122 |
+
removing their nine contexts gives this build **0.007172**, the online-K6 sibling **0.007945**,
|
| 123 |
+
official FP8 **0.012798**, and NVFP4 **0.092727** over 127 contexts. No ordering changes.
|
| 124 |
+
|
| 125 |
Paired on identical contexts:
|
| 126 |
|
| 127 |
- versus the BF16-attention sibling: **−0.000751**, 95 % CI [−0.000977, −0.000572],
|
|
|
|
| 138 |
since official FP8 serves a BF16 head. Measured directly on **this** checkpoint with asymmetric
|
| 139 |
heads (reference through the true BF16 head, candidate through this build's dequantized K6
|
| 140 |
head): the head costs **+0.000125** (95 % CI [+0.000107, +0.000144], 9/136 contexts favour it),
|
| 141 |
+
so **as served this build is 0.007532** with 97.08 % top-1. On the overlap-corrected
|
| 142 |
+
127-context subset, the measured result is **0.007300** with 97.05 % top-1; the head increment
|
| 143 |
+
is +0.000128 (95 % CI [+0.000110, +0.000146], 8/127 contexts favour it). The original
|
| 144 |
+
as-served result is still 1.74x better than FP8's
|
| 145 |
body-only 0.013126.
|
| 146 |
|
| 147 |
**Weakest control:** live-versus-replayed logit qualification is 6.54e-04 on this harness,
|
|
|
|
| 150 |
direction, but treat the magnitude as a point estimate. The FP8 gap, at 7.6x the floor, is
|
| 151 |
not in question.
|
| 152 |
|
| 153 |
+
**Development-set caveat:** the recipe was chosen with the 136-context development suite
|
| 154 |
+
visible. The source-disjoint qualification below is the post-selection test; its later lexical
|
| 155 |
+
overlap correction is reported rather than hidden.
|
| 156 |
|
| 157 |
## Post-selection qualification
|
| 158 |
|
|
|
|
| 161 |
(context token hashes 0/160, document names 0/100, content hashes 0/100), partitioned by whole
|
| 162 |
source cluster, run **once**, with no recipe changed afterwards.
|
| 163 |
|
| 164 |
+
The original 42-context table used a fixed-stride character overlap scan. A later,
|
| 165 |
+
offset-independent scan found exact 12-token calibration overlap in four qualification source
|
| 166 |
+
documents. Applying the same conservative rule to every candidate — exclude every context from
|
| 167 |
+
any source document with even one hit — leaves **36 contexts / 24 clusters**:
|
| 168 |
+
|
| 169 |
| candidate | mean KLD | 95 % CI | top-1 | paired vs FP8 |
|
| 170 |
|---|---:|---|---:|---|
|
| 171 |
+
| [hydrated](https://huggingface.co/malaiwah/Qwen3.8-27B-EXL3-K5K6-hydrated) | **0.003093** | [0.002577, 0.003684] | 97.63 % | −0.002798, **36/36** |
|
| 172 |
+
| [K5/K6 online K6](https://huggingface.co/malaiwah/Qwen3.8-27B-EXL3-K5K6) | 0.003455 | [0.002916, 0.004060] | 97.50 % | −0.002436, **36/36** |
|
| 173 |
+
| [context edition](https://huggingface.co/malaiwah/Qwen3.8-27B-EXL3-K5K6-context) | 0.003990 | [0.003268, 0.004797] | 97.36 % | −0.001901, **36/36** |
|
| 174 |
+
| `Qwen/Qwen3.8-27B-FP8` | 0.005891 | [0.004901, 0.006985] | 96.72 % | — |
|
| 175 |
+
|
| 176 |
+
The correction changes no ordering or paired win: the three EXL3 builds remain 47 / 41 / 32 %
|
| 177 |
+
below FP8. The original 42-context figures and the candidate-independent correction are both
|
| 178 |
+
preserved in [docs/31](https://github.com/malaiwah/qwen38-27b-exl3/blob/main/docs/31-frozen-qualification.md).
|
| 179 |
+
Absolute magnitudes remain suite-specific.
|
| 180 |
+
|
| 181 |
+
## Downstream task retention
|
| 182 |
+
|
| 183 |
+
On 40 deterministic generated tasks (10 each arithmetic, executable builtins-only code,
|
| 184 |
+
exact-list instruction following and tool-call schema), BF16 and every comparator scored
|
| 185 |
+
40/40. This build had **zero regressions** and matched BF16's exact final-answer text on
|
| 186 |
+
**35/40**; all five differing answers still passed their contracts. Wilson 95 % lower bound
|
| 187 |
+
is 91.2 %. This is a transparent smoke suite, not a public leaderboard; full responses are in
|
| 188 |
+
the [run receipt](https://github.com/malaiwah/qwen38-27b-exl3/blob/main/receipts/tasks-v2-hydrated.json);
|
| 189 |
+
its extracted-value agreement field is superseded by the
|
| 190 |
+
[strict rescore](https://github.com/malaiwah/qwen38-27b-exl3/blob/main/receipts/task-retention-v2-strict-rescore.json).
|
| 191 |
|
| 192 |
## Context capacity
|
| 193 |
|
|
|
|
| 201 |
| K6 attention, seqs 8, util 0.95 | 187,050 tok / 6.71 GiB | **185,600 run** | stable, multimodal-safe |
|
| 202 |
| K6 attention, seqs 8, util 0.98 | 202,185 tok / 7.55 GiB | — | text fine, **a 3,264-token image OOMed** with 33 MiB free |
|
| 203 |
|
| 204 |
+
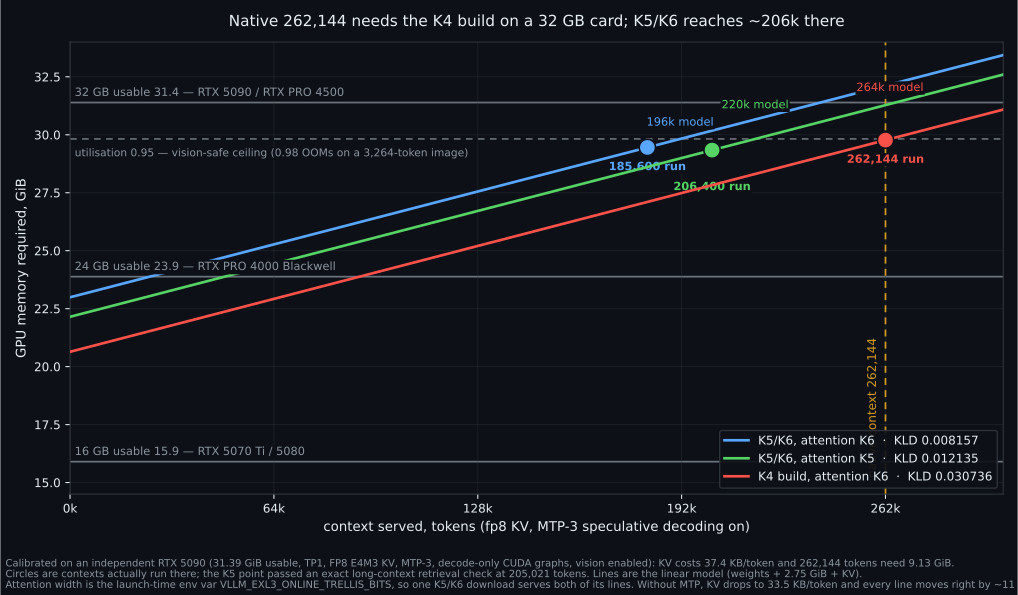
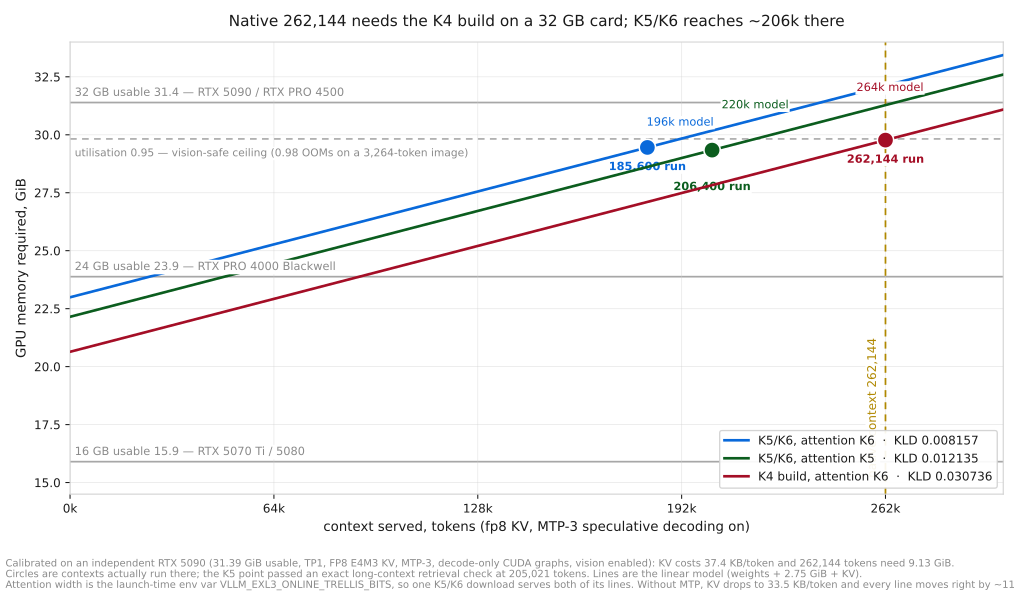
**Native 262,144 does not fit this checkpoint with MTP-3 on a 32 GB card.** The engine needs
|
| 205 |
+
**9.13 GiB** of KV (37.4 KB/token: 16 full-attention layers, 4 KV heads, head_dim 256; the
|
| 206 |
+
other 48 layers are Gated DeltaNet and hold per-sequence state). Without MTP that falls to
|
| 207 |
+
33.5 KB/token and buys ~11 % more length. The smaller
|
| 208 |
+
[`malaiwah/Qwen3.8-27B-K4`](https://huggingface.co/malaiwah/Qwen3.8-27B-K4) is the only family
|
| 209 |
+
member hardware-qualified at native length on a real 32 GB card (289,577-token capacity).
|
| 210 |
+
The context edition starts natively with MTP-3 and an 8.4 MP image ceiling under a capped
|
| 211 |
+
32 GB-equivalent engine budget, but its physical RTX 5090 rerun remains pending. On 48 GB and
|
| 212 |
+
larger, native context fits here at the best fidelity.
|
| 213 |
|
| 214 |
Keep utilisation at **0.95** if you serve images: 0.98 leaves no vision headroom.
|
| 215 |
|
|
|
|
| 221 |
## Serving
|
| 222 |
|
| 223 |
```bash
|
| 224 |
+
docker run --rm --gpus '"device=0"' --ipc host -p 127.0.0.1:8000:8000 \
|
| 225 |
-v /models:/models:ro \
|
| 226 |
--entrypoint /opt/venv/bin/vllm \
|
| 227 |
voipmonitor/vllm@sha256:820181fbbc975cd5291c411cda9771d58fecee1636d916f508f47230df20592b \
|
| 228 |
serve /models/Qwen3.8-27B-EXL3-K5K6-hydrated \
|
| 229 |
--served-model-name qwen38 --quantization exl3 --enforce-eager \
|
| 230 |
+
--quantization-config '{"linear":{"weight":"mxfp8"},"ignore":["re:.*visual\\..*","re:.*in_proj_a$","re:.*in_proj_b$","re:.*in_proj_ba$","re:.*mtp\\..*","lm_head"]}' \
|
| 231 |
--mm-processor-kwargs '{"truncation":false}' \
|
| 232 |
--reasoning-parser qwen3 --enable-auto-tool-choice --tool-call-parser qwen3_coder \
|
| 233 |
--max-model-len 8192 --gpu-memory-utilization 0.95 --max-num-seqs 8 \
|
| 234 |
--host 0.0.0.0 --port 8000
|
| 235 |
```
|
| 236 |
+
The container listens on all interfaces internally, but Docker publishes the port to host
|
| 237 |
+
loopback only. For remote clients, keep that binding and put an authenticated TLS proxy in
|
| 238 |
+
front; do not expose this unauthenticated generation endpoint directly.
|
| 239 |
+
|
| 240 |
|
| 241 |
No `VLLM_EXL3_ONLINE_TRELLIS_BITS`, no `VLLM_EXL3_ONLINE_CACHE_DIR`: nothing is encoded at
|
| 242 |
load, which is the point of this build. Three notes carry over from the sibling:
|
|
|
|
| 246 |
`model.`, so `re:.*visual\..*` matches while `re:.*\.visual\..*` silently does not, and the
|
| 247 |
wrong pattern **crashes** startup
|
| 248 |
([#311](https://github.com/local-inference-lab/vllm/issues/311), fixed by
|
| 249 |
+
[PR #312](https://github.com/local-inference-lab/vllm/pull/312)). The tested config ignores
|
| 250 |
+
`mtp.*` from the generic BF16 online overlay; EXL3-owned draft projections are selected
|
| 251 |
+
before that ignore check and still load from their serialized quantized tensors.
|
| 252 |
3. **`--mm-processor-kwargs '{"truncation":false}'` is required for images** whose expanded
|
| 253 |
token sequence exceeds 2,048, or requests fail with HTTP 400
|
| 254 |
([#313](https://github.com/local-inference-lab/vllm/issues/313)).
|
| 255 |
|
| 256 |
The command above is what the **pinned image runs unmodified**, so it is eager-only. CUDA-graph
|
| 257 |
+
decode (+46-50 %) and the measured reconstructed-prefill path (+113 %) need patches still
|
| 258 |
+
open upstream ([#314](https://github.com/local-inference-lab/vllm/pull/314),
|
| 259 |
+
[#316](https://github.com/local-inference-lab/vllm/pull/316), and
|
| 260 |
+
[#318](https://github.com/local-inference-lab/vllm/pull/318)); the sibling card carries the
|
| 261 |
+
exact one-module patch recipe and current sha256. No published image digest contains it.
|
| 262 |
|
| 263 |
## What is not verified
|
| 264 |
|
| 265 |
+
The deterministic downstream smoke passes 40/40 with zero BF16 regressions, but no public
|
| 266 |
+
task benchmark has run. Also unverified: real OCR/chart/document/video quality, long-context
|
| 267 |
+
retrieval or perplexity **for this build**, native-262K or YaRN-1M generation, multi-GPU or
|
| 268 |
+
TP>1, non-SM120 hardware, and quant-specific safety regression testing.
|
| 269 |
Throughput was not re-measured here: this build shares the sibling's kernels and resident
|
| 270 |
footprint, so its decode and prefill figures should carry over — that is an inference, not a
|
| 271 |
measurement.
|
| 272 |
|
| 273 |
+
Evaluation captures and reports for this build are published in the
|
| 274 |
+
[fidelity dataset](https://huggingface.co/datasets/malaiwah/qwen38-27b-fidelity-suite-v3),
|
| 275 |
+
so the row is independently recomputable without this checkpoint or a GPU.
|
|
|
|
|
|
|
| 276 |
|
| 277 |
## Machine-readable evidence
|
| 278 |
|
assets/context-frontier-dark.png
CHANGED

|
Git LFS Details
|

|
Git LFS Details
|
assets/context-frontier-dark.svg
CHANGED
|
|
assets/context-frontier-light.png
CHANGED

|
Git LFS Details
|

|
Git LFS Details
|
assets/context-frontier-light.svg
CHANGED
|
|
assets/context-per-card-dark.png
ADDED

|
Git LFS Details
|
assets/context-per-card-dark.svg
ADDED
|
assets/context-per-card-light.png
ADDED

|
Git LFS Details
|
assets/context-per-card-light.svg
ADDED
|
assets/fidelity-vs-size-dark.png
ADDED

|
Git LFS Details
|
assets/fidelity-vs-size-dark.svg
ADDED
|
assets/fidelity-vs-size-light.png
ADDED

|
Git LFS Details
|
assets/fidelity-vs-size-light.svg
ADDED
|
release-evidence.json
CHANGED
|
@@ -1,6 +1,7 @@
|
|
| 1 |
{
|
| 2 |
"schema": "qwen38-release-evidence/1",
|
| 3 |
"generated_utc": "2026-08-15T03:42:51Z",
|
|
|
|
| 4 |
"artifact": {
|
| 5 |
"hf_repo": "malaiwah/Qwen3.8-27B-EXL3-K5K6-hydrated",
|
| 6 |
"label": "K5/K6, attention serialized offline at K6",
|
|
@@ -45,7 +46,7 @@
|
|
| 45 |
"suite_token_sha256": "3f9d17f1b55f64872ad3ac19c8711654e09ba70b7ca14b0851525088fe735691",
|
| 46 |
"partition": "analysis",
|
| 47 |
"contexts": 136,
|
| 48 |
-
"scored_positions":
|
| 49 |
"shared_comparator_head": "BF16, identical for every candidate (body-only)",
|
| 50 |
"mean_kld": 0.007406422525617622,
|
| 51 |
"ci95": [
|
|
@@ -83,24 +84,59 @@
|
|
| 83 |
"bf16_control": "24/32, 0.0128"
|
| 84 |
}
|
| 85 |
},
|
| 86 |
-
"development_set_caveat": "Recipe selection saw
|
| 87 |
-
"captures_published":
|
| 88 |
"as_served": {
|
| 89 |
-
"
|
| 90 |
-
|
| 91 |
-
|
| 92 |
-
|
| 93 |
-
0.
|
| 94 |
-
0.
|
| 95 |
-
|
| 96 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 97 |
}
|
| 98 |
},
|
| 99 |
"serving": {
|
| 100 |
"note": "No online encoding: no VLLM_EXL3_ONLINE_TRELLIS_BITS, no cache directory. Eager on the pinned image."
|
| 101 |
},
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 102 |
"not_verified": [
|
| 103 |
-
"downstream
|
| 104 |
"multimodal quality beyond single image smoke tests",
|
| 105 |
"long-context accuracy beyond an external 205,021-token retrieval check",
|
| 106 |
"native 262,144 generation on this box",
|
|
|
|
| 1 |
{
|
| 2 |
"schema": "qwen38-release-evidence/1",
|
| 3 |
"generated_utc": "2026-08-15T03:42:51Z",
|
| 4 |
+
"amended_utc": "2026-08-15T12:27:32Z",
|
| 5 |
"artifact": {
|
| 6 |
"hf_repo": "malaiwah/Qwen3.8-27B-EXL3-K5K6-hydrated",
|
| 7 |
"label": "K5/K6, attention serialized offline at K6",
|
|
|
|
| 46 |
"suite_token_sha256": "3f9d17f1b55f64872ad3ac19c8711654e09ba70b7ca14b0851525088fe735691",
|
| 47 |
"partition": "analysis",
|
| 48 |
"contexts": 136,
|
| 49 |
+
"scored_positions": 278392,
|
| 50 |
"shared_comparator_head": "BF16, identical for every candidate (body-only)",
|
| 51 |
"mean_kld": 0.007406422525617622,
|
| 52 |
"ci95": [
|
|
|
|
| 84 |
"bf16_control": "24/32, 0.0128"
|
| 85 |
}
|
| 86 |
},
|
| 87 |
+
"development_set_caveat": "Recipe selection saw v3; source-disjoint v4 qualification is published. The conservative overlap-corrected v3 subset and v4 results are linked by amendments below.",
|
| 88 |
+
"captures_published": true,
|
| 89 |
"as_served": {
|
| 90 |
+
"original": {
|
| 91 |
+
"contexts": 136,
|
| 92 |
+
"scored_positions": 278392,
|
| 93 |
+
"mean_kld": 0.007531590572321231,
|
| 94 |
+
"top1_agreement": 0.9707822063852409,
|
| 95 |
+
"head_delta_mean_kld": 0.00012516804670361007,
|
| 96 |
+
"head_delta_ci95": [
|
| 97 |
+
0.00010680418990943814,
|
| 98 |
+
0.0001438008910763626
|
| 99 |
+
]
|
| 100 |
+
},
|
| 101 |
+
"overlap_corrected": {
|
| 102 |
+
"contexts": 127,
|
| 103 |
+
"scored_positions": 259969,
|
| 104 |
+
"mean_kld": 0.007300129113882429,
|
| 105 |
+
"top1_agreement": 0.9704657093730407,
|
| 106 |
+
"head_delta_mean_kld": 0.00012809525810428388,
|
| 107 |
+
"head_delta_ci95": [
|
| 108 |
+
0.00010955942052458132,
|
| 109 |
+
0.0001463054626847932
|
| 110 |
+
],
|
| 111 |
+
"contexts_favouring_quantized_head": 8
|
| 112 |
+
},
|
| 113 |
+
"method": "asymmetric heads: BF16 reference head versus this checkpoint's dequantized K6 head"
|
| 114 |
}
|
| 115 |
},
|
| 116 |
"serving": {
|
| 117 |
"note": "No online encoding: no VLLM_EXL3_ONLINE_TRELLIS_BITS, no cache directory. Eager on the pinned image."
|
| 118 |
},
|
| 119 |
+
"amendments": {
|
| 120 |
+
"fidelity_dataset_revision": "73252e77e96bbf5596484e29dd8041f9f38c95f1",
|
| 121 |
+
"overlap_corrected_v3": {
|
| 122 |
+
"path": "receipts/analysis-v3-contamination-corrected.json",
|
| 123 |
+
"sha256": "026fc453787eccef15879f29266489ba9ec04bbff59ab7e35827e92394480417"
|
| 124 |
+
},
|
| 125 |
+
"source_disjoint_v4": {
|
| 126 |
+
"path": "receipts/qualification-v4-contamination-corrected.json",
|
| 127 |
+
"sha256": "17148ed02713f426dcb4b7b69c8072a5eb8a9abd49bcbfcea585ca8e5c2f5ab3"
|
| 128 |
+
},
|
| 129 |
+
"task_run": {
|
| 130 |
+
"path": "receipts/tasks-v2-hydrated.json",
|
| 131 |
+
"sha256": "704b9c51f5e902a680f087e2eed00d51c6166d35461e667f0d6d7c5ce6d3aec4"
|
| 132 |
+
},
|
| 133 |
+
"task_strict_rescore": {
|
| 134 |
+
"path": "receipts/task-retention-v2-strict-rescore.json",
|
| 135 |
+
"sha256": "b1cddff1a9ae012a48ec0258096c3a258e652aef887fc9128d8665e62c867080"
|
| 136 |
+
}
|
| 137 |
+
},
|
| 138 |
"not_verified": [
|
| 139 |
+
"public downstream benchmark beyond the deterministic paired smoke",
|
| 140 |
"multimodal quality beyond single image smoke tests",
|
| 141 |
"long-context accuracy beyond an external 205,021-token retrieval check",
|
| 142 |
"native 262,144 generation on this box",
|