


Release Decision 1.0 Lex: typed decision specialist
Browse filesThis view is limited to 50 files because it contains too many changes. See raw diff
- .gitattributes +11 -34
- ARCHITECTURE.md +15 -0
- DISTRIBUTION_TERMS.md +7 -0
- EVALUATION.md +30 -0
- FINETUNING.md +30 -0
- LICENSE +21 -0
- LICENSES/Transformers-Apache-2.0.txt +203 -0
- LICENSES/gemma/GEMMA_PROHIBITED_USE_POLICY.html +84 -0
- LICENSES/gemma/GEMMA_TERMS.html +176 -0
- LICENSES/gemma/Notice +19 -0
- LICENSES/gemma/TOKENIZER_TERMS.md +7 -0
- LICENSING_STATUS.md +17 -0
- METHODS.md +11 -0
- NOTICE +82 -0
- NOTICE_SOURCES.json +229 -0
- PACKAGE_MANIFEST.json +376 -0
- README.md +73 -0
- TECHNICAL_VALIDATION.json +55 -0
- TRAINING_ATTRIBUTION.md +33 -0
- TRAINING_PROVENANCE.json +65 -0
- USAGE.md +31 -0
- VALIDATION.md +9 -0
- assets/architecture-atlas.pdf +3 -0
- assets/architecture.pdf +3 -0
- assets/architecture.png +3 -0
- assets/architecture.svg +259 -0
- assets/attention-geglu.pdf +3 -0
- assets/attention-geglu.png +3 -0
- assets/attention-geglu.svg +115 -0
- assets/candidate-readout.pdf +3 -0
- assets/candidate-readout.png +3 -0
- assets/candidate-readout.svg +121 -0
- assets/decision-lex-header.png +3 -0
- assets/residual-layers.pdf +3 -0
- assets/residual-layers.png +3 -0
- assets/residual-layers.svg +118 -0
- decision_finetune/__init__.py +1 -0
- decision_finetune/__main__.py +80 -0
- decision_finetune/data.py +139 -0
- decision_finetune/metrics.py +61 -0
- decision_finetune/run.py +237 -0
- decision_finetune/state.py +110 -0
- decision_inference/__init__.py +3 -0
- decision_inference/profile.py +55 -0
- decision_runtime/__init__.py +11 -0
- decision_runtime/_compat.py +20 -0
- decision_runtime/native.py +152 -0
- decision_runtime/training.py +310 -0
- examples/decisions.jsonl +3 -0
- examples/finetune.sh +21 -0
.gitattributes
CHANGED
|
@@ -1,35 +1,12 @@
|
|
| 1 |
-
*.7z filter=lfs diff=lfs merge=lfs -text
|
| 2 |
-
*.arrow filter=lfs diff=lfs merge=lfs -text
|
| 3 |
-
*.bin filter=lfs diff=lfs merge=lfs -text
|
| 4 |
-
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
| 5 |
-
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
| 6 |
-
*.ftz filter=lfs diff=lfs merge=lfs -text
|
| 7 |
-
*.gz filter=lfs diff=lfs merge=lfs -text
|
| 8 |
-
*.h5 filter=lfs diff=lfs merge=lfs -text
|
| 9 |
-
*.joblib filter=lfs diff=lfs merge=lfs -text
|
| 10 |
-
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
| 11 |
-
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
| 12 |
-
*.model filter=lfs diff=lfs merge=lfs -text
|
| 13 |
-
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
| 14 |
-
*.npy filter=lfs diff=lfs merge=lfs -text
|
| 15 |
-
*.npz filter=lfs diff=lfs merge=lfs -text
|
| 16 |
-
*.onnx filter=lfs diff=lfs merge=lfs -text
|
| 17 |
-
*.ot filter=lfs diff=lfs merge=lfs -text
|
| 18 |
-
*.parquet filter=lfs diff=lfs merge=lfs -text
|
| 19 |
-
*.pb filter=lfs diff=lfs merge=lfs -text
|
| 20 |
-
*.pickle filter=lfs diff=lfs merge=lfs -text
|
| 21 |
-
*.pkl filter=lfs diff=lfs merge=lfs -text
|
| 22 |
-
*.pt filter=lfs diff=lfs merge=lfs -text
|
| 23 |
-
*.pth filter=lfs diff=lfs merge=lfs -text
|
| 24 |
-
*.rar filter=lfs diff=lfs merge=lfs -text
|
| 25 |
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
| 26 |
-
|
| 27 |
-
|
| 28 |
-
|
| 29 |
-
|
| 30 |
-
|
| 31 |
-
|
| 32 |
-
|
| 33 |
-
|
| 34 |
-
|
| 35 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
| 2 |
+
native/tokenizer/tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
| 3 |
+
assets/architecture-atlas.pdf filter=lfs diff=lfs merge=lfs -text
|
| 4 |
+
assets/architecture.pdf filter=lfs diff=lfs merge=lfs -text
|
| 5 |
+
assets/architecture.png filter=lfs diff=lfs merge=lfs -text
|
| 6 |
+
assets/attention-geglu.pdf filter=lfs diff=lfs merge=lfs -text
|
| 7 |
+
assets/attention-geglu.png filter=lfs diff=lfs merge=lfs -text
|
| 8 |
+
assets/candidate-readout.pdf filter=lfs diff=lfs merge=lfs -text
|
| 9 |
+
assets/candidate-readout.png filter=lfs diff=lfs merge=lfs -text
|
| 10 |
+
assets/decision-lex-header.png filter=lfs diff=lfs merge=lfs -text
|
| 11 |
+
assets/residual-layers.pdf filter=lfs diff=lfs merge=lfs -text
|
| 12 |
+
assets/residual-layers.png filter=lfs diff=lfs merge=lfs -text
|
ARCHITECTURE.md
ADDED
|
@@ -0,0 +1,15 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Lex architecture
|
| 2 |
+
|
| 3 |
+
Lex fine-tunes Kai's 571,909,635-parameter encoder architecture. Three independently parameterized 22-layer paths serve Choice, Noul and Score. Each path has its own final normalization, two interaction layers and a candidate scorer; token embeddings and embedding normalization are shared.
|
| 4 |
+
|
| 5 |
+

|
| 6 |
+
|
| 7 |
+
A question and all of its candidate descriptions are encoded jointly with the context. Marker states supply scalar candidate scores, normalized over the valid candidates. A shared type embedding is added after each path's final normalization. Each needed encoder path processes the full padded batch; interaction heads gather rows of that type.
|
| 8 |
+
|
| 9 |
+

|
| 10 |
+
|
| 11 |
+
Choice returns a candidate and probabilities; Noul returns the probability of yes; Score returns the ordered distribution and its expected value. Candidate IDs preserve associations outside the token stream. Multiple questions use batches, with repeated context encoding.
|
| 12 |
+
|
| 13 |
+
The public API accepts complete packed inputs of at most 1,024 tokens per question. No field is silently truncated.
|
| 14 |
+
|
| 15 |
+
[Main SVG](assets/architecture.svg) · [Residual layers](assets/residual-layers.svg) · [Attention and GEGLU](assets/attention-geglu.svg) · [PDF atlas](assets/architecture-atlas.pdf)
|
DISTRIBUTION_TERMS.md
ADDED
|
@@ -0,0 +1,7 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Decision distribution terms
|
| 2 |
+
|
| 3 |
+
Decision's new code and model-weight contributions are provided under the included [MIT license](LICENSE). Retained third-party material remains subject to its original license and notices; the MIT grant does not replace those conditions.
|
| 4 |
+
|
| 5 |
+
The inherited tokenizer is distributed with the [Gemma Terms of Use](LICENSES/gemma/GEMMA_TERMS.html), including the incorporated [Gemma Prohibited Use Policy](LICENSES/gemma/GEMMA_PROHIBITED_USE_POLICY.html). By accessing, using or distributing the covered tokenizer material, you agree to comply with those terms and restrictions. Those documents are incorporated into this distribution agreement for that material. Redistributors must pass on the applicable agreement, restrictions and required notices, and identify their modifications as required by the upstream terms.
|
| 6 |
+
|
| 7 |
+
This provision concerns the inherited tokenizer material. It does not describe Decision's encoder weights as Gemma weights or replace the separate MIT and Apache-2.0 grants for other components. See [license scope](LICENSING_STATUS.md) and [NOTICE](NOTICE) for attribution and the component mapping.
|
EVALUATION.md
ADDED
|
@@ -0,0 +1,30 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Official typed-decisions TEST
|
| 2 |
+
|
| 3 |
+
The fixed final Lex checkpoint and the official `laya-typed-decisions` specialist were each evaluated once on the original 2,000 TEST decisions, from 400 state components. Both models support all 2,000 complete inputs within 1,024 tokens, their native windows and their untruncated official-default support. No TRAIN state component or full input overlaps this TEST support. The test contains four English workflows and 20 question schemas. This is not evidence of multilingual or unseen-schema generalization.
|
| 4 |
+
|
| 5 |
+
| Metric | Lex | Official specialist (shipped temperature) |
|
| 6 |
+
|---|---:|---:|
|
| 7 |
+
| Original-label hard accuracy | **78.15%** (1,563/2,000) | 76.60% (1,532/2,000) |
|
| 8 |
+
| Soft NLL | 0.961902 | **0.884390** |
|
| 9 |
+
| Mean soft Brier | 0.030858 | **0.018452** |
|
| 10 |
+
| Score RPS | 0.022994 | **0.015602** |
|
| 11 |
+
| Score expected-value MAE | 0.251408 | **0.242408** |
|
| 12 |
+
|
| 13 |
+
Lex's accuracy gain is 1.55 percentage points (31 decisions). The paired 95% interval is **[-0.20, +3.15125] percentage points**, which includes zero. The interval uses 2,000 state-component bootstrap samples, seed 20260921, stratified by each component's workflow set; complete components are retained. This supports a higher observed hard-accuracy point, not statistically significant or uniformly better performance. Probability metrics are worse for Lex in this comparison. No calibration was fitted.
|
| 14 |
+
|
| 15 |
+
| Type | Decisions | Lex accuracy | Official accuracy |
|
| 16 |
+
|---|---:|---:|---:|
|
| 17 |
+
| Choice | 600 | 74.00% | 73.33% |
|
| 18 |
+
| Noul | 600 | 84.67% | 85.67% |
|
| 19 |
+
| Score | 800 | 76.375% | 72.25% |
|
| 20 |
+
|
| 21 |
+
| Workflow | Decisions | Lex accuracy | Official accuracy |
|
| 22 |
+
|---|---:|---:|---:|
|
| 23 |
+
| Agent trace observability | 500 | 72.4% | 73.0% |
|
| 24 |
+
| Customer service | 500 | 79.6% | 76.4% |
|
| 25 |
+
| Invoice processing | 500 | 84.4% | 80.4% |
|
| 26 |
+
| Security incidents | 500 | 76.2% | 76.6% |
|
| 27 |
+
|
| 28 |
+
Hard accuracy uses the source's original semantic hard label. Choice and Score use the first maximum in supplied order; Noul uses `p_yes >= 0.5`. Soft NLL uses the explicitly normalized original soft label distribution and natural logarithms (probability floor 1e-12). Brier averages squared probability error over the valid candidates; ordinal Score RPS averages cumulative-distribution squared error over K−1 boundaries. Score MAE compares the predicted expected value against the original source score. The official raw-temperature accuracy is also 76.60%; raw soft NLL is 0.869598.
|
| 29 |
+
|
| 30 |
+
The frozen TEST parquet SHA256 is `4f294f218ea1da27f3efef936359389c62ea4d3973a41457732990f1d31b647c`. The actual saved-summary SHA256 is `1a21955b24be16cefa2963779e71edf4d6b5adcd14679fc438e6a87e3e604b88`. No TEST text, labels or predictions are redistributed. The annotations are synthetic/teacher-derived; accuracy does not certify operational safety or calibrated business utility.
|
FINETUNING.md
ADDED
|
@@ -0,0 +1,30 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Fine-tune on your data
|
| 2 |
+
|
| 3 |
+
The included CLI trains the existing Choice, Noul and Score paths without adding new parameters. It supports hard or soft labels, deterministic scheduling, full-input admission, DEV checkpoint selection and optimizer/RNG resume. Token embedding, embedding normalization and type embedding remain frozen. The other 486 parameter tensors are trainable when their type is present.
|
| 4 |
+
|
| 5 |
+
Provide your own TRAIN and DEV JSONL. The CLI rejects shared IDs, shared normalized full inputs and same-source components where supplied. It does not prove semantic independence; use an appropriate development split and do not train on a release/test set.
|
| 6 |
+
|
| 7 |
+
| Type | Target |
|
| 8 |
+
|---|---|
|
| 9 |
+
| Choice | `{"choice_id":"candidate-id"}` or `{"probabilities":[0.2,0.8]}` |
|
| 10 |
+
| Noul | `{"probability":0.8}`; hard labels are 0 or 1 |
|
| 11 |
+
| Score | `{"probabilities":[0.1,0.2,0.7]}` in increasing-value level order; hard labels are one-hot |
|
| 12 |
+
|
| 13 |
+
Every row retains `id`, full `state_text` and a complete typed `question`. Probability vectors sum to one. A scalar Score is not silently converted into a distribution.
|
| 14 |
+
|
| 15 |
+
```bash
|
| 16 |
+
TRAIN=/data/train.jsonl DEV=/data/dev.jsonl OUTPUT=/runs/my-decision \
|
| 17 |
+
ROCR_VISIBLE_DEVICES=0 bash examples/finetune.sh
|
| 18 |
+
```
|
| 19 |
+
|
| 20 |
+
`examples/finetune.sh` is the editable example configuration; it uses actual supported flags, not a nonexistent `--config` option. Its four-epoch recipe uses logical batch 64 / microbatch 8, BF16 autocast with FP32 parameters/loss, AdamW, encoder LR 2.5e-5 / head LR 1e-4, clip 1, CE plus 0.1 ordinal RPS for Score, and a cosine floor of 1e-6 after 10% warmup. Logical tails use their actual row count. These are example defaults, not a guarantee of improvement.
|
| 21 |
+
|
| 22 |
+
The default selector minimizes equal-type macro soft NLL at step 0 and epoch ends. The separate `--selection hard-accuracy` policy requires an explicit `hard_target_id` on every DEV row, uses row hard accuracy then soft NLL then the earlier step, and never derives hard gold from soft targets. Noul hard selection uses `p_yes >= .5`. Record the selector and cadence used in any model comparison; these defaults are starting points rather than a guarantee of task quality.
|
| 23 |
+
|
| 24 |
+
Successful runs export the selected native bundle and report its manifest in `COMPLETE.json`. Selecting step 0 means no adopted adaptation. Immutable checkpoints include model, AdamW and RNG state; allow substantial disk space. For an interrupted run, use exactly the same original arguments and output plus `--resume <checkpoint> --resume-sha256 <hash>`. Read `LATEST.json` for the last completely saved boundary. `--stop-after-step N` is an optional clean pause; it does not restart or shorten the LR horizon.
|
| 25 |
+
|
| 26 |
+
The included source underwent a bounded AMD continuous-versus-resume check and independent native reload. That interface evidence is separate from dataset quality or long training stability. Validate the quality of your selected model on an appropriately isolated evaluation set; no automatic release or adoption is performed.
|
| 27 |
+
|
| 28 |
+
## Lex checkpoint provenance
|
| 29 |
+
|
| 30 |
+
The editable example above is a downstream fine-tuning recipe, not the exact Lex release recipe. Lex was refit from Kai on all 6,000 original typed-decisions TRAIN decisions using eight epochs, fixed final step 750 and blended original hard/soft cross-entropy. It used no final-refit DEV selector, no warmup and no RPS term. See [METHODS.md](METHODS.md) and [TRAINING_PROVENANCE.json](TRAINING_PROVENANCE.json). The public CLI does not provide a named `blend50` switch; explicitly form normalized blended targets if using that objective. Reusing Lex as an initializer is a new experiment.
|
LICENSE
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
MIT License
|
| 2 |
+
|
| 3 |
+
Copyright (c) 2026 Decision Nano contributors
|
| 4 |
+
|
| 5 |
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
| 6 |
+
of this software and associated documentation files (the "Software"), to deal
|
| 7 |
+
in the Software without restriction, including without limitation the rights
|
| 8 |
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
| 9 |
+
copies of the Software, and to permit persons to whom the Software is
|
| 10 |
+
furnished to do so, subject to the following conditions:
|
| 11 |
+
|
| 12 |
+
The above copyright notice and this permission notice shall be included in all
|
| 13 |
+
copies or substantial portions of the Software.
|
| 14 |
+
|
| 15 |
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
| 16 |
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
| 17 |
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
| 18 |
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
| 19 |
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
| 20 |
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
| 21 |
+
SOFTWARE.
|
LICENSES/Transformers-Apache-2.0.txt
ADDED
|
@@ -0,0 +1,203 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
Copyright 2018- The Hugging Face team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Apache License
|
| 4 |
+
Version 2.0, January 2004
|
| 5 |
+
http://www.apache.org/licenses/
|
| 6 |
+
|
| 7 |
+
TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION
|
| 8 |
+
|
| 9 |
+
1. Definitions.
|
| 10 |
+
|
| 11 |
+
"License" shall mean the terms and conditions for use, reproduction,
|
| 12 |
+
and distribution as defined by Sections 1 through 9 of this document.
|
| 13 |
+
|
| 14 |
+
"Licensor" shall mean the copyright owner or entity authorized by
|
| 15 |
+
the copyright owner that is granting the License.
|
| 16 |
+
|
| 17 |
+
"Legal Entity" shall mean the union of the acting entity and all
|
| 18 |
+
other entities that control, are controlled by, or are under common
|
| 19 |
+
control with that entity. For the purposes of this definition,
|
| 20 |
+
"control" means (i) the power, direct or indirect, to cause the
|
| 21 |
+
direction or management of such entity, whether by contract or
|
| 22 |
+
otherwise, or (ii) ownership of fifty percent (50%) or more of the
|
| 23 |
+
outstanding shares, or (iii) beneficial ownership of such entity.
|
| 24 |
+
|
| 25 |
+
"You" (or "Your") shall mean an individual or Legal Entity
|
| 26 |
+
exercising permissions granted by this License.
|
| 27 |
+
|
| 28 |
+
"Source" form shall mean the preferred form for making modifications,
|
| 29 |
+
including but not limited to software source code, documentation
|
| 30 |
+
source, and configuration files.
|
| 31 |
+
|
| 32 |
+
"Object" form shall mean any form resulting from mechanical
|
| 33 |
+
transformation or translation of a Source form, including but
|
| 34 |
+
not limited to compiled object code, generated documentation,
|
| 35 |
+
and conversions to other media types.
|
| 36 |
+
|
| 37 |
+
"Work" shall mean the work of authorship, whether in Source or
|
| 38 |
+
Object form, made available under the License, as indicated by a
|
| 39 |
+
copyright notice that is included in or attached to the work
|
| 40 |
+
(an example is provided in the Appendix below).
|
| 41 |
+
|
| 42 |
+
"Derivative Works" shall mean any work, whether in Source or Object
|
| 43 |
+
form, that is based on (or derived from) the Work and for which the
|
| 44 |
+
editorial revisions, annotations, elaborations, or other modifications
|
| 45 |
+
represent, as a whole, an original work of authorship. For the purposes
|
| 46 |
+
of this License, Derivative Works shall not include works that remain
|
| 47 |
+
separable from, or merely link (or bind by name) to the interfaces of,
|
| 48 |
+
the Work and Derivative Works thereof.
|
| 49 |
+
|
| 50 |
+
"Contribution" shall mean any work of authorship, including
|
| 51 |
+
the original version of the Work and any modifications or additions
|
| 52 |
+
to that Work or Derivative Works thereof, that is intentionally
|
| 53 |
+
submitted to Licensor for inclusion in the Work by the copyright owner
|
| 54 |
+
or by an individual or Legal Entity authorized to submit on behalf of
|
| 55 |
+
the copyright owner. For the purposes of this definition, "submitted"
|
| 56 |
+
means any form of electronic, verbal, or written communication sent
|
| 57 |
+
to the Licensor or its representatives, including but not limited to
|
| 58 |
+
communication on electronic mailing lists, source code control systems,
|
| 59 |
+
and issue tracking systems that are managed by, or on behalf of, the
|
| 60 |
+
Licensor for the purpose of discussing and improving the Work, but
|
| 61 |
+
excluding communication that is conspicuously marked or otherwise
|
| 62 |
+
designated in writing by the copyright owner as "Not a Contribution."
|
| 63 |
+
|
| 64 |
+
"Contributor" shall mean Licensor and any individual or Legal Entity
|
| 65 |
+
on behalf of whom a Contribution has been received by Licensor and
|
| 66 |
+
subsequently incorporated within the Work.
|
| 67 |
+
|
| 68 |
+
2. Grant of Copyright License. Subject to the terms and conditions of
|
| 69 |
+
this License, each Contributor hereby grants to You a perpetual,
|
| 70 |
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
| 71 |
+
copyright license to reproduce, prepare Derivative Works of,
|
| 72 |
+
publicly display, publicly perform, sublicense, and distribute the
|
| 73 |
+
Work and such Derivative Works in Source or Object form.
|
| 74 |
+
|
| 75 |
+
3. Grant of Patent License. Subject to the terms and conditions of
|
| 76 |
+
this License, each Contributor hereby grants to You a perpetual,
|
| 77 |
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
| 78 |
+
(except as stated in this section) patent license to make, have made,
|
| 79 |
+
use, offer to sell, sell, import, and otherwise transfer the Work,
|
| 80 |
+
where such license applies only to those patent claims licensable
|
| 81 |
+
by such Contributor that are necessarily infringed by their
|
| 82 |
+
Contribution(s) alone or by combination of their Contribution(s)
|
| 83 |
+
with the Work to which such Contribution(s) was submitted. If You
|
| 84 |
+
institute patent litigation against any entity (including a
|
| 85 |
+
cross-claim or counterclaim in a lawsuit) alleging that the Work
|
| 86 |
+
or a Contribution incorporated within the Work constitutes direct
|
| 87 |
+
or contributory patent infringement, then any patent licenses
|
| 88 |
+
granted to You under this License for that Work shall terminate
|
| 89 |
+
as of the date such litigation is filed.
|
| 90 |
+
|
| 91 |
+
4. Redistribution. You may reproduce and distribute copies of the
|
| 92 |
+
Work or Derivative Works thereof in any medium, with or without
|
| 93 |
+
modifications, and in Source or Object form, provided that You
|
| 94 |
+
meet the following conditions:
|
| 95 |
+
|
| 96 |
+
(a) You must give any other recipients of the Work or
|
| 97 |
+
Derivative Works a copy of this License; and
|
| 98 |
+
|
| 99 |
+
(b) You must cause any modified files to carry prominent notices
|
| 100 |
+
stating that You changed the files; and
|
| 101 |
+
|
| 102 |
+
(c) You must retain, in the Source form of any Derivative Works
|
| 103 |
+
that You distribute, all copyright, patent, trademark, and
|
| 104 |
+
attribution notices from the Source form of the Work,
|
| 105 |
+
excluding those notices that do not pertain to any part of
|
| 106 |
+
the Derivative Works; and
|
| 107 |
+
|
| 108 |
+
(d) If the Work includes a "NOTICE" text file as part of its
|
| 109 |
+
distribution, then any Derivative Works that You distribute must
|
| 110 |
+
include a readable copy of the attribution notices contained
|
| 111 |
+
within such NOTICE file, excluding those notices that do not
|
| 112 |
+
pertain to any part of the Derivative Works, in at least one
|
| 113 |
+
of the following places: within a NOTICE text file distributed
|
| 114 |
+
as part of the Derivative Works; within the Source form or
|
| 115 |
+
documentation, if provided along with the Derivative Works; or,
|
| 116 |
+
within a display generated by the Derivative Works, if and
|
| 117 |
+
wherever such third-party notices normally appear. The contents
|
| 118 |
+
of the NOTICE file are for informational purposes only and
|
| 119 |
+
do not modify the License. You may add Your own attribution
|
| 120 |
+
notices within Derivative Works that You distribute, alongside
|
| 121 |
+
or as an addendum to the NOTICE text from the Work, provided
|
| 122 |
+
that such additional attribution notices cannot be construed
|
| 123 |
+
as modifying the License.
|
| 124 |
+
|
| 125 |
+
You may add Your own copyright statement to Your modifications and
|
| 126 |
+
may provide additional or different license terms and conditions
|
| 127 |
+
for use, reproduction, or distribution of Your modifications, or
|
| 128 |
+
for any such Derivative Works as a whole, provided Your use,
|
| 129 |
+
reproduction, and distribution of the Work otherwise complies with
|
| 130 |
+
the conditions stated in this License.
|
| 131 |
+
|
| 132 |
+
5. Submission of Contributions. Unless You explicitly state otherwise,
|
| 133 |
+
any Contribution intentionally submitted for inclusion in the Work
|
| 134 |
+
by You to the Licensor shall be under the terms and conditions of
|
| 135 |
+
this License, without any additional terms or conditions.
|
| 136 |
+
Notwithstanding the above, nothing herein shall supersede or modify
|
| 137 |
+
the terms of any separate license agreement you may have executed
|
| 138 |
+
with Licensor regarding such Contributions.
|
| 139 |
+
|
| 140 |
+
6. Trademarks. This License does not grant permission to use the trade
|
| 141 |
+
names, trademarks, service marks, or product names of the Licensor,
|
| 142 |
+
except as required for reasonable and customary use in describing the
|
| 143 |
+
origin of the Work and reproducing the content of the NOTICE file.
|
| 144 |
+
|
| 145 |
+
7. Disclaimer of Warranty. Unless required by applicable law or
|
| 146 |
+
agreed to in writing, Licensor provides the Work (and each
|
| 147 |
+
Contributor provides its Contributions) on an "AS IS" BASIS,
|
| 148 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
|
| 149 |
+
implied, including, without limitation, any warranties or conditions
|
| 150 |
+
of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
|
| 151 |
+
PARTICULAR PURPOSE. You are solely responsible for determining the
|
| 152 |
+
appropriateness of using or redistributing the Work and assume any
|
| 153 |
+
risks associated with Your exercise of permissions under this License.
|
| 154 |
+
|
| 155 |
+
8. Limitation of Liability. In no event and under no legal theory,
|
| 156 |
+
whether in tort (including negligence), contract, or otherwise,
|
| 157 |
+
unless required by applicable law (such as deliberate and grossly
|
| 158 |
+
negligent acts) or agreed to in writing, shall any Contributor be
|
| 159 |
+
liable to You for damages, including any direct, indirect, special,
|
| 160 |
+
incidental, or consequential damages of any character arising as a
|
| 161 |
+
result of this License or out of the use or inability to use the
|
| 162 |
+
Work (including but not limited to damages for loss of goodwill,
|
| 163 |
+
work stoppage, computer failure or malfunction, or any and all
|
| 164 |
+
other commercial damages or losses), even if such Contributor
|
| 165 |
+
has been advised of the possibility of such damages.
|
| 166 |
+
|
| 167 |
+
9. Accepting Warranty or Additional Liability. While redistributing
|
| 168 |
+
the Work or Derivative Works thereof, You may choose to offer,
|
| 169 |
+
and charge a fee for, acceptance of support, warranty, indemnity,
|
| 170 |
+
or other liability obligations and/or rights consistent with this
|
| 171 |
+
License. However, in accepting such obligations, You may act only
|
| 172 |
+
on Your own behalf and on Your sole responsibility, not on behalf
|
| 173 |
+
of any other Contributor, and only if You agree to indemnify,
|
| 174 |
+
defend, and hold each Contributor harmless for any liability
|
| 175 |
+
incurred by, or claims asserted against, such Contributor by reason
|
| 176 |
+
of your accepting any such warranty or additional liability.
|
| 177 |
+
|
| 178 |
+
END OF TERMS AND CONDITIONS
|
| 179 |
+
|
| 180 |
+
APPENDIX: How to apply the Apache License to your work.
|
| 181 |
+
|
| 182 |
+
To apply the Apache License to your work, attach the following
|
| 183 |
+
boilerplate notice, with the fields enclosed by brackets "[]"
|
| 184 |
+
replaced with your own identifying information. (Don't include
|
| 185 |
+
the brackets!) The text should be enclosed in the appropriate
|
| 186 |
+
comment syntax for the file format. We also recommend that a
|
| 187 |
+
file or class name and description of purpose be included on the
|
| 188 |
+
same "printed page" as the copyright notice for easier
|
| 189 |
+
identification within third-party archives.
|
| 190 |
+
|
| 191 |
+
Copyright [yyyy] [name of copyright owner]
|
| 192 |
+
|
| 193 |
+
Licensed under the Apache License, Version 2.0 (the "License");
|
| 194 |
+
you may not use this file except in compliance with the License.
|
| 195 |
+
You may obtain a copy of the License at
|
| 196 |
+
|
| 197 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 198 |
+
|
| 199 |
+
Unless required by applicable law or agreed to in writing, software
|
| 200 |
+
distributed under the License is distributed on an "AS IS" BASIS,
|
| 201 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 202 |
+
See the License for the specific language governing permissions and
|
| 203 |
+
limitations under the License.
|
LICENSES/gemma/GEMMA_PROHIBITED_USE_POLICY.html
ADDED
|
@@ -0,0 +1,84 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!doctype html>
|
| 2 |
+
<html lang="en"><meta charset="utf-8"><title>Gemma Prohibited Use Policy</title><body><h1>Gemma Prohibited Use Policy</h1><p>Official Google legal text, retrieved 2026-09-21T11:09:44.489495+00:00. Source: <a href="https://ai.google.dev/gemma/prohibited_use_policy">https://ai.google.dev/gemma/prohibited_use_policy</a>. Article markup preserved; website navigation omitted. This document is not the MIT license.</p><div class="devsite-article-body clearfix">
|
| 3 |
+
<p>
|
| 4 |
+
</p>
|
| 5 |
+
<p>Google reserves the right to update this Gemma Prohibited Use Policy from time
|
| 6 |
+
to time.</p>
|
| 7 |
+
<p>Last modified: February 21, 2024</p>
|
| 8 |
+
<p>You <strong>may not</strong> use nor allow others to use Gemma or Model Derivatives to:</p>
|
| 9 |
+
<ol>
|
| 10 |
+
<li>Generate any content, including the outputs or results generated by Gemma or
|
| 11 |
+
Model Derivatives, that infringes, misappropriates, or otherwise violates any
|
| 12 |
+
individual's or entity's rights (including, but not limited to rights in
|
| 13 |
+
copyrighted content).</li>
|
| 14 |
+
<li>Perform or facilitate dangerous, illegal, or malicious activities, including:
|
| 15 |
+
<ol>
|
| 16 |
+
<li>Facilitation or promotion of illegal activities or violations of law,
|
| 17 |
+
such as:
|
| 18 |
+
<ol>
|
| 19 |
+
<li>Promoting or generating content related to child sexual abuse or
|
| 20 |
+
exploitation;</li>
|
| 21 |
+
<li>Promoting or facilitating sale of, or providing instructions for
|
| 22 |
+
synthesizing or accessing, illegal substances, goods, or services;</li>
|
| 23 |
+
<li>Facilitating or encouraging users to commit any type of crimes; or</li>
|
| 24 |
+
<li>Promoting or generating violent extremism or terrorist content.</li>
|
| 25 |
+
</ol></li>
|
| 26 |
+
<li>Engagement in the illegal or unlicensed practice of any vocation or
|
| 27 |
+
profession including, but not limited to, legal, medical, accounting, or
|
| 28 |
+
financial professional practices.</li>
|
| 29 |
+
<li>Abuse, harm, interference, or disruption of services (or enable others to
|
| 30 |
+
do the same), such as:
|
| 31 |
+
<ol>
|
| 32 |
+
<li>Promoting or facilitating the generation or distribution of spam; or</li>
|
| 33 |
+
<li>Generating content for deceptive or fraudulent activities, scams,
|
| 34 |
+
phishing, or malware.</li>
|
| 35 |
+
</ol></li>
|
| 36 |
+
<li>Attempts to override or circumvent safety filters or intentionally drive
|
| 37 |
+
Gemma or Model Derivatives to act in a manner that contravenes this Gemma
|
| 38 |
+
Prohibited Use Policy.</li>
|
| 39 |
+
<li>Generation of content that may harm or promote the harm of individuals or
|
| 40 |
+
a group, such as:
|
| 41 |
+
<ol>
|
| 42 |
+
<li>Generating content that promotes or encourages hatred;</li>
|
| 43 |
+
<li>Facilitating methods of harassment or bullying to intimidate, abuse,
|
| 44 |
+
or insult others;</li>
|
| 45 |
+
<li>Generating content that facilitates, promotes, or incites violence;</li>
|
| 46 |
+
<li>Generating content that facilitates, promotes, or encourages self
|
| 47 |
+
harm;</li>
|
| 48 |
+
<li>Generating personally identifying information for distribution or
|
| 49 |
+
other harms;</li>
|
| 50 |
+
<li>Tracking or monitoring people without their consent;</li>
|
| 51 |
+
<li>Generating content that may have unfair or adverse impacts on people,
|
| 52 |
+
particularly impacts related to sensitive or protected
|
| 53 |
+
characteristics; or</li>
|
| 54 |
+
<li>Generating, gathering, processing, or inferring sensitive personal or
|
| 55 |
+
private information about individuals without obtaining all rights,
|
| 56 |
+
authorizations, and consents required by applicable laws.</li>
|
| 57 |
+
</ol></li>
|
| 58 |
+
</ol></li>
|
| 59 |
+
<li>Generate and distribute content intended to misinform, misrepresent or
|
| 60 |
+
mislead, including:
|
| 61 |
+
<ol>
|
| 62 |
+
<li>Misrepresentation of the provenance of generated content by claiming
|
| 63 |
+
content was created by a human, or represent generated content as
|
| 64 |
+
original works, in order to deceive;</li>
|
| 65 |
+
<li>Generation of content that impersonates an individual (living or dead)
|
| 66 |
+
without explicit disclosure, in order to deceive;</li>
|
| 67 |
+
<li>Misleading claims of expertise or capability made particularly in
|
| 68 |
+
sensitive areas (e.g. health, finance, government services, or legal);</li>
|
| 69 |
+
<li>Making automated decisions in domains that affect material or individual
|
| 70 |
+
rights or well-being (e.g., finance, legal, employment, healthcare,
|
| 71 |
+
housing, insurance, and social welfare);</li>
|
| 72 |
+
<li>Generation of defamatory content, including defamatory statements,
|
| 73 |
+
images, or audio content; or</li>
|
| 74 |
+
<li>Engaging in the unauthorized or unlicensed practice of any profession
|
| 75 |
+
including, but not limited to, financial, legal, medical/health, or
|
| 76 |
+
related professional practices.</li>
|
| 77 |
+
</ol></li>
|
| 78 |
+
<li>Generate sexually explicit content, including content created for the
|
| 79 |
+
purposes of pornography or sexual gratification (e.g. sexual chatbots). Note
|
| 80 |
+
that this does not include content created for scientific, educational,
|
| 81 |
+
documentary, or artistic purposes.</li>
|
| 82 |
+
</ol>
|
| 83 |
+
<link data-page-link="" href="https://fonts.googleapis.com/css2?family=Google+Symbols:opsz,wght,FILL,GRAD@20..48,100..700,0..1,-50..200" rel="stylesheet"/>
|
| 84 |
+
</div></body></html>
|
LICENSES/gemma/GEMMA_TERMS.html
ADDED
|
@@ -0,0 +1,176 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!doctype html>
|
| 2 |
+
<html lang="en"><meta charset="utf-8"><title>Gemma Terms of Use</title><body><h1>Gemma Terms of Use</h1><p>Official Google legal text, retrieved 2026-09-21T11:09:43.368595+00:00. Source: <a href="https://ai.google.dev/gemma/terms">https://ai.google.dev/gemma/terms</a>. Article markup preserved; website navigation omitted. This document is not the MIT license.</p><div class="devsite-article-body clearfix">
|
| 3 |
+
<p>
|
| 4 |
+
</p>
|
| 5 |
+
<p>The terms below apply to Gemma models listed in the Appendix at bottom of this page. For Gemma 4 terms, see the <a href="https://ai.google.dev/gemma/apache_2">Gemma 4 license</a>.</p>
|
| 6 |
+
<p>Last modified: April 1, 2026</p>
|
| 7 |
+
<p>By using, reproducing, modifying, distributing, performing or displaying any
|
| 8 |
+
portion or element of Gemma, Model Derivatives including via any Hosted Service,
|
| 9 |
+
(each as defined below) (collectively, the "<strong>Gemma Services</strong>") or otherwise
|
| 10 |
+
accepting the terms of this Agreement, you agree to be bound by this Agreement.</p>
|
| 11 |
+
<h2 data-text="Section 1: DEFINITIONS" id="section-1:" tabindex="-1">Section 1: DEFINITIONS</h2>
|
| 12 |
+
<h3 data-text="1.1 Definitions" id="1.1-definitions" tabindex="-1">1.1 Definitions</h3>
|
| 13 |
+
<p>(a) "<strong>Agreement</strong>" or "<strong>Gemma Terms of Use</strong>" means these terms and conditions
|
| 14 |
+
that govern the use, reproduction, Distribution or modification of the Gemma
|
| 15 |
+
Services and any terms and conditions incorporated by reference.</p>
|
| 16 |
+
<p>(b) "<strong>Distribution</strong>" or "<strong>Distribute</strong>" means any transmission, publication,
|
| 17 |
+
or other sharing of Gemma or Model Derivatives to a third party, including by
|
| 18 |
+
providing or making Gemma or its functionality available as a hosted service via
|
| 19 |
+
API, web access, or any other electronic or remote means ("<strong>Hosted Service</strong>").</p>
|
| 20 |
+
<p>(c) "<strong>Gemma</strong>" means the set of machine learning language models, trained model
|
| 21 |
+
weights and parameters identified in the <a href="#appendix">Appendix</a>,
|
| 22 |
+
regardless of the source that you obtained it from.</p>
|
| 23 |
+
<p>(d) "<strong>Google</strong>" means Google LLC.</p>
|
| 24 |
+
<p>(e) "<strong>Model Derivatives</strong>" means all (i) modifications to Gemma, (ii) works based
|
| 25 |
+
on Gemma, or (iii) any other machine learning model which is created by transfer
|
| 26 |
+
of patterns of the weights, parameters, operations, or Output of Gemma, to that
|
| 27 |
+
model in order to cause that model to perform similarly to Gemma, including
|
| 28 |
+
distillation methods that use intermediate data representations or methods based
|
| 29 |
+
on the generation of synthetic data Outputs by Gemma for training that model.
|
| 30 |
+
For clarity, Outputs are not deemed Model Derivatives.</p>
|
| 31 |
+
<p>(f) "<strong>Output</strong>" means the information content output of Gemma or a Model
|
| 32 |
+
Derivative that results from operating or otherwise using Gemma or the Model
|
| 33 |
+
Derivative, including via a Hosted Service.</p>
|
| 34 |
+
<h3 data-text="1.2" id="1.2" tabindex="-1">1.2</h3>
|
| 35 |
+
<p>As used in this Agreement, "<strong>including</strong>" means
|
| 36 |
+
"<strong>including without limitation</strong>".</p>
|
| 37 |
+
<h2 data-text="Section 2: ELIGIBILITY AND USAGE" id="section-2:" tabindex="-1">Section 2: ELIGIBILITY AND USAGE</h2>
|
| 38 |
+
<h3 data-text="2.1 Eligibility" id="2.1-eligibility" tabindex="-1">2.1 Eligibility</h3>
|
| 39 |
+
<p>You represent and warrant that you have the legal capacity to enter into this
|
| 40 |
+
Agreement (including being of sufficient age of consent). If you are accessing
|
| 41 |
+
or using any of the Gemma Services for or on behalf of a legal entity, (a) you
|
| 42 |
+
are entering into this Agreement on behalf of yourself and that legal entity,
|
| 43 |
+
(b) you represent and warrant that you have the authority to act on behalf of
|
| 44 |
+
and bind that entity to this Agreement and (c) references to "<strong>you</strong>" or
|
| 45 |
+
"<strong>your</strong>" in the remainder of this Agreement refers to both you (as an
|
| 46 |
+
individual) and that entity.</p>
|
| 47 |
+
<h3 data-text="2.2 Use" id="2.2-use" tabindex="-1">2.2 Use</h3>
|
| 48 |
+
<p>You may use, reproduce, modify, Distribute, perform or display any of the Gemma
|
| 49 |
+
Services only in accordance with the terms of this Agreement, and must not
|
| 50 |
+
violate (or encourage or permit anyone else to violate) any term of this
|
| 51 |
+
Agreement.</p>
|
| 52 |
+
<h2 data-text="Section 3: DISTRIBUTION AND RESTRICTIONS" id="section-3:" tabindex="-1">Section 3: DISTRIBUTION AND RESTRICTIONS</h2>
|
| 53 |
+
<h3 data-text="3.1 Distribution and Redistribution" id="3.1-distribution" tabindex="-1">3.1 Distribution and Redistribution</h3>
|
| 54 |
+
<p>You may reproduce or Distribute copies of Gemma or Model Derivatives if you meet
|
| 55 |
+
all of the following conditions:</p>
|
| 56 |
+
<ol>
|
| 57 |
+
<li>You must include the use restrictions referenced in Section 3.2 as an
|
| 58 |
+
enforceable provision in any agreement (e.g., license agreement, terms of use,
|
| 59 |
+
etc.) governing the use and/or distribution of Gemma or Model Derivatives and
|
| 60 |
+
you must provide notice to subsequent users you Distribute to that Gemma or
|
| 61 |
+
Model Derivatives are subject to the use restrictions in Section 3.2.</li>
|
| 62 |
+
<li>You must provide all third party recipients of Gemma or Model Derivatives a
|
| 63 |
+
copy of this Agreement.</li>
|
| 64 |
+
<li>You must cause any modified files to carry prominent notices stating that you
|
| 65 |
+
modified the files.</li>
|
| 66 |
+
<li>All Distributions (other than through a Hosted Service) must be accompanied
|
| 67 |
+
by a "<strong>Notice</strong>" text file that contains the following notice:
|
| 68 |
+
"<strong>Gemma is provided under and subject to the Gemma Terms of Use found at ai.google.dev/gemma/terms</strong>".</li>
|
| 69 |
+
</ol>
|
| 70 |
+
<p>You may add your own intellectual property statement to your modifications and,
|
| 71 |
+
except as set forth in this Section, may provide additional or different terms
|
| 72 |
+
and conditions for use, reproduction, or Distribution of your modifications, or
|
| 73 |
+
for any such Model Derivatives as a whole, provided your use, reproduction,
|
| 74 |
+
modification, Distribution, performance, and display of Gemma otherwise complies
|
| 75 |
+
with the terms and conditions of this Agreement. Any additional or different
|
| 76 |
+
terms and conditions you impose must not conflict with the terms of this
|
| 77 |
+
Agreement.</p>
|
| 78 |
+
<h3 data-text="3.2 Use Restrictions" id="3.2-use" tabindex="-1">3.2 Use Restrictions</h3>
|
| 79 |
+
<p>You must not use any of the Gemma Services:</p>
|
| 80 |
+
<ol>
|
| 81 |
+
<li>for the restricted uses set forth in the Gemma Prohibited Use Policy at
|
| 82 |
+
<a href="https://ai.google.dev/gemma/prohibited_use_policy">ai.google.dev/gemma/prohibited_use_policy</a>
|
| 83 |
+
("<strong>Prohibited Use Policy</strong>"), which is hereby incorporated by reference into
|
| 84 |
+
this Agreement; or</li>
|
| 85 |
+
<li>in violation of applicable laws and regulations.</li>
|
| 86 |
+
</ol>
|
| 87 |
+
<p>To the maximum extent permitted by law, Google reserves the right to restrict
|
| 88 |
+
(remotely or otherwise) usage of any of the Gemma Services that Google
|
| 89 |
+
reasonably believes are in violation of this Agreement.</p>
|
| 90 |
+
<h3 data-text="3.3 Generated Output" id="3.3-generated" tabindex="-1">3.3 Generated Output</h3>
|
| 91 |
+
<p>Google claims no rights in Outputs you generate using Gemma. You and your users
|
| 92 |
+
are solely responsible for Outputs and their subsequent uses.</p>
|
| 93 |
+
<h2 data-text="Section 4: ADDITIONAL PROVISIONS" id="section-4:" tabindex="-1">Section 4: ADDITIONAL PROVISIONS</h2>
|
| 94 |
+
<h3 data-text="4.1 Updates" id="4.1-updates" tabindex="-1">4.1 Updates</h3>
|
| 95 |
+
<p>Google may update Gemma from time to time.</p>
|
| 96 |
+
<h3 data-text="4.2 Trademarks" id="4.2-trademarks" tabindex="-1">4.2 Trademarks</h3>
|
| 97 |
+
<p>Nothing in this Agreement grants you any rights to use Google's trademarks,
|
| 98 |
+
trade names, logos or to otherwise suggest endorsement or misrepresent the
|
| 99 |
+
relationship between you and Google. Google reserves any rights not expressly
|
| 100 |
+
granted herein.</p>
|
| 101 |
+
<h3 data-text="4.3 DISCLAIMER OF WARRANTY" id="4.3-disclaimer" tabindex="-1">4.3 DISCLAIMER OF WARRANTY</h3>
|
| 102 |
+
<p>UNLESS REQUIRED BY APPLICABLE LAW, THE GEMMA SERVICES, AND OUTPUTS, ARE PROVIDED
|
| 103 |
+
ON AN "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, EITHER
|
| 104 |
+
EXPRESS OR IMPLIED, INCLUDING ANY WARRANTIES OR CONDITIONS OF TITLE,
|
| 105 |
+
NON-INFRINGEMENT, MERCHANTABILITY, OR FITNESS FOR A PARTICULAR PURPOSE. YOU ARE
|
| 106 |
+
SOLELY RESPONSIBLE FOR DETERMINING THE APPROPRIATENESS OF USING, REPRODUCING,
|
| 107 |
+
MODIFYING, PERFORMING, DISPLAYING OR DISTRIBUTING ANY OF THE GEMMA SERVICES
|
| 108 |
+
OR OUTPUTS AND ASSUME ANY AND ALL RISKS ASSOCIATED WITH YOUR USE OR DISTRIBUTION
|
| 109 |
+
OF ANY OF THE GEMMA SERVICES OR OUTPUTS AND YOUR EXERCISE OF RIGHTS AND
|
| 110 |
+
PERMISSIONS UNDER THIS AGREEMENT.</p>
|
| 111 |
+
<h3 data-text="4.4 LIMITATION OF LIABILITY" id="4.4-limitation" tabindex="-1">4.4 LIMITATION OF LIABILITY</h3>
|
| 112 |
+
<p>TO THE FULLEST EXTENT PERMITTED BY APPLICABLE LAW, IN NO EVENT AND UNDER NO
|
| 113 |
+
LEGAL THEORY, WHETHER IN TORT (INCLUDING NEGLIGENCE), PRODUCT LIABILITY,
|
| 114 |
+
CONTRACT, OR OTHERWISE, UNLESS REQUIRED BY APPLICABLE LAW, SHALL GOOGLE OR ITS
|
| 115 |
+
AFFILIATES BE LIABLE TO YOU FOR DAMAGES, INCLUDING ANY DIRECT, INDIRECT,
|
| 116 |
+
SPECIAL, INCIDENTAL, EXEMPLARY, CONSEQUENTIAL, OR PUNITIVE DAMAGES, OR LOST
|
| 117 |
+
PROFITS OF ANY KIND ARISING FROM THIS AGREEMENT OR RELATED TO, ANY OF THE GEMMA
|
| 118 |
+
SERVICES OR OUTPUTS EVEN IF GOOGLE OR ITS AFFILIATES HAVE BEEN ADVISED OF THE
|
| 119 |
+
POSSIBILITY OF SUCH DAMAGES.</p>
|
| 120 |
+
<h3 data-text="4.5 Term, Termination, and Survival" id="4.5-term," tabindex="-1">4.5 Term, Termination, and Survival</h3>
|
| 121 |
+
<p>The term of this Agreement will commence upon your acceptance of this Agreement
|
| 122 |
+
(including acceptance by your use, modification, or Distribution, reproduction,
|
| 123 |
+
performance or display of any portion or element of the Gemma Services) and will
|
| 124 |
+
continue in full force and effect until terminated in accordance with the terms
|
| 125 |
+
of this Agreement. Google may terminate this Agreement if you are in breach of
|
| 126 |
+
any term of this Agreement. Upon termination of this Agreement, you must delete
|
| 127 |
+
and cease use and Distribution of all copies of Gemma and Model Derivatives in
|
| 128 |
+
your possession or control. Sections 1, 2.1, 3.3, 4.2 to 4.9 shall survive the
|
| 129 |
+
termination of this Agreement.</p>
|
| 130 |
+
<h3 data-text="4.6 Governing Law and Jurisdiction" id="4.6-governing" tabindex="-1">4.6 Governing Law and Jurisdiction</h3>
|
| 131 |
+
<p>This Agreement will be governed by the laws of the State of California without
|
| 132 |
+
regard to choice of law principles. The UN Convention on Contracts for the
|
| 133 |
+
International Sale of Goods does not apply to this Agreement. The state and
|
| 134 |
+
federal courts of Santa Clara County, California shall have exclusive
|
| 135 |
+
jurisdiction of any dispute arising out of this Agreement.</p>
|
| 136 |
+
<h3 data-text="4.7 Severability" id="4.7-severability" tabindex="-1">4.7 Severability</h3>
|
| 137 |
+
<p>If any provision of this Agreement is held to be invalid, illegal or
|
| 138 |
+
unenforceable, the remaining provisions shall be unaffected thereby and remain
|
| 139 |
+
valid as if such provision had not been set forth herein.</p>
|
| 140 |
+
<h3 data-text="4.8 Entire Agreement" id="4.8-entire" tabindex="-1">4.8 Entire Agreement</h3>
|
| 141 |
+
<p>This Agreement states all the terms agreed between the parties and supersedes
|
| 142 |
+
all other agreements between the parties as of the date of acceptance relating
|
| 143 |
+
to its subject matter.</p>
|
| 144 |
+
<h3 data-text="4.9 No Waiver" id="4.9-no" tabindex="-1">4.9 No Waiver</h3>
|
| 145 |
+
<p>Google will not be treated as having waived any rights by not exercising (or
|
| 146 |
+
delaying the exercise of) any rights under this Agreement.</p>
|
| 147 |
+
<h2 data-text="Appendix" id="appendix" tabindex="-1">Appendix</h2>
|
| 148 |
+
<ul>
|
| 149 |
+
<li><a href="https://ai.google.dev/gemma/docs/core/model_card">Gemma 1</a></li>
|
| 150 |
+
<li><a href="https://ai.google.dev/gemma/docs/core/model_card">Gemma 1.1</a></li>
|
| 151 |
+
<li><a href="https://ai.google.dev/gemma/docs/core/model_card_2">Gemma 2</a></li>
|
| 152 |
+
<li><a href="https://ai.google.dev/gemma/docs/core/model_card_3">Gemma 3</a></li>
|
| 153 |
+
<li><a href="https://ai.google.dev/gemma/docs/3n">Gemma 3n</a></li>
|
| 154 |
+
<li><a href="https://ai.google.dev/gemma/docs/functiongemma">FunctionGemma</a></li>
|
| 155 |
+
<li><a href="https://ai.google.dev/gemma/docs/embeddinggemma">EmbeddingGemma</a></li>
|
| 156 |
+
<li><a href="https://ai.google.dev/gemma/docs/paligemma/model-card">PaliGemma</a></li>
|
| 157 |
+
<li><a href="https://ai.google.dev/gemma/docs/paligemma/model-card-2">PaliGemma 2</a></li>
|
| 158 |
+
<li><a href="https://ai.google.dev/gemma/docs/shieldgemma/model_card">ShieldGemma</a></li>
|
| 159 |
+
<li><a href="https://ai.google.dev/gemma/docs/shieldgemma/model_card_2">ShieldGemma 2</a></li>
|
| 160 |
+
<li><a href="https://ai.google.dev/gemma/docs/codegemma/model_card">CodeGemma</a></li>
|
| 161 |
+
<li><a href="https://ai.google.dev/gemma/docs/codegemma/model_card">CodeGemma 1.1</a></li>
|
| 162 |
+
<li><a href="https://huggingface.co/google/gemma-2-2b-jpn-it">Gemma 2 JPN</a></li>
|
| 163 |
+
<li><a href="https://www.kaggle.com/models/google/datagemma-rig">DataGemma RIG</a></li>
|
| 164 |
+
<li><a href="https://www.kaggle.com/models/google/datagemma-rag">DataGemma RAG</a></li>
|
| 165 |
+
<li><a href="https://ai.google.dev/gemma/docs/recurrentgemma/model_card">RecurrentGemma</a></li>
|
| 166 |
+
<li><a href="https://ai.google.dev/gemma/docs/gemma_scope">Gemma Scope</a></li>
|
| 167 |
+
<li><a href="https://ai.google.dev/gemma/docs/gemma-aps">Gemma-APS</a></li>
|
| 168 |
+
<li><a href="https://www.kaggle.com/models/google/t5gemma">T5Gemma</a></li>
|
| 169 |
+
<li><a href="https://www.kaggle.com/models/google/vaultgemma">VaultGemma</a></li>
|
| 170 |
+
<li><a href="https://www.kaggle.com/models/google/functiongemma">FunctionGemma</a></li>
|
| 171 |
+
<li><a href="https://www.kaggle.com/models/google/t5gemma-2">T5Gemma 2</a></li>
|
| 172 |
+
<li><a href="https://www.kaggle.com/models/google/translategemma">TranslateGemma</a></li>
|
| 173 |
+
</ul>
|
| 174 |
+
<aside class="note"><strong>Note:</strong><span> Previous versions of these Terms are <a href="https://ai.google.dev/gemma/terms-archive">archived here</a>.</span></aside>
|
| 175 |
+
<link data-page-link="" href="https://fonts.googleapis.com/css2?family=Google+Symbols:opsz,wght,FILL,GRAD@20..48,100..700,0..1,-50..200" rel="stylesheet"/>
|
| 176 |
+
</div></body></html>
|
LICENSES/gemma/Notice
ADDED
|
@@ -0,0 +1,19 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
Gemma is provided under and subject to the Gemma Terms of Use found at ai.google.dev/gemma/terms
|
| 2 |
+
|
| 3 |
+
Tokenizer provenance for Decision-1.0-Kai
|
| 4 |
+
|
| 5 |
+
The tokenizer payload is inherited from Vela-1.0-Encoder-307M, whose base
|
| 6 |
+
model is mmBERT. The mmBERT author configuration identifies google/gemma-2-9b
|
| 7 |
+
as its tokenizer source. The upstream tokenizer terms are preserved for
|
| 8 |
+
applicable inherited material; the project's MIT grant does not replace them.
|
| 9 |
+
|
| 10 |
+
These tokenizer files are redistributed unchanged from the pinned Vela
|
| 11 |
+
payload. This statement does not assert that Vela's files are byte-identical
|
| 12 |
+
to Google's original files, or that Kai's encoder weights are Gemma weights.
|
| 13 |
+
No independent tokenizer-specific MIT grant or Google exception was located.
|
| 14 |
+
If any tokenizer file is subsequently modified, prominently identify that
|
| 15 |
+
modification and preserve the original terms and notices.
|
| 16 |
+
|
| 17 |
+
See GEMMA_TERMS.html, GEMMA_PROHIBITED_USE_POLICY.html and TOKENIZER_TERMS.md.
|
| 18 |
+
This supplement does not replace the package's existing MIT LICENSE,
|
| 19 |
+
third-party NOTICE, or Transformers Apache-2.0 license text.
|
LICENSES/gemma/TOKENIZER_TERMS.md
ADDED
|
@@ -0,0 +1,7 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Inherited tokenizer terms
|
| 2 |
+
|
| 3 |
+
This package contains tokenizer material inherited through Vela and mmBERT from the Gemma tokenizer. This file preserves the applicable upstream conditions; it does not relicense Google's material under MIT or assert that Kai's separately trained encoder weights are Gemma weights.
|
| 4 |
+
|
| 5 |
+
As a condition of using or redistributing the included Gemma-origin material, you must comply with the [Gemma Terms of Use](GEMMA_TERMS.html), including Section 3.2 and the [Gemma Prohibited Use Policy](GEMMA_PROHIBITED_USE_POLICY.html), which are incorporated into these terms. You must not use, or permit others to use, that material in violation of those restrictions or applicable law. On further distribution, provide recipients these terms and Google's complete agreement and preserve the accompanying `Notice`. Prominently identify any modifications to covered files. Nothing in the project's MIT license removes these obligations or grants rights to Google trademarks.
|
| 6 |
+
|
| 7 |
+
The authoritative sources are [Google's Terms](https://ai.google.dev/gemma/terms) and [Google's policy](https://ai.google.dev/gemma/prohibited_use_policy). The accompanying copies identify their retrieval date. The current agreement still includes Gemma 2; the separate Gemma 4 license does not replace it for this inherited tokenizer.
|
LICENSING_STATUS.md
ADDED
|
@@ -0,0 +1,17 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Decision-1.0-Lex licensing
|
| 2 |
+
|
| 3 |
+
**Lex's new code and model-weight contributions use MIT.** Third-party material retains its original terms. The [MIT LICENSE](LICENSE) and existing [NOTICE](NOTICE) remain unchanged.
|
| 4 |
+
|
| 5 |
+
| Material | Applicable terms and attribution |
|
| 6 |
+
|---|---|
|
| 7 |
+
| Lex's new contributions; inherited Vela/mmBERT model contributions | Project MIT grant and upstream attribution in [NOTICE](NOTICE) |
|
| 8 |
+
| Adapted ModernBERT/Transformers code | [Apache-2.0](LICENSES/Transformers-Apache-2.0.txt); original copyright and modification attribution are retained |
|
| 9 |
+
| Inherited tokenizer material | [Tokenizer terms](LICENSES/gemma/TOKENIZER_TERMS.md), the [Gemma agreement](LICENSES/gemma/GEMMA_TERMS.html), [use policy](LICENSES/gemma/GEMMA_PROHIBITED_USE_POLICY.html), and required [Notice](LICENSES/gemma/Notice) |
|
| 10 |
+
|
| 11 |
+
The tokenizer comes through Vela and mmBERT; mmBERT's author configuration identifies `google/gemma-2-9b` as its source. The included materials preserve the applicable upstream conditions. They do not assert a separate tokenizer MIT exemption, byte identity with Google's original files, or that Lex's encoder weights are Gemma weights. The original MIT and Apache grants do not replace those tokenizer conditions.
|
| 12 |
+
|
| 13 |
+
Vela's fixed model card (`fe9ccc074b781bc0e2e13c2c8d26f2640410636a`) and mmBERT's publisher card (`c5955035435e2bf121cde7f3c8863ef52ff35d82`) declare MIT. Transformers 4.57.6 (`753d61104116eefc8ffc977327b441ee0c8d599f`) supplies the Apache-2.0 code attribution. Public source links, revisions and file identities are recorded in [NOTICE_SOURCES.json](NOTICE_SOURCES.json). The Gemma agreement copy is dated April 1, 2026 and continues to cover Gemma 2; the separate Gemma 4 license is not substituted.
|
| 14 |
+
|
| 15 |
+
Downloads use automatic access after acknowledgment of the [distribution terms](DISTRIBUTION_TERMS.md), including the retained tokenizer agreement and use restrictions. This mechanism does not change the component-specific license scope or establish an unrestricted all-files-MIT grant. The distribution contains unchanged native weights and inherited tokenizer payload; the bundled notices and upstream texts remain part of the package.
|
| 16 |
+
|
| 17 |
+
Training/evaluation data, Laya weights and Laya SDK source are not redistributed in this release. Installed dependencies retain their own licenses.
|
METHODS.md
ADDED
|
@@ -0,0 +1,11 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Lex training method
|
| 2 |
+
|
| 3 |
+
Decision-1.0-Lex is an English typed-decisions specialist fine-tuned from the fixed Kai native `da603662bc57e89ccfb51c972ed9c1f2825f267597353cf1337df9117a3dfabe`. Its 571,909,635-parameter geometry is unchanged. All three type paths are trained: 486 tensors across three encoders, interaction heads and scorers; the shared token embedding, embedding normalization and type embedding remain frozen.
|
| 4 |
+
|
| 5 |
+
Development used a state-component split of the original official TRAIN: 4,800 decisions for training and 1,200 for development. The fixed selected recipe was blend50 at the higher learning-rate setting. Those development scores are distinct from the final TEST result. The final refit then combined all 6,000 original TRAIN decisions, trained from the same Kai parent for eight epochs, and exported fixed step 750 without checkpoint selection. Every decision appears exactly eight times; epochs are concatenated before dividing into logical batches, so no tail is dropped or repeated.
|
| 6 |
+
|
| 7 |
+
For the original normalized soft label vector q and original semantic hard-label one-hot h, the target is 0.5q + 0.5h. The loss is cross-entropy summed over 64 decisions and divided by 64, with no RPS, consistency, distillation or calibration fitting. Candidate order and semantic descriptions are retained. Each logical batch uses eight physical batches of eight. Training uses BF16 autocast with FP32 parameters and loss, AdamW (weight decay 0.01), gradient clipping at 1, and seed 20260921. There is no warmup. Encoder/head starting learning rates are 2.5e-5/1e-4 and each follows `1e-6 + (base - 1e-6) * (1 + cos(pi * (step - 1) / 749)) / 2` for steps 1–750.
|
| 8 |
+
|
| 9 |
+
All complete packed inputs fit 1,024 tokens. The final native manifest is `f288d873999832a3f37c6a7c4268c2ab309691e621794dbf7acab891acbbb7e6`. Native metadata retains the original research export provenance; its native Score training-policy metadata is an inference/export compatibility contract, not a claim that only Score was trained. The actual all-types update is recorded in the export provenance and [TRAINING_PROVENANCE.json](TRAINING_PROVENANCE.json).
|
| 10 |
+
|
| 11 |
+
The final TEST was opened only after this checkpoint and recipe were frozen. It was evaluated once against the official typed specialist on identical complete inputs. Neither TEST checkpoint selection nor temperature fitting was performed. [EVALUATION.md](EVALUATION.md) records the point improvement and its limits. This package does not transfer Kai's multilingual quality or latency measurements to Lex.
|
NOTICE
ADDED
|
@@ -0,0 +1,82 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
Decision Nano
|
| 2 |
+
Copyright (c) 2026 Decision Nano contributors
|
| 3 |
+
|
| 4 |
+
The accompanying MIT LICENSE applies to the project's original code,
|
| 5 |
+
documentation, and new model-weight contributions. It does not replace
|
| 6 |
+
third-party copyrights, licenses, or applicable source-material terms.
|
| 7 |
+
Upstream components and remaining provenance boundaries are identified below.
|
| 8 |
+
|
| 9 |
+
BASE ENCODER AND MODEL WEIGHTS
|
| 10 |
+
|
| 11 |
+
Decision Nano was developed from Vela-1.0-Encoder-307M, published by the
|
| 12 |
+
vLLM Semantic Router / Vela contributors:
|
| 13 |
+
https://huggingface.co/llm-semantic-router/Vela-1.0-Encoder-307M
|
| 14 |
+
Revision: fe9ccc074b781bc0e2e13c2c8d26f2640410636a
|
| 15 |
+
The pinned publisher model card declares the MIT license and identifies
|
| 16 |
+
jhu-clsp/mmBERT-base as its base model. Nano adds type-specific encoder
|
| 17 |
+
paths, candidate interaction/readout layers, packing and training changes.
|
| 18 |
+
No Vela, mmBERT, or other third-party copyright is transferred to Nano.
|
| 19 |
+
|
| 20 |
+
mmBERT is by Marc Marone, Orion Weller, William Fleshman, Eugene Yang,
|
| 21 |
+
Dawn Lawrie, and Benjamin Van Durme. Its official model card declares MIT:
|
| 22 |
+
https://huggingface.co/jhu-clsp/mmBERT-base
|
| 23 |
+
Model-card revision inspected: c5955035435e2bf121cde7f3c8863ef52ff35d82
|
| 24 |
+
This revision identifies the license evidence; it is not a claim that Vela's
|
| 25 |
+
historical training ancestry was reconstructed to that mmBERT checkpoint.
|
| 26 |
+
Reference: mmBERT: A Modern Multilingual Encoder with Annealed Language
|
| 27 |
+
Learning (2025), https://arxiv.org/abs/2509.06888
|
| 28 |
+
|
| 29 |
+
The original publisher cards and their hashes are retained in
|
| 30 |
+
source-metadata/MODEL_LICENSE_METADATA.json. Neither inspected model
|
| 31 |
+
snapshot supplies a separate upstream LICENSE file or copyright notice.
|
| 32 |
+
|
| 33 |
+
MODERNBERT / TRANSFORMERS CODE
|
| 34 |
+
|
| 35 |
+
Copyright 2018- The Hugging Face team. All rights reserved.
|
| 36 |
+
Copyright 2024 Answer.AI, LightOn, and contributors, and the HuggingFace Inc.
|
| 37 |
+
team. All rights reserved.
|
| 38 |
+
|
| 39 |
+
The ModernBERT implementation used by Nano is from Transformers 4.57.6,
|
| 40 |
+
commit 753d61104116eefc8ffc977327b441ee0c8d599f, under Apache License 2.0.
|
| 41 |
+
The complete upstream license is retained in
|
| 42 |
+
LICENSES/Transformers-Apache-2.0.txt. The original ModernBERT copyright
|
| 43 |
+
header and exact source references are retained under source-metadata/.
|
| 44 |
+
|
| 45 |
+
native/policy/reference/modernbert_sdpa_layout.py adapts the upstream
|
| 46 |
+
ModernBERT attention computation: it makes Q/K/V contiguous on the guarded
|
| 47 |
+
ROCm efficient-SDPA path and binds the wrapper locally. The original path
|
| 48 |
+
is retained outside that guard. This is a project modification, not an
|
| 49 |
+
unmodified upstream Transformers file. The adapted upstream portions
|
| 50 |
+
remain subject to Apache-2.0; the root MIT LICENSE does not override them.
|
| 51 |
+
|
| 52 |
+
TOKENIZER PROVENANCE BOUNDARY
|
| 53 |
+
|
| 54 |
+
Nano retains the tokenizer payload inherited through Vela/mmBERT.
|
| 55 |
+
The mmBERT authors identify its tokenizer as Gemma 2; their training
|
| 56 |
+
configuration names google/gemma-2-9b. Google publishes that original
|
| 57 |
+
repository under Gemma terms, whereas the inspected mmBERT and Vela model
|
| 58 |
+
cards declare MIT for their repositories without a tokenizer-specific
|
| 59 |
+
notice or exception. The exact applicable scope for these inherited
|
| 60 |
+
tokenizer files is not established by a model-card tag alone.
|
| 61 |
+
|
| 62 |
+
This notice therefore does not independently relicense tokenizer.json,
|
| 63 |
+
tokenizer_config.json, or special_tokens_map.json as Nano-created MIT
|
| 64 |
+
material, and does not assert that Gemma terms govern Nano's independently
|
| 65 |
+
trained encoder weights. See LICENSING_STATUS.md for the exact affected
|
| 66 |
+
files and the remaining clarification needed before an unrestricted
|
| 67 |
+
all-files-MIT distribution claim.
|
| 68 |
+
|
| 69 |
+
TRAINING SOURCES AND RUNTIME DEPENDENCIES
|
| 70 |
+
|
| 71 |
+
Training-source credits and the changes made in constructing typed tasks
|
| 72 |
+
are listed in TRAINING_ATTRIBUTION.md. No training or evaluation examples,
|
| 73 |
+
Laya model weights, or Laya SDK source files are included in this package.
|
| 74 |
+
The root LICENSE does not relicense the underlying datasets or waive their
|
| 75 |
+
attribution, share-alike, or other applicable conditions.
|
| 76 |
+
|
| 77 |
+
PyTorch, Transformers, tokenizers, safetensors, NumPy and their dependencies
|
| 78 |
+
are installed separately. Their distributions retain their own licenses
|
| 79 |
+
and third-party notices. This package does not substitute its MIT LICENSE
|
| 80 |
+
for those dependency licenses.
|
| 81 |
+
|
| 82 |
+
This NOTICE is informational and does not alter any applicable license.
|
NOTICE_SOURCES.json
ADDED
|
@@ -0,0 +1,229 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"schema": "decision-nano-license-sources-v1",
|
| 3 |
+
"date": "2026-09-21",
|
| 4 |
+
"project_license": {
|
| 5 |
+
"spdx": "MIT",
|
| 6 |
+
"scope": "Original Decision Nano code, documentation and new model-weight contributions; third-party terms preserved",
|
| 7 |
+
"publisher_choice_explicit": true
|
| 8 |
+
},
|
| 9 |
+
"base_models": {
|
| 10 |
+
"vela": {
|
| 11 |
+
"api_url": "https://huggingface.co/api/models/llm-semantic-router/Vela-1.0-Encoder-307M/revision/fe9ccc074b781bc0e2e13c2c8d26f2640410636a",
|
| 12 |
+
"revision": "fe9ccc074b781bc0e2e13c2c8d26f2640410636a",
|
| 13 |
+
"license": "mit",
|
| 14 |
+
"base_model": "jhu-clsp/mmBERT-base",
|
| 15 |
+
"files": [
|
| 16 |
+
".gitattributes",
|
| 17 |
+
"README.md",
|
| 18 |
+
"config.json",
|
| 19 |
+
"model.safetensors",
|
| 20 |
+
"special_tokens_map.json",
|
| 21 |
+
"tokenizer.json",
|
| 22 |
+
"tokenizer_config.json"
|
| 23 |
+
],
|
| 24 |
+
"readme": {
|
| 25 |
+
"url": "https://huggingface.co/llm-semantic-router/Vela-1.0-Encoder-307M/resolve/fe9ccc074b781bc0e2e13c2c8d26f2640410636a/README.md",
|
| 26 |
+
"sha256": "817df5015d443e6a9e6bbc870d8bd4f0f5c0d48e29b8f50f665319609838f7ef",
|
| 27 |
+
"bytes": 2046,
|
| 28 |
+
"local_file": "source-metadata/VELA_LICENSE_SOURCE_README.md"
|
| 29 |
+
}
|
| 30 |
+
},
|
| 31 |
+
"mmbert": {
|
| 32 |
+
"api_url": "https://huggingface.co/api/models/jhu-clsp/mmBERT-base",
|
| 33 |
+
"revision": "c5955035435e2bf121cde7f3c8863ef52ff35d82",
|
| 34 |
+
"license": "mit",
|
| 35 |
+
"base_model": null,
|
| 36 |
+
"files": [
|
| 37 |
+
".gitattributes",
|
| 38 |
+
"README.md",
|
| 39 |
+
"config.json",
|
| 40 |
+
"pytorch_model.bin",
|
| 41 |
+
"special_tokens_map.json",
|
| 42 |
+
"tokenizer.json",
|
| 43 |
+
"tokenizer_config.json"
|
| 44 |
+
],
|
| 45 |
+
"readme": {
|
| 46 |
+
"url": "https://huggingface.co/jhu-clsp/mmBERT-base/resolve/c5955035435e2bf121cde7f3c8863ef52ff35d82/README.md",
|
| 47 |
+
"sha256": "35724415037ee3159aa733c16050620cc19a76219112a6ceeb3949572e0b37e9",
|
| 48 |
+
"bytes": 29650,
|
| 49 |
+
"local_file": "source-metadata/MMBERT_LICENSE_SOURCE_README.md"
|
| 50 |
+
}
|
| 51 |
+
}
|
| 52 |
+
},
|
| 53 |
+
"transformers": [
|
| 54 |
+
{
|
| 55 |
+
"url": "https://raw.githubusercontent.com/huggingface/transformers/753d61104116eefc8ffc977327b441ee0c8d599f/LICENSE",
|
| 56 |
+
"repository": "huggingface/transformers",
|
| 57 |
+
"revision": "753d61104116eefc8ffc977327b441ee0c8d599f",
|
| 58 |
+
"tag": "v4.57.6",
|
| 59 |
+
"upstream_file_sha256": "77fd4710def9ec3c0f6225800e0235f15a425abd4a8b03559127fcd782612049",
|
| 60 |
+
"saved_file": "LICENSES/Transformers-Apache-2.0.txt",
|
| 61 |
+
"saved_sha256": "77fd4710def9ec3c0f6225800e0235f15a425abd4a8b03559127fcd782612049",
|
| 62 |
+
"saved_bytes": 11418,
|
| 63 |
+
"full_license": true
|
| 64 |
+
},
|
| 65 |
+
{
|
| 66 |
+
"url": "https://raw.githubusercontent.com/huggingface/transformers/753d61104116eefc8ffc977327b441ee0c8d599f/src/transformers/models/modernbert/modeling_modernbert.py",
|
| 67 |
+
"repository": "huggingface/transformers",
|
| 68 |
+
"revision": "753d61104116eefc8ffc977327b441ee0c8d599f",
|
| 69 |
+
"tag": "v4.57.6",
|
| 70 |
+
"upstream_file_sha256": "1b23db2f59d3f80bd9af89fb6df3ce15affd90b5ffc09925e732450e694868ff",
|
| 71 |
+
"saved_file": "source-metadata/TRANSFORMERS_MODERNBERT_SOURCE_HEADER.txt",
|
| 72 |
+
"saved_sha256": "4577f1803f9dbe8b43f5da709f8750c798def2c33f7eb055d62baf286ed472c8",
|
| 73 |
+
"saved_bytes": 1497,
|
| 74 |
+
"full_license": false
|
| 75 |
+
}
|
| 76 |
+
],
|
| 77 |
+
"local_modernbert_adaptation": {
|
| 78 |
+
"package_file": "native/policy/reference/modernbert_sdpa_layout.py",
|
| 79 |
+
"sha256": "0fb3a22db93ad76e30dfbfb3011de442149d97c565e139a3a55738287a1fbbc8",
|
| 80 |
+
"bytes": 3365,
|
| 81 |
+
"source_verified_against_planned_native_payload": true,
|
| 82 |
+
"terms": "Apache-2.0 for adapted upstream portions; project modifications separately identified in NOTICE"
|
| 83 |
+
},
|
| 84 |
+
"tokenizer_lineage": {
|
| 85 |
+
"configuration_url": "https://raw.githubusercontent.com/JHU-CLSP/mmBERT/108ffb376ad65c2512801bb88931933dcd286baf/configs/mmBERT-base.yaml",
|
| 86 |
+
"configuration": {
|
| 87 |
+
"file": "source-metadata/MMBERT_TOKENIZER_LINEAGE.yaml",
|
| 88 |
+
"sha256": "0ffa0f1c8388868a42cdbb8ec4b709db6eab4b3e33d8495f4e5f0c32bd15afd3",
|
| 89 |
+
"bytes": 2768
|
| 90 |
+
},
|
| 91 |
+
"declared_tokenizer_name": "google/gemma-2-9b",
|
| 92 |
+
"original_publisher_repository": "https://huggingface.co/google/gemma-2-9b",
|
| 93 |
+
"original_terms_url": "https://ai.google.dev/gemma/terms",
|
| 94 |
+
"scope_status": "UPSTREAM_TERMS_SUPPLEMENT_PACKAGED_DOWNLOAD_USE_AGREEMENT_NOT_YET_INTEGRATED",
|
| 95 |
+
"affected_planned_files": {
|
| 96 |
+
"native/tokenizer/special_tokens_map.json": {
|
| 97 |
+
"sha256": "6e3204c5a4004719c185007a745d1940471a6fb02521cfa0a00306dbb6bc5903",
|
| 98 |
+
"bytes": 1051
|
| 99 |
+
},
|
| 100 |
+
"native/tokenizer/tokenizer.json": {
|
| 101 |
+
"sha256": "609d8f4c067cd3950f88594c5a802616cea245823836ef5848ee4fc40aab5b6f",
|
| 102 |
+
"bytes": 34363188
|
| 103 |
+
},
|
| 104 |
+
"native/tokenizer/tokenizer_config.json": {
|
| 105 |
+
"sha256": "74a259bb1a3811a7e3028adcd07a65765d866d5e66e0e883f0994ccfa67e8455",
|
| 106 |
+
"bytes": 46470
|
| 107 |
+
}
|
| 108 |
+
},
|
| 109 |
+
"no_gated_source_fetched": true
|
| 110 |
+
},
|
| 111 |
+
"distribution": {
|
| 112 |
+
"native_manifest_sha256": "25642383af8af8b24ac8a482a5b1697bd59cbcac02978cd6c6fd571bd3e6148f",
|
| 113 |
+
"training_or_evaluation_data_included": false,
|
| 114 |
+
"laya_weights_or_sdk_source_included": false,
|
| 115 |
+
"installed_dependency_distributions_vendored": false
|
| 116 |
+
},
|
| 117 |
+
"superseded_draft": {
|
| 118 |
+
"sha256": "d9bc648b19d435e2173aeabbed6728b5fe4c1e766ac67c20faa934e98218c46f",
|
| 119 |
+
"bytes": 2419,
|
| 120 |
+
"preserved_at": "previous package-preview attribution draft"
|
| 121 |
+
},
|
| 122 |
+
"files": [
|
| 123 |
+
{
|
| 124 |
+
"file": "LICENSE",
|
| 125 |
+
"sha256": "fa0d68dc88b1e5f5511e7d0f21744acff46782693ea453326bd5b12c8a756f3f",
|
| 126 |
+
"bytes": 1083
|
| 127 |
+
},
|
| 128 |
+
{
|
| 129 |
+
"file": "NOTICE",
|
| 130 |
+
"sha256": "f154da77b74087d1e000dc6bd4ef6b9e2cc169195da78eff416abdb18d3fa191",
|
| 131 |
+
"bytes": 4245
|
| 132 |
+
},
|
| 133 |
+
{
|
| 134 |
+
"file": "NOTICE_DRAFT.md",
|
| 135 |
+
"sha256": "626249b6e003b5e199ce1bba549f92f7fb0074a8c9935f791f896105312d1ce0",
|
| 136 |
+
"bytes": 440
|
| 137 |
+
},
|
| 138 |
+
{
|
| 139 |
+
"file": "TRAINING_ATTRIBUTION.md",
|
| 140 |
+
"sha256": "19571d6d1844cee1e546d37b38b12ea4e4298a780bd427e53b6236d24fb1044f",
|
| 141 |
+
"bytes": 4625
|
| 142 |
+
},
|
| 143 |
+
{
|
| 144 |
+
"file": "LICENSING_STATUS.md",
|
| 145 |
+
"sha256": "46c4964c3a01be179608b3902ac0275460e8fcbd951421372f03fea5024fbde0",
|
| 146 |
+
"bytes": 2258
|
| 147 |
+
},
|
| 148 |
+
{
|
| 149 |
+
"file": "LICENSES/Transformers-Apache-2.0.txt",
|
| 150 |
+
"sha256": "77fd4710def9ec3c0f6225800e0235f15a425abd4a8b03559127fcd782612049",
|
| 151 |
+
"bytes": 11418
|
| 152 |
+
},
|
| 153 |
+
{
|
| 154 |
+
"file": "source-metadata/MODEL_LICENSE_METADATA.json",
|
| 155 |
+
"sha256": "696395f97428b851f136d50d850978af8c2a3b278c82620f63246a9312b74a30",
|
| 156 |
+
"bytes": 1538
|
| 157 |
+
},
|
| 158 |
+
{
|
| 159 |
+
"file": "source-metadata/TRANSFORMERS_LICENSE_SOURCE.json",
|
| 160 |
+
"sha256": "b60e54814b6c70791318475ebd4737c29fe5816f3141df392144dd31ac316d77",
|
| 161 |
+
"bytes": 1178
|
| 162 |
+
},
|
| 163 |
+
{
|
| 164 |
+
"file": "source-metadata/TRANSFORMERS_MODERNBERT_SOURCE_HEADER.txt",
|
| 165 |
+
"sha256": "4577f1803f9dbe8b43f5da709f8750c798def2c33f7eb055d62baf286ed472c8",
|
| 166 |
+
"bytes": 1497
|
| 167 |
+
},
|
| 168 |
+
{
|
| 169 |
+
"file": "LICENSES/gemma/GEMMA_PROHIBITED_USE_POLICY.html",
|
| 170 |
+
"sha256": "7e50ae0c7a6386ab51d36aa868e1d20a4fb28cbcab38778a5dbdac6a445f5a96",
|
| 171 |
+
"bytes": 4636
|
| 172 |
+
},
|
| 173 |
+
{
|
| 174 |
+
"file": "LICENSES/gemma/GEMMA_TERMS.html",
|
| 175 |
+
"sha256": "01ccbe2f6504a6a1364db0e5d6d91ed37309435229c322a29b20ee5daebebc1a",
|
| 176 |
+
"bytes": 13510
|
| 177 |
+
},
|
| 178 |
+
{
|
| 179 |
+
"file": "LICENSES/gemma/Notice",
|
| 180 |
+
"sha256": "a7b8b1b625d4a140b4dd55ee4479db7d64b5cda047f2cbc1be9d21516b470921",
|
| 181 |
+
"bytes": 1088
|
| 182 |
+
},
|
| 183 |
+
{
|
| 184 |
+
"file": "LICENSES/gemma/TOKENIZER_TERMS.md",
|
| 185 |
+
"sha256": "3929fe0a22a189b5ed3f29db13aec7b11f8a88feba727c8029a1e11ef5f8d70d",
|
| 186 |
+
"bytes": 1326
|
| 187 |
+
}
|
| 188 |
+
],
|
| 189 |
+
"license_resolution_supplement": {
|
| 190 |
+
"product": "Decision-1.0-Kai",
|
| 191 |
+
"source_review": {
|
| 192 |
+
"file": "release/license-resolution-v1/REVIEW.md",
|
| 193 |
+
"sha256": "dce1b3a1ae3a536033898c8f514b151d56ed48bfe328a42d0d712c923da6db9f",
|
| 194 |
+
"bytes": 3932
|
| 195 |
+
},
|
| 196 |
+
"official_fetch_receipt": {
|
| 197 |
+
"file": "release/license-resolution-v1/OFFICIAL_FETCH_RECEIPT.json",
|
| 198 |
+
"sha256": "34a017f07218e98b8fbef4a738421f9d944ffff751edbe3be7419b272363d20b",
|
| 199 |
+
"bytes": 2223
|
| 200 |
+
},
|
| 201 |
+
"copies": [
|
| 202 |
+
{
|
| 203 |
+
"file": "LICENSES/gemma/GEMMA_PROHIBITED_USE_POLICY.html",
|
| 204 |
+
"sha256": "7e50ae0c7a6386ab51d36aa868e1d20a4fb28cbcab38778a5dbdac6a445f5a96",
|
| 205 |
+
"bytes": 4636
|
| 206 |
+
},
|
| 207 |
+
{
|
| 208 |
+
"file": "LICENSES/gemma/GEMMA_TERMS.html",
|
| 209 |
+
"sha256": "01ccbe2f6504a6a1364db0e5d6d91ed37309435229c322a29b20ee5daebebc1a",
|
| 210 |
+
"bytes": 13510
|
| 211 |
+
},
|
| 212 |
+
{
|
| 213 |
+
"file": "LICENSES/gemma/Notice",
|
| 214 |
+
"sha256": "a7b8b1b625d4a140b4dd55ee4479db7d64b5cda047f2cbc1be9d21516b470921",
|
| 215 |
+
"bytes": 1088
|
| 216 |
+
},
|
| 217 |
+
{
|
| 218 |
+
"file": "LICENSES/gemma/TOKENIZER_TERMS.md",
|
| 219 |
+
"sha256": "3929fe0a22a189b5ed3f29db13aec7b11f8a88feba727c8029a1e11ef5f8d70d",
|
| 220 |
+
"bytes": 1326
|
| 221 |
+
}
|
| 222 |
+
],
|
| 223 |
+
"download_use_agreement_integrated": false,
|
| 224 |
+
"hf_gate_configured": false,
|
| 225 |
+
"legal_enforceability_determined": false,
|
| 226 |
+
"all_files_mit_claim": false,
|
| 227 |
+
"original_LICENSE_NOTICE_unchanged": true
|
| 228 |
+
}
|
| 229 |
+
}
|
PACKAGE_MANIFEST.json
ADDED
|
@@ -0,0 +1,376 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"files": {
|
| 3 |
+
".gitattributes": {
|
| 4 |
+
"bytes": 753,
|
| 5 |
+
"sha256": "d401c47d3da9ae93830e327b487cde895438378a1f90620a70b5c7b3e5d3ed92"
|
| 6 |
+
},
|
| 7 |
+
"ARCHITECTURE.md": {
|
| 8 |
+
"bytes": 1330,
|
| 9 |
+
"sha256": "82ceb4a1b1d6372ec15cce9b2902dc52477383f5bc52ba4206aad93efce097ff"
|
| 10 |
+
},
|
| 11 |
+
"DISTRIBUTION_TERMS.md": {
|
| 12 |
+
"bytes": 1147,
|
| 13 |
+
"sha256": "f1d3806ecf7c89046e6a422ad3cad9f85a589f28c3936b78b41806e92b297b7f"
|
| 14 |
+
},
|
| 15 |
+
"EVALUATION.md": {
|
| 16 |
+
"bytes": 2813,
|
| 17 |
+
"sha256": "00862d0a49c69c406b7dbfa890f95f09a34680568309d1cc0571733abe7b933c"
|
| 18 |
+
},
|
| 19 |
+
"FINETUNING.md": {
|
| 20 |
+
"bytes": 3629,
|
| 21 |
+
"sha256": "33c76f3490f283d9e189eeb4190c0297795329b56546271a52b80cd503dd2ec0"
|
| 22 |
+
},
|
| 23 |
+
"LICENSE": {
|
| 24 |
+
"bytes": 1083,
|
| 25 |
+
"sha256": "fa0d68dc88b1e5f5511e7d0f21744acff46782693ea453326bd5b12c8a756f3f"
|
| 26 |
+
},
|
| 27 |
+
"LICENSES/Transformers-Apache-2.0.txt": {
|
| 28 |
+
"bytes": 11418,
|
| 29 |
+
"sha256": "77fd4710def9ec3c0f6225800e0235f15a425abd4a8b03559127fcd782612049"
|
| 30 |
+
},
|
| 31 |
+
"LICENSES/gemma/GEMMA_PROHIBITED_USE_POLICY.html": {
|
| 32 |
+
"bytes": 4636,
|
| 33 |
+
"sha256": "7e50ae0c7a6386ab51d36aa868e1d20a4fb28cbcab38778a5dbdac6a445f5a96"
|
| 34 |
+
},
|
| 35 |
+
"LICENSES/gemma/GEMMA_TERMS.html": {
|
| 36 |
+
"bytes": 13510,
|
| 37 |
+
"sha256": "01ccbe2f6504a6a1364db0e5d6d91ed37309435229c322a29b20ee5daebebc1a"
|
| 38 |
+
},
|
| 39 |
+
"LICENSES/gemma/Notice": {
|
| 40 |
+
"bytes": 1088,
|
| 41 |
+
"sha256": "a7b8b1b625d4a140b4dd55ee4479db7d64b5cda047f2cbc1be9d21516b470921"
|
| 42 |
+
},
|
| 43 |
+
"LICENSES/gemma/TOKENIZER_TERMS.md": {
|
| 44 |
+
"bytes": 1326,
|
| 45 |
+
"sha256": "3929fe0a22a189b5ed3f29db13aec7b11f8a88feba727c8029a1e11ef5f8d70d"
|
| 46 |
+
},
|
| 47 |
+
"LICENSING_STATUS.md": {
|
| 48 |
+
"bytes": 2324,
|
| 49 |
+
"sha256": "fdc2482eb5a734e2390058b673aca9d38374703ad6fc13fc9794ef1d89fd07ba"
|
| 50 |
+
},
|
| 51 |
+
"METHODS.md": {
|
| 52 |
+
"bytes": 2543,
|
| 53 |
+
"sha256": "a7dd6dec55dfe463cc0211c3dffa114b88bb95db90816b70c18b62b5d7be7ad1"
|
| 54 |
+
},
|
| 55 |
+
"NOTICE": {
|
| 56 |
+
"bytes": 4245,
|
| 57 |
+
"sha256": "f154da77b74087d1e000dc6bd4ef6b9e2cc169195da78eff416abdb18d3fa191"
|
| 58 |
+
},
|
| 59 |
+
"NOTICE_SOURCES.json": {
|
| 60 |
+
"bytes": 8858,
|
| 61 |
+
"sha256": "55bd38eb79306965774c0531717177b1ad8f168c886414ffd421f8bbec7097b5"
|
| 62 |
+
},
|
| 63 |
+
"README.md": {
|
| 64 |
+
"bytes": 4683,
|
| 65 |
+
"sha256": "76b5b4529cdb7e09d4a236e55ff5672c7f1bac9408780cda19bf4ed9dfe30dbe"
|
| 66 |
+
},
|
| 67 |
+
"TECHNICAL_VALIDATION.json": {
|
| 68 |
+
"bytes": 1547,
|
| 69 |
+
"sha256": "fcfd2ce54f623325f268a702fc0c06044447e651dad665d6430e92d48f8e7353"
|
| 70 |
+
},
|
| 71 |
+
"TRAINING_ATTRIBUTION.md": {
|
| 72 |
+
"bytes": 5808,
|
| 73 |
+
"sha256": "7d0689d8c5e342e2dce4c7f2ee5e7f5d8b69c43bb3ea262601a12156bf3bff41"
|
| 74 |
+
},
|
| 75 |
+
"TRAINING_PROVENANCE.json": {
|
| 76 |
+
"bytes": 2310,
|
| 77 |
+
"sha256": "5c95cf851a9480e6037bc190d0deee87da35576489362262ad4151bafbb96990"
|
| 78 |
+
},
|
| 79 |
+
"USAGE.md": {
|
| 80 |
+
"bytes": 3245,
|
| 81 |
+
"sha256": "289c507fcb507328511a88b41db3eb3adada16e8c0644152ce782617d4f4f074"
|
| 82 |
+
},
|
| 83 |
+
"VALIDATION.md": {
|
| 84 |
+
"bytes": 2120,
|
| 85 |
+
"sha256": "85e1f45ddf0d5e2650490eefdbd50f81ccccd7f414d78a8075206da49ef0043d"
|
| 86 |
+
},
|
| 87 |
+
"assets/architecture-atlas.pdf": {
|
| 88 |
+
"bytes": 635270,
|
| 89 |
+
"sha256": "ff64805a39d16be56d401166ef4d310da86305058bb2c532751754c8c34d49ee"
|
| 90 |
+
},
|
| 91 |
+
"assets/architecture.pdf": {
|
| 92 |
+
"bytes": 173099,
|
| 93 |
+
"sha256": "6aa6895f5708cda7d935991cf9c1179d9e54e22a32459968a052acf05f62a14a"
|
| 94 |
+
},
|
| 95 |
+
"assets/architecture.png": {
|
| 96 |
+
"bytes": 432419,
|
| 97 |
+
"sha256": "daeed79f92a66a2655eb0594f59af4e90424a84ba9519eeaf2ef5bb8b7949fa2"
|
| 98 |
+
},
|
| 99 |
+
"assets/architecture.svg": {
|
| 100 |
+
"bytes": 23430,
|
| 101 |
+
"sha256": "7c3ae44a25e7d9035e6a9635608f7e491a22d9be6991243b85d85f30874e563c"
|
| 102 |
+
},
|
| 103 |
+
"assets/attention-geglu.pdf": {
|
| 104 |
+
"bytes": 172797,
|
| 105 |
+
"sha256": "43b3485510971d29e66bc17b30b4bffe934ad66078598cc3e2efd63ae9b9bc7c"
|
| 106 |
+
},
|
| 107 |
+
"assets/attention-geglu.png": {
|
| 108 |
+
"bytes": 265587,
|
| 109 |
+
"sha256": "de7d88e3cf036d3b8cba38df47d5b3182faecb9233e675104cee7c75dd7fd8c5"
|
| 110 |
+
},
|
| 111 |
+
"assets/attention-geglu.svg": {
|
| 112 |
+
"bytes": 10256,
|
| 113 |
+
"sha256": "0ae02a36ebe97d0b6eed7b23e140c1fdc85e710c00015c518cae67ed5ec06cea"
|
| 114 |
+
},
|
| 115 |
+
"assets/candidate-readout.pdf": {
|
| 116 |
+
"bytes": 156814,
|
| 117 |
+
"sha256": "56b9e06a343e9044c38cfb8d1ba5ba121bdc7d763db5ce45b927aacdcb00c995"
|
| 118 |
+
},
|
| 119 |
+
"assets/candidate-readout.png": {
|
| 120 |
+
"bytes": 309736,
|
| 121 |
+
"sha256": "ad4be86a2aa0136cd7f528c317340c38988b932aab653f25a5a57a9a3cbad834"
|
| 122 |
+
},
|
| 123 |
+
"assets/candidate-readout.svg": {
|
| 124 |
+
"bytes": 9825,
|
| 125 |
+
"sha256": "1d3709818d5b08014ba63042e5287f84f1c97a735a85ec49108ec6e9e77151ee"
|
| 126 |
+
},
|
| 127 |
+
"assets/decision-lex-header.png": {
|
| 128 |
+
"bytes": 2237372,
|
| 129 |
+
"sha256": "064a4d5ad3ae8b25e973bcf6abdc4117b3d8883bcb87d11a95a8bf9eadd89673"
|
| 130 |
+
},
|
| 131 |
+
"assets/residual-layers.pdf": {
|
| 132 |
+
"bytes": 131144,
|
| 133 |
+
"sha256": "2c5b50bb840ae115a1264b66d535a1048172e891a33d02d507c193525cc45630"
|
| 134 |
+
},
|
| 135 |
+
"assets/residual-layers.png": {
|
| 136 |
+
"bytes": 309369,
|
| 137 |
+
"sha256": "f3ee6441fe1016e2435256644675b08bff99cec72d521e49a78f6cbe5b2dc3bf"
|
| 138 |
+
},
|
| 139 |
+
"assets/residual-layers.svg": {
|
| 140 |
+
"bytes": 10990,
|
| 141 |
+
"sha256": "cdf5cfb263b50eef0171eafead3062ee75eb805961517f313490fdca03b390c3"
|
| 142 |
+
},
|
| 143 |
+
"decision_finetune/__init__.py": {
|
| 144 |
+
"bytes": 81,
|
| 145 |
+
"sha256": "51ab50ae9a598c7b09970161be3551f9dff0851a209ec692f2e296b1bd44566d"
|
| 146 |
+
},
|
| 147 |
+
"decision_finetune/__main__.py": {
|
| 148 |
+
"bytes": 5410,
|
| 149 |
+
"sha256": "d5cabebd24c823d5dc03a4b528dae8b8b70a63dd0692eb6516a59bd4bd64d6a7"
|
| 150 |
+
},
|
| 151 |
+
"decision_finetune/data.py": {
|
| 152 |
+
"bytes": 6679,
|
| 153 |
+
"sha256": "9fae31cb39512952a1dd78fb0b6735434da6f6b94606341fc0200ab9cdaf447e"
|
| 154 |
+
},
|
| 155 |
+
"decision_finetune/metrics.py": {
|
| 156 |
+
"bytes": 4046,
|
| 157 |
+
"sha256": "c3de487e9294d5278064b7e1768915bf68f593c9d7fb067addc52c4c9ac3b07e"
|
| 158 |
+
},
|
| 159 |
+
"decision_finetune/run.py": {
|
| 160 |
+
"bytes": 16750,
|
| 161 |
+
"sha256": "045ff99dd95c69e2ccdf4b1f8af84797c2929a27b16a9c1a3208bba10b41361b"
|
| 162 |
+
},
|
| 163 |
+
"decision_finetune/state.py": {
|
| 164 |
+
"bytes": 5751,
|
| 165 |
+
"sha256": "87dd485127fea7b80ad19300c0d6d95a92b7c2b6bd5b62c99bdc9201b681c9fe"
|
| 166 |
+
},
|
| 167 |
+
"decision_inference/__init__.py": {
|
| 168 |
+
"bytes": 138,
|
| 169 |
+
"sha256": "4b5452be7f24be5accb72df1b2d74d9247a39a48173a79f3f5fd884225be0bbd"
|
| 170 |
+
},
|
| 171 |
+
"decision_inference/profile.py": {
|
| 172 |
+
"bytes": 2375,
|
| 173 |
+
"sha256": "a634a52654efbc378fc564c4fa1cd1a1fdd866f8dd44d6d8f63a2bf4243649e3"
|
| 174 |
+
},
|
| 175 |
+
"decision_runtime/__init__.py": {
|
| 176 |
+
"bytes": 723,
|
| 177 |
+
"sha256": "b0f9db94cfbcc73cab2f09e0269b8bd2eb87c0cc533b34ea5c9a8bfbb1ee48ca"
|
| 178 |
+
},
|
| 179 |
+
"decision_runtime/_compat.py": {
|
| 180 |
+
"bytes": 1847,
|
| 181 |
+
"sha256": "a0dd42a4e3b20eabbaf0d0d62ffc290ef4d9d20bc2fb2ba39d980771a8d0744c"
|
| 182 |
+
},
|
| 183 |
+
"decision_runtime/native.py": {
|
| 184 |
+
"bytes": 6903,
|
| 185 |
+
"sha256": "21c674a0d8a1406156504390974505ba5f981e7ecc9f0c3b29985876ef78511c"
|
| 186 |
+
},
|
| 187 |
+
"decision_runtime/training.py": {
|
| 188 |
+
"bytes": 15998,
|
| 189 |
+
"sha256": "166ea54629d5c90e0e0972b82c0b96e008c799f384400886ffd64312ab972177"
|
| 190 |
+
},
|
| 191 |
+
"examples/decisions.jsonl": {
|
| 192 |
+
"bytes": 867,
|
| 193 |
+
"sha256": "d4b89583ccc9aa35e74dd28c46e01884103ea7a0fa018de8c34d4f88a94287f1"
|
| 194 |
+
},
|
| 195 |
+
"examples/finetune.sh": {
|
| 196 |
+
"bytes": 1242,
|
| 197 |
+
"sha256": "9b72d89237808e0019521ab4e42635007c39d20ea200d98afa9fdca6e49ae400"
|
| 198 |
+
},
|
| 199 |
+
"infer.py": {
|
| 200 |
+
"bytes": 2373,
|
| 201 |
+
"sha256": "6313bfd5e295d5dc3d9b6ded5f85cda75cf1da8ed4b2dbae32f619a76021e410"
|
| 202 |
+
},
|
| 203 |
+
"native/INVENTORY.json": {
|
| 204 |
+
"bytes": 31007,
|
| 205 |
+
"sha256": "06aed00ac4571582b992a995a793875804a0546bdae1461c4161b30fba2143a9"
|
| 206 |
+
},
|
| 207 |
+
"native/MANIFEST.json": {
|
| 208 |
+
"bytes": 4326,
|
| 209 |
+
"sha256": "f288d873999832a3f37c6a7c4268c2ab309691e621794dbf7acab891acbbb7e6"
|
| 210 |
+
},
|
| 211 |
+
"native/STATE_LAYOUT.json": {
|
| 212 |
+
"bytes": 10971,
|
| 213 |
+
"sha256": "a6b24716e2b21240d327ba8763a73f1b54862bc86d5e1f92bb9e670be968e494"
|
| 214 |
+
},
|
| 215 |
+
"native/__init__.py": {
|
| 216 |
+
"bytes": 78,
|
| 217 |
+
"sha256": "1afb9dbcfc379f28049486fe6acb7acfdaa8d16b6773d6084ca4b82ead26f010"
|
| 218 |
+
},
|
| 219 |
+
"native/artifacts.py": {
|
| 220 |
+
"bytes": 7958,
|
| 221 |
+
"sha256": "c98adaf6d782e9fc592cd78b1307d63faffa9ba622b9d508c63337c29156e4d3"
|
| 222 |
+
},
|
| 223 |
+
"native/choice_encoder.safetensors": {
|
| 224 |
+
"bytes": 441337216,
|
| 225 |
+
"sha256": "9516cc841c485c98b27b4f63d2ea8e604fe8064121173064b113da8a6bf57ef6"
|
| 226 |
+
},
|
| 227 |
+
"native/contract.py": {
|
| 228 |
+
"bytes": 10886,
|
| 229 |
+
"sha256": "51a24800792bb3e5bf2a11f50f7bc384770641f4f44ed46277dc01e891bf4726"
|
| 230 |
+
},
|
| 231 |
+
"native/decision_config.json": {
|
| 232 |
+
"bytes": 14308,
|
| 233 |
+
"sha256": "1fefb4ad7dede00c4633bb2ce5fc44fb04237207b9e9ce90fcf8ea8b01a1328d"
|
| 234 |
+
},
|
| 235 |
+
"native/decision_heads.safetensors": {
|
| 236 |
+
"bytes": 177241884,
|
| 237 |
+
"sha256": "bce3ee658a978a19c48c605b921cff994f892e7fc17abd6f8645f07428fbc36f"
|
| 238 |
+
},
|
| 239 |
+
"native/encoder/config.json": {
|
| 240 |
+
"bytes": 2769,
|
| 241 |
+
"sha256": "7aff915e9f159305e0bef3eb0206416f99b8560260b8969b35f1dcd54aaad1a5"
|
| 242 |
+
},
|
| 243 |
+
"native/encoder/model.safetensors": {
|
| 244 |
+
"bytes": 1227771752,
|
| 245 |
+
"sha256": "daaafd81c4ed767d203e24226d78e792800068a7dac344aa043844b82a6306c7"
|
| 246 |
+
},
|
| 247 |
+
"native/infer.py": {
|
| 248 |
+
"bytes": 1095,
|
| 249 |
+
"sha256": "9d14841935c836a0765c705d5a24e8fa97437ae35fff65bc6e690b397f0d0315"
|
| 250 |
+
},
|
| 251 |
+
"native/model.py": {
|
| 252 |
+
"bytes": 11098,
|
| 253 |
+
"sha256": "8fe91e2a77f372d32117e62281ccb58a054c144228b73b4987f1e1a3fca9ee5b"
|
| 254 |
+
},
|
| 255 |
+
"native/packing.py": {
|
| 256 |
+
"bytes": 6748,
|
| 257 |
+
"sha256": "f1dab7f032f4aaab27118606397ca67d71b1f4a2ba49e65bebcfd83a64b27819"
|
| 258 |
+
},
|
| 259 |
+
"native/policy/__init__.py": {
|
| 260 |
+
"bytes": 131,
|
| 261 |
+
"sha256": "0cb0bad7d3d0f258ecf95f52297ee8733a75f8504cabb86b9aea4b8256885114"
|
| 262 |
+
},
|
| 263 |
+
"native/policy/artifacts.py": {
|
| 264 |
+
"bytes": 7877,
|
| 265 |
+
"sha256": "5838d2ea747d912789f3fc813a212af919cbc24ee185073576d9fbe32ed31cf2"
|
| 266 |
+
},
|
| 267 |
+
"native/policy/contract.py": {
|
| 268 |
+
"bytes": 4334,
|
| 269 |
+
"sha256": "0b8eeeeebe9e367564a3c57f48364c5e94ae060f759e220b1326caf152276b67"
|
| 270 |
+
},
|
| 271 |
+
"native/policy/infer.py": {
|
| 272 |
+
"bytes": 1545,
|
| 273 |
+
"sha256": "672bfae798060d51fcccac03143ac881fe7512893ffdacdb36b0618d4b160896"
|
| 274 |
+
},
|
| 275 |
+
"native/policy/model.py": {
|
| 276 |
+
"bytes": 7678,
|
| 277 |
+
"sha256": "eaeebac8fd6bd96243a5c4b6225c86ee3359c067784f1595979ee603cba9acca"
|
| 278 |
+
},
|
| 279 |
+
"native/policy/packing.py": {
|
| 280 |
+
"bytes": 6748,
|
| 281 |
+
"sha256": "f1dab7f032f4aaab27118606397ca67d71b1f4a2ba49e65bebcfd83a64b27819"
|
| 282 |
+
},
|
| 283 |
+
"native/policy/reference/__init__.py": {
|
| 284 |
+
"bytes": 192,
|
| 285 |
+
"sha256": "c8d6fd86207752407f94437544a97266b9529f88d2b341d35aafcd911c942b28"
|
| 286 |
+
},
|
| 287 |
+
"native/policy/reference/artifacts.py": {
|
| 288 |
+
"bytes": 9342,
|
| 289 |
+
"sha256": "3f59428b7a05608ac01c73c7db89c38fcc3e2c5030219df8d053af92b32e6159"
|
| 290 |
+
},
|
| 291 |
+
"native/policy/reference/infer.py": {
|
| 292 |
+
"bytes": 1545,
|
| 293 |
+
"sha256": "672bfae798060d51fcccac03143ac881fe7512893ffdacdb36b0618d4b160896"
|
| 294 |
+
},
|
| 295 |
+
"native/policy/reference/model.py": {
|
| 296 |
+
"bytes": 5060,
|
| 297 |
+
"sha256": "733ea4a48ea03089dac8c3e6a175920704fac50f93313b0214cec4052f25bd26"
|
| 298 |
+
},
|
| 299 |
+
"native/policy/reference/modernbert_sdpa_layout.py": {
|
| 300 |
+
"bytes": 3365,
|
| 301 |
+
"sha256": "0fb3a22db93ad76e30dfbfb3011de442149d97c565e139a3a55738287a1fbbc8"
|
| 302 |
+
},
|
| 303 |
+
"native/policy/reference/packing.py": {
|
| 304 |
+
"bytes": 6748,
|
| 305 |
+
"sha256": "f1dab7f032f4aaab27118606397ca67d71b1f4a2ba49e65bebcfd83a64b27819"
|
| 306 |
+
},
|
| 307 |
+
"native/score_encoder.safetensors": {
|
| 308 |
+
"bytes": 441337080,
|
| 309 |
+
"sha256": "4f45795977846ef4c31b34e4f35bf95dabf5951d71358bab32c9a94814a84a53"
|
| 310 |
+
},
|
| 311 |
+
"native/tokenizer/special_tokens_map.json": {
|
| 312 |
+
"bytes": 1051,
|
| 313 |
+
"sha256": "6e3204c5a4004719c185007a745d1940471a6fb02521cfa0a00306dbb6bc5903"
|
| 314 |
+
},
|
| 315 |
+
"native/tokenizer/tokenizer.json": {
|
| 316 |
+
"bytes": 34363188,
|
| 317 |
+
"sha256": "609d8f4c067cd3950f88594c5a802616cea245823836ef5848ee4fc40aab5b6f"
|
| 318 |
+
},
|
| 319 |
+
"native/tokenizer/tokenizer_config.json": {
|
| 320 |
+
"bytes": 46470,
|
| 321 |
+
"sha256": "74a259bb1a3811a7e3028adcd07a65765d866d5e66e0e883f0994ccfa67e8455"
|
| 322 |
+
},
|
| 323 |
+
"native/training_policy.py": {
|
| 324 |
+
"bytes": 4761,
|
| 325 |
+
"sha256": "6f7fad91c5089b304a1d637b594027a9379a63600792766ce0abca6b24bd2ec5"
|
| 326 |
+
},
|
| 327 |
+
"requirements.txt": {
|
| 328 |
+
"bytes": 296,
|
| 329 |
+
"sha256": "001dd433614bcbacee15858a38f432b97f44b01ad404714f442738f4a8ce2428"
|
| 330 |
+
},
|
| 331 |
+
"source-metadata/ENCODER_README.md": {
|
| 332 |
+
"bytes": 2046,
|
| 333 |
+
"sha256": "817df5015d443e6a9e6bbc870d8bd4f0f5c0d48e29b8f50f665319609838f7ef"
|
| 334 |
+
},
|
| 335 |
+
"source-metadata/ENCODER_SOURCE.json": {
|
| 336 |
+
"bytes": 425,
|
| 337 |
+
"sha256": "9bb1a753d9979117520152860a599064d92a8eaf7f23a0e0d458c66007c8fdf9"
|
| 338 |
+
},
|
| 339 |
+
"source-metadata/MMBERT_LICENSE_SOURCE_README.md": {
|
| 340 |
+
"bytes": 29650,
|
| 341 |
+
"sha256": "35724415037ee3159aa733c16050620cc19a76219112a6ceeb3949572e0b37e9"
|
| 342 |
+
},
|
| 343 |
+
"source-metadata/MMBERT_TOKENIZER_LINEAGE.yaml": {
|
| 344 |
+
"bytes": 2768,
|
| 345 |
+
"sha256": "0ffa0f1c8388868a42cdbb8ec4b709db6eab4b3e33d8495f4e5f0c32bd15afd3"
|
| 346 |
+
},
|
| 347 |
+
"source-metadata/MODEL_LICENSE_METADATA.json": {
|
| 348 |
+
"bytes": 1538,
|
| 349 |
+
"sha256": "696395f97428b851f136d50d850978af8c2a3b278c82620f63246a9312b74a30"
|
| 350 |
+
},
|
| 351 |
+
"source-metadata/TRANSFORMERS_LICENSE_SOURCE.json": {
|
| 352 |
+
"bytes": 1178,
|
| 353 |
+
"sha256": "b60e54814b6c70791318475ebd4737c29fe5816f3141df392144dd31ac316d77"
|
| 354 |
+
},
|
| 355 |
+
"source-metadata/TRANSFORMERS_MODERNBERT_SOURCE_HEADER.txt": {
|
| 356 |
+
"bytes": 1497,
|
| 357 |
+
"sha256": "4577f1803f9dbe8b43f5da709f8750c798def2c33f7eb055d62baf286ed472c8"
|
| 358 |
+
},
|
| 359 |
+
"source-metadata/VELA_LICENSE_SOURCE_README.md": {
|
| 360 |
+
"bytes": 2046,
|
| 361 |
+
"sha256": "817df5015d443e6a9e6bbc870d8bd4f0f5c0d48e29b8f50f665319609838f7ef"
|
| 362 |
+
}
|
| 363 |
+
},
|
| 364 |
+
"language_scope": "English typed-decisions specialist",
|
| 365 |
+
"manifest_excludes_itself": true,
|
| 366 |
+
"name": "Decision-1.0-Lex",
|
| 367 |
+
"native_file_count": 31,
|
| 368 |
+
"native_manifest": "native/MANIFEST.json",
|
| 369 |
+
"parameter_tensors": 489,
|
| 370 |
+
"parameters": 571909635,
|
| 371 |
+
"schema": "decision.public-distribution.v1",
|
| 372 |
+
"status": "READY_FOR_ROOT_PUBLICATION",
|
| 373 |
+
"subject_manifest_sha256": "f288d873999832a3f37c6a7c4268c2ab309691e621794dbf7acab891acbbb7e6",
|
| 374 |
+
"technical_validation": "TECHNICAL_VALIDATION.json",
|
| 375 |
+
"training_provenance": "TRAINING_PROVENANCE.json"
|
| 376 |
+
}
|
README.md
ADDED
|
@@ -0,0 +1,73 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
base_model: llm-semantic-router/Decision-1.0-Kai
|
| 3 |
+
language:
|
| 4 |
+
- en
|
| 5 |
+
tags:
|
| 6 |
+
- decision-making
|
| 7 |
+
- text-classification
|
| 8 |
+
- ordinal-regression
|
| 9 |
+
- fine-tuned
|
| 10 |
+
- safetensors
|
| 11 |
+
license: other
|
| 12 |
+
license_name: decision-with-upstream-terms
|
| 13 |
+
license_link: https://huggingface.co/llm-semantic-router/Decision-1.0-Lex/blob/main/LICENSING_STATUS.md
|
| 14 |
+
extra_gated_heading: "Decision distribution terms"
|
| 15 |
+
extra_gated_description: "Decision's new code and weights use MIT; retained third-party material keeps its original terms. The inherited tokenizer is supplied under the Gemma Terms of Use and incorporated Prohibited Use Policy. The bundled distribution agreement incorporates the tokenizer terms at https://ai.google.dev/gemma/terms and use restrictions at https://ai.google.dev/gemma/prohibited_use_policy. Access is automatically granted after acknowledgment."
|
| 16 |
+
extra_gated_button_content: "Agree and access"
|
| 17 |
+
extra_gated_fields: {"I have read and agree to the distribution terms, including the Gemma Terms of Use and incorporated use restrictions for the inherited tokenizer": "checkbox"}
|
| 18 |
+
---
|
| 19 |
+
|
| 20 |
+

|
| 21 |
+
|
| 22 |
+
# Decision-1.0-Lex
|
| 23 |
+
|
| 24 |
+
*Lex — Latin for law. Give your decisions a rule.*
|
| 25 |
+
|
| 26 |
+
**Your move.**
|
| 27 |
+
|
| 28 |
+
Turn operational context into structured decisions. Lex is a specialist fine-tuned from Kai to select actions, test conditions and apply scoring rubrics across four English workflows.
|
| 29 |
+
|
| 30 |
+
**572M parameters · Three decision types · Complete 1K · Fine-tunable**
|
| 31 |
+
|
| 32 |
+
Initial release · [Try Decision Studio](https://llm-semantic-router-decision-studio.hf.space) · [Decision collection](https://huggingface.co/collections/llm-semantic-router/decision-10-6ab12177bd0002394d8409f9).
|
| 33 |
+
|
| 34 |
+
## A sharper specialist
|
| 35 |
+
|
| 36 |
+
**78.15% accuracy — 1.55 points above Laya Typed Decisions.**
|
| 37 |
+
|
| 38 |
+
Both models were evaluated on the original 2,000-decision typed-decisions test split, with complete inputs and the official fine-tuned Laya checkpoint. Lex answers **31 more decisions correctly**.
|
| 39 |
+
|
| 40 |
+
| Test accuracy | Lex | Laya Typed Decisions |
|
| 41 |
+
|---|---:|---:|
|
| 42 |
+
| **Overall** | **78.15%** | 76.60% |
|
| 43 |
+
| Choice · 600 decisions | **74.00%** | 73.33% |
|
| 44 |
+
| Noul · 600 decisions | 84.67% | **85.67%** |
|
| 45 |
+
| Score · 800 decisions | **76.38%** | 72.25% |
|
| 46 |
+
|
| 47 |
+
Observed accuracy gain; the paired 95% interval is −0.20 to +3.15 points. Laya leads on Noul and probability-quality metrics. [Full evaluation](https://gist.github.com/Xunzhuo/76b59cb158ce5069a53b946c6f0ee656#file-01-lex-evaluation-md).
|
| 48 |
+
|
| 49 |
+
## Built for operational decisions
|
| 50 |
+
|
| 51 |
+
| Customer service | Invoice processing | Security incidents | Agent traces |
|
| 52 |
+
|---|---|---|---|
|
| 53 |
+
| Select an action or escalation. | Check conditions and route exceptions. | Assess a signal against a rubric. | Classify outcomes and flag issues. |
|
| 54 |
+
|
| 55 |
+
Supply the context, question and candidate descriptions at runtime. **Choice** returns candidate probabilities, **Noul** estimates whether a condition holds, and **Score** returns an ordered distribution and expected value. Applications choose how to act on those outputs.
|
| 56 |
+
|
| 57 |
+
Lex is evaluated as an English specialist on these four workflows. For broader multilingual tasks, explore the general [Kai model](https://huggingface.co/llm-semantic-router/Decision-1.0-Kai).
|
| 58 |
+
|
| 59 |
+
## Make it yours
|
| 60 |
+
|
| 61 |
+
Run the [Python examples](USAGE.md), or adapt Lex to your own labels and rubrics with the included [fine-tuning CLI](FINETUNING.md). Both hard and soft training labels are supported, with checkpoint resume.
|
| 62 |
+
|
| 63 |
+
The complete 1,024-token budget includes context, instructions, all candidates and special tokens. Overlength requests return an error. Native Choice and Score support 2–255 candidates or ordered levels; the Studio adapter uses 2–10 Score levels.
|
| 64 |
+
|
| 65 |
+
## Architecture
|
| 66 |
+
|
| 67 |
+

|
| 68 |
+
|
| 69 |
+
Three 22-layer bidirectional encoder paths share multilingual input embeddings, with separate interaction layers and candidate readouts for Choice, Noul and Score. Lex retains Kai's architecture and specializes its weights through supervised fine-tuning.
|
| 70 |
+
|
| 71 |
+
[Architecture details](ARCHITECTURE.md) · [Training and methods](METHODS.md)
|
| 72 |
+
|
| 73 |
+
Built on [Kai](https://huggingface.co/llm-semantic-router/Decision-1.0-Kai) and [Vela Encoder](https://huggingface.co/llm-semantic-router/Vela-1.0-Encoder-307M). Probabilities are not calibrated confidence; candidate order and task wording can affect outputs. [Attribution and retained third-party terms](NOTICE) · [License scope](LICENSING_STATUS.md).
|
TECHNICAL_VALIDATION.json
ADDED
|
@@ -0,0 +1,55 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"TEST_rows": 0,
|
| 3 |
+
"actual_output_closure_sha256": "7ab577af71b775ea78529f40e29c02cb4dabc104b7a7c520a34cf7260a12691e",
|
| 4 |
+
"all_parameter_content_and_versions_unchanged": true,
|
| 5 |
+
"application_imports_confined_to_package": true,
|
| 6 |
+
"batch_sizes": [
|
| 7 |
+
8,
|
| 8 |
+
8,
|
| 9 |
+
8,
|
| 10 |
+
8,
|
| 11 |
+
8,
|
| 12 |
+
8,
|
| 13 |
+
8,
|
| 14 |
+
8
|
| 15 |
+
],
|
| 16 |
+
"calls": 8,
|
| 17 |
+
"complete1K": true,
|
| 18 |
+
"device_family": "AMD ROCm",
|
| 19 |
+
"gradients_none": true,
|
| 20 |
+
"initial_diagnostic_attempt": {
|
| 21 |
+
"forward_calls": 0,
|
| 22 |
+
"model_loads": 0,
|
| 23 |
+
"model_or_package_change": false,
|
| 24 |
+
"result": "mechanical argument-path reader error before model load; corrected in separate attempt"
|
| 25 |
+
},
|
| 26 |
+
"is_latency_benchmark": false,
|
| 27 |
+
"is_quality_evaluation": false,
|
| 28 |
+
"native_manifest_sha256": "f288d873999832a3f37c6a7c4268c2ab309691e621794dbf7acab891acbbb7e6",
|
| 29 |
+
"parameter_tensors": 489,
|
| 30 |
+
"parameters": 571909635,
|
| 31 |
+
"parity_against_independent_final_refit_fresh": {
|
| 32 |
+
"hard_flips": 0,
|
| 33 |
+
"logit_atol": 0.0001,
|
| 34 |
+
"max_logit_difference": 0.0,
|
| 35 |
+
"max_probability_difference": 0.0,
|
| 36 |
+
"pass": true,
|
| 37 |
+
"probability_atol": 2e-05
|
| 38 |
+
},
|
| 39 |
+
"peak_allocated_bytes": 2642393088,
|
| 40 |
+
"peak_reserved_bytes": 2768240640,
|
| 41 |
+
"precision": "FP32 SDPA",
|
| 42 |
+
"python_isolated": true,
|
| 43 |
+
"rows": 64,
|
| 44 |
+
"runtime_versions": {
|
| 45 |
+
"numpy": "2.5.3",
|
| 46 |
+
"safetensors": "0.8.0",
|
| 47 |
+
"tokenizers": "0.22.2",
|
| 48 |
+
"torch": "2.12.0+git6bbd260",
|
| 49 |
+
"transformers": "4.57.6"
|
| 50 |
+
},
|
| 51 |
+
"schema": "decision.lex.public-package-validation.v1",
|
| 52 |
+
"source_split": "original official TRAIN",
|
| 53 |
+
"status": "PASS_LEX_COMPLETE_PACKAGE_AMD",
|
| 54 |
+
"updates": 0
|
| 55 |
+
}
|
TRAINING_ATTRIBUTION.md
ADDED
|
@@ -0,0 +1,33 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Training-source attribution
|
| 2 |
+
|
| 3 |
+
Lex inherits the following training-source lineage through its fixed Kai parent. This package redistributes model artifacts and project code, not the source datasets. Dataset licenses remain with their authors; the model's MIT notice does not grant new rights to those texts or annotations.
|
| 4 |
+
|
| 5 |
+
| Source | Attribution and source terms |
|
| 6 |
+
|---|---|
|
| 7 |
+
| SNLI | Bowman, Angeli, Potts and Manning (2015), [Stanford Natural Language Inference](https://nlp.stanford.edu/projects/snli/); CC-BY-SA-4.0. |
|
| 8 |
+
| BoolQ | Clark et al. (2019), [Boolean Questions](https://github.com/google-research-datasets/boolean-questions); CC-BY-SA-3.0, with underlying Wikipedia attribution retained in source records. |
|
| 9 |
+
| ARC | Clark et al. (2018), [AI2 Reasoning Challenge](https://huggingface.co/datasets/allenai/ai2_arc); publisher metadata identifies CC-BY-SA-4.0. |
|
| 10 |
+
| MASSIVE | FitzGerald et al. (2022), [Amazon MASSIVE](https://github.com/alexa/massive), multilingual intent labels. |
|
| 11 |
+
| HelpSteer2 | Wang et al. (2024), [NVIDIA HelpSteer2](https://huggingface.co/datasets/nvidia/HelpSteer2), human ordinal response ratings. |
|
| 12 |
+
| KLUE-STS | Park et al. (2021), [KLUE](https://github.com/KLUE-benchmark/KLUE); retain the dataset's CC-BY-SA-4.0 terms. |
|
| 13 |
+
| JSTS and JCommonsenseQA | Kurihara, Kawahara and Shibata (2022), [JGLUE](https://github.com/yahoojapan/JGLUE/tree/6f071c09316baae89c3d083a90985b4b1cb9968c); CC-BY-SA-4.0. |
|
| 14 |
+
| Natural Instructions | Wang et al. (2022), [Super-NaturalInstructions](https://github.com/allenai/natural-instructions/tree/55a365637381ce7f3748fa2eac7aef1a113bbb82). Instruction definitions and dataset instances have distinct terms; the collection's code license does not replace instance-source licenses. |
|
| 15 |
+
| SocialIQA | Sap et al. (2019), [Social IQa](https://allenai.org/data/socialiqa); CC-BY-4.0. |
|
| 16 |
+
| QASC | Khot, Clark, Guerquin, Jansen and Sabharwal (2020), [QASC](https://github.com/allenai/qasc/blob/c44a320c2bb682d614a675d2ba4be072150db4eb/README.md); CC-BY-4.0. |
|
| 17 |
+
| Cosmos QA | Huang, Le Bras, Bhagavatula and Choi (2019), [Cosmos QA](https://github.com/wilburOne/cosmosqa/tree/b6eb99cca4e2a51dd28a9a6f562534872d851639); [official publisher card](https://huggingface.co/datasets/allenai/cosmos_qa) records CC-BY-4.0 and author confirmation. |
|
| 18 |
+
| TyDi QA | Clark et al. (2020), [TyDi QA](https://github.com/google-research-datasets/tydiqa); Apache-2.0 dataset/repository terms do not remove underlying Wikipedia attribution obligations. |
|
| 19 |
+
| OpenAssistant | Köpf et al. (2023), [OpenAssistant Conversations](https://huggingface.co/datasets/OpenAssistant/oasst1); Apache-2.0. Human quality/helpfulness annotations were used in training. |
|
| 20 |
+
| AfriSenti | Muhammad et al. (2023), [AfriSenti and SemEval-2023 Task 12](https://github.com/afrisenti-semeval/afrisent-semeval-2023/tree/5aec3cfcf87b59f885e98641f72e52182776429d); CC-BY-4.0. The upstream README also provides the NaijaSenti and ASAB citations. |
|
| 21 |
+
| SentiMix Hinglish | Patwa, Aguilar, Kar, Pandey, PYKL, Gambäck, Chakraborty, Solorio and Das (2020), [SemEval-2020 Task 9](https://aclanthology.org/2020.semeval-1.100/), [dataset DOI](https://doi.org/10.5281/zenodo.3974927); CC-BY-4.0. |
|
| 22 |
+
|
| 23 |
+
The Natural Instructions training families were query well-formedness (task 673), CaSiNo (353), ATOMIC (1216/1211), poem sentiment (833), HateXplain (1502/1503), WIQA (1548/1727), and ProPara (1568). Their recorded instance terms are respectively CC-BY-SA-4.0, CC-BY-4.0, CC-BY-4.0, CC-BY-4.0, MIT, Apache-2.0 and Apache-2.0. For WIQA and ProPara, this records the published NI instance declarations; it does not claim a separate re-audit of every original data archive. Qasper was a development family, not a training family.
|
| 24 |
+
|
| 25 |
+
Project transformations included explicit Choice/Noul/Score schemas, candidate identifiers, deterministic splits and component isolation, adjacent-level distributions for original continuous means, and one-hot representations of original hard labels. Sentiment categories remain coarse ordered sentiment, not fabricated continuous human quality ratings. TyDi uses the annotated supporting passage for Boolean prediction; it is not a retrieval task. OASST Spanish/Chinese rubrics and schema paraphrases were agent-authored changes, not new human annotations. Controlled rule/state examples were generated by the project. No original dataset is relicensed by these transformations.
|
| 26 |
+
|
| 27 |
+
Training-source attribution is distinct from evaluation-source attribution and from claims about what may have appeared in upstream encoder pretraining. Benchmark-only datasets and excluded candidates are not represented here as training sources.
|
| 28 |
+
|
| 29 |
+
## Lex specialization
|
| 30 |
+
|
| 31 |
+
Lex additionally uses the original TRAIN split of [LocalLLaMA/typed-decisions](https://huggingface.co/datasets/LocalLLaMA/typed-decisions), fixed revision `ea9306458d6e9563628369a3d1e72e362fb381d2`. The publisher identifies this English synthetic dataset as Apache-2.0. The 1,200 original cases contain 6,000 decisions across four workflows and 20 question schemas. The dataset's generated states and teacher-derived hard/soft targets measure agreement with that annotation process, not human ground truth or validated business outcomes.
|
| 32 |
+
|
| 33 |
+
The original TRAIN parquet SHA256 is `46a58d63edfd86e23229c78afe8b72307bb4ca9fb0e8df180cabb3c67ec9dcd5` (598,824 bytes). Lex preserves complete states, semantic candidates, question criteria, original hard labels, and explicitly normalized soft targets. The final training target is an equal mixture of the normalized soft distribution and the one-hot original hard label. All original TRAIN decisions appear exactly eight times. TEST was excluded from training and recipe selection. Dataset instances, gold labels, latent factors, and third-party model/SDK files are not included in this distribution.
|
TRAINING_PROVENANCE.json
ADDED
|
@@ -0,0 +1,65 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"active_path_tensors": 486,
|
| 3 |
+
"dataset": {
|
| 4 |
+
"TEST_used_for_training_or_selection": false,
|
| 5 |
+
"cases": 1200,
|
| 6 |
+
"decision_exposures": 48000,
|
| 7 |
+
"decisions": 6000,
|
| 8 |
+
"epochs": 8,
|
| 9 |
+
"original_split": "train",
|
| 10 |
+
"parquet_bytes": 598824,
|
| 11 |
+
"parquet_sha256": "46a58d63edfd86e23229c78afe8b72307bb4ca9fb0e8df180cabb3c67ec9dcd5",
|
| 12 |
+
"repo": "LocalLLaMA/typed-decisions",
|
| 13 |
+
"revision": "ea9306458d6e9563628369a3d1e72e362fb381d2"
|
| 14 |
+
},
|
| 15 |
+
"fresh_native_parity": {
|
| 16 |
+
"hard_flip_atol": 0,
|
| 17 |
+
"logit_atol": 0.0001,
|
| 18 |
+
"max_logit_difference": 0.0,
|
| 19 |
+
"max_probability_difference": 0.0,
|
| 20 |
+
"official_hard_flips": 0,
|
| 21 |
+
"pass": true,
|
| 22 |
+
"probability_atol": 2e-05,
|
| 23 |
+
"rows": 64
|
| 24 |
+
},
|
| 25 |
+
"frozen_training_plan_sha256": "d15c3cafd15d0ae14cf45e196d987016b304702f6f3930081b2ef30bbeabc638",
|
| 26 |
+
"language_scope": "English typed-decisions specialist",
|
| 27 |
+
"model": "Decision-1.0-Lex",
|
| 28 |
+
"native_files_unchanged": true,
|
| 29 |
+
"native_manifest_sha256": "f288d873999832a3f37c6a7c4268c2ab309691e621794dbf7acab891acbbb7e6",
|
| 30 |
+
"parameter_tensors": 489,
|
| 31 |
+
"parameters": 571909635,
|
| 32 |
+
"parent_native_manifest_sha256": "da603662bc57e89ccfb51c972ed9c1f2825f267597353cf1337df9117a3dfabe",
|
| 33 |
+
"provenance_scope": "Lex refit; not the Kai tensor-composition ledger or Kai evaluation/performance",
|
| 34 |
+
"python_version": "3.12.13",
|
| 35 |
+
"recipe": {
|
| 36 |
+
"DEV_evaluation_during_final_refit": false,
|
| 37 |
+
"bf16_autocast": true,
|
| 38 |
+
"clip_norm": 1.0,
|
| 39 |
+
"cosine_end_lr": 1e-06,
|
| 40 |
+
"encoder_lr": 2.5e-05,
|
| 41 |
+
"fixed_export_step": 750,
|
| 42 |
+
"head_lr": 0.0001,
|
| 43 |
+
"logical_batch_size": 64,
|
| 44 |
+
"loss": "cross_entropy(0.5*normalized_original_soft + 0.5*onehot_original_hard)",
|
| 45 |
+
"optimizer": "AdamW",
|
| 46 |
+
"parameter_precision": "fp32",
|
| 47 |
+
"physical_batch_size": 8,
|
| 48 |
+
"seed": 20260921,
|
| 49 |
+
"steps": 750,
|
| 50 |
+
"temperature_fit": false,
|
| 51 |
+
"warmup_steps": 0,
|
| 52 |
+
"weight_decay": 0.01
|
| 53 |
+
},
|
| 54 |
+
"runtime_versions": {
|
| 55 |
+
"numpy": "2.5.3",
|
| 56 |
+
"safetensors": "0.8.0",
|
| 57 |
+
"tokenizers": "0.22.2",
|
| 58 |
+
"torch": "2.12.0+git6bbd260",
|
| 59 |
+
"transformers": "4.57.6"
|
| 60 |
+
},
|
| 61 |
+
"schema": "decision.lex.training-provenance.v1",
|
| 62 |
+
"shared_frozen_tensors": 3,
|
| 63 |
+
"training_complete_sha256": "d0cc6eba0cc698cfc6538351ce0f7f73ccd7143be6a9431ad0dd3ae773ba2645",
|
| 64 |
+
"training_output_closure_sha256": "d3525627110ea2331d4e32d40303c61f2fd576b8222adfc69394177bc6e28142"
|
| 65 |
+
}
|
USAGE.md
ADDED
|
@@ -0,0 +1,31 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Run typed decisions
|
| 2 |
+
|
| 3 |
+
Open the [Lex model page](https://huggingface.co/llm-semantic-router/Decision-1.0-Lex), accept the distribution terms, then download the complete release with an authenticated Hugging Face CLI:
|
| 4 |
+
|
| 5 |
+
```bash
|
| 6 |
+
hf auth login
|
| 7 |
+
hf download llm-semantic-router/Decision-1.0-Lex --local-dir Decision-1.0-Lex
|
| 8 |
+
cd Decision-1.0-Lex
|
| 9 |
+
```
|
| 10 |
+
|
| 11 |
+
Use `--local-dir` to materialize ordinary files for the native loader. Install the pinned Python dependencies from `requirements.txt` in your compatible ROCm environment before running the examples.
|
| 12 |
+
|
| 13 |
+
This initial release bundles the verified native under `native/`, the public Python API. Run the following commands from the complete distribution root in a compatible environment. `PACKAGE_MANIFEST.json` records the exact payload; do not add files inside `native/` because its loader checks the complete file roster.
|
| 14 |
+
|
| 15 |
+
Use an existing compatible AMD ROCm environment. The verified source pins Transformers 4.57.6; tested companion versions were Python 3.12.13, tokenizers 0.22.2 and safetensors 0.8.0. Actual validation used a ROCm PyTorch 2.12 development build, not a promised generic wheel installation. Choose a matching supported ROCm/PyTorch installation for your host; this release does not supply an installer or a CPU/NVIDIA inference path. Do not upgrade an active environment in place.
|
| 16 |
+
|
| 17 |
+
```bash
|
| 18 |
+
export PYTHONPATH="$PWD${PYTHONPATH:+:$PYTHONPATH}"
|
| 19 |
+
export PYTHONDONTWRITEBYTECODE=1
|
| 20 |
+
export HF_HUB_OFFLINE=1 TRANSFORMERS_OFFLINE=1 TOKENIZERS_PARALLELISM=false
|
| 21 |
+
ROCR_VISIBLE_DEVICES=0 python infer.py \
|
| 22 |
+
--input examples/decisions.jsonl --output predictions.jsonl --batch-size 8
|
| 23 |
+
```
|
| 24 |
+
|
| 25 |
+
The three examples illustrate the Choice, Noul and Score interfaces. They are synthetic interface examples, not evaluated model predictions. Each input line has exactly `id`, `state_text`, and `question`; do not attach labels. Choice uses `options`, Score uses ordered `levels`, and Noul uses the fixed no/yes pair with optional `false_criterion`/`true_criterion`. IDs identify outputs and do not become model tokens.
|
| 26 |
+
|
| 27 |
+
The Python API returns original record/candidate identities, logits and probabilities in the supplied order. Choice includes the chosen candidate ID. Noul includes the yes probability; it does not emit a boolean decision. An application can choose first-argmax (an exact no/yes tie selects no) or `p_yes >= 0.5` (tie selects yes), but should declare that choice. Score includes `expected_value` over the supplied values and `score`, the expected ordinal index from 0 to K−1. Neither is automatically a calibrated business utility.
|
| 28 |
+
|
| 29 |
+
All state/question/candidate text and markers count toward the complete 1024 limit. `predict_1k` checks every input before the first forward and rejects overflow without truncation. Batch sizes 1–8 are supported by this wrapper. Use it rather than directly invoking the native research-capacity entrypoint.
|
| 30 |
+
|
| 31 |
+
A compatible fine-tuned export can be used with `--native <directory> --manifest-sha256 <trusted hash>`. Only the pinned runtime revision and three-path architecture are accepted. Downloaded HF symlinks must be materialized into real files before loading. The manifest hash is an integrity check, not a reason to execute arbitrary untrusted Python.
|
VALIDATION.md
ADDED
|
@@ -0,0 +1,9 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Technical validation
|
| 2 |
+
|
| 3 |
+
The final refit completed 750 updates and exported a native bundle with 571,909,635 parameters in 489 tensors. The initial 64 TRAIN decisions passed same-B8 native/all-types-wrapper parity. The first update had finite gradients across all 486 active tensors and actual parameter-content changes in each of the nine encoder/head/scorer groups. The shared three tensors remained unchanged.
|
| 4 |
+
|
| 5 |
+
After releasing the training model and optimizer, a separate process loaded the final native and repeated those 64 TRAIN decisions in eight FP32 batches. Logits and probabilities matched the saved final predictions exactly, with zero hard-label flips. This was a technical reload check, not another quality evaluation.
|
| 6 |
+
|
| 7 |
+
The public Python inference and fine-tuning modules are copied unchanged from the tested Kai distribution. Their strict loader verifies every native file and the runtime source allowlist before loading. The native runtime/tokenizer/geometry match the supported architecture; no research-directory import is required. The completed Lex package-isolation check loaded the bundled native through public `load_native` and evaluated the same 64 TRAIN decisions through `predict_1k` in eight FP32 batches. It ran with isolated Python from an external working directory, with all application imports confined to this package. Maximum logit/probability differences from the independent final-refit fresh reference were 0.0/0.0, with zero hard flips. All 489 parameter contents and versions were unchanged; no gradients, updates or TEST evaluation occurred. See [TECHNICAL_VALIDATION.json](TECHNICAL_VALIDATION.json).
|
| 8 |
+
|
| 9 |
+
The included fine-tuning CLI's earlier bounded continuous-versus-resume and independent-reload checks are interface evidence, not new Lex training results. Lex's final training used the fixed research recipe described in [METHODS.md](METHODS.md). The supported product profile is complete packed length ≤1,024 and FP32 inference on compatible AMD ROCm. No browser end-to-end latency, CPU/NVIDIA inference, multilingual-specialist quality or larger-window quality is claimed.
|
assets/architecture-atlas.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:ff64805a39d16be56d401166ef4d310da86305058bb2c532751754c8c34d49ee
|
| 3 |
+
size 635270
|
assets/architecture.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:6aa6895f5708cda7d935991cf9c1179d9e54e22a32459968a052acf05f62a14a
|
| 3 |
+
size 173099
|
assets/architecture.png
ADDED

|
Git LFS Details
|
assets/architecture.svg
ADDED
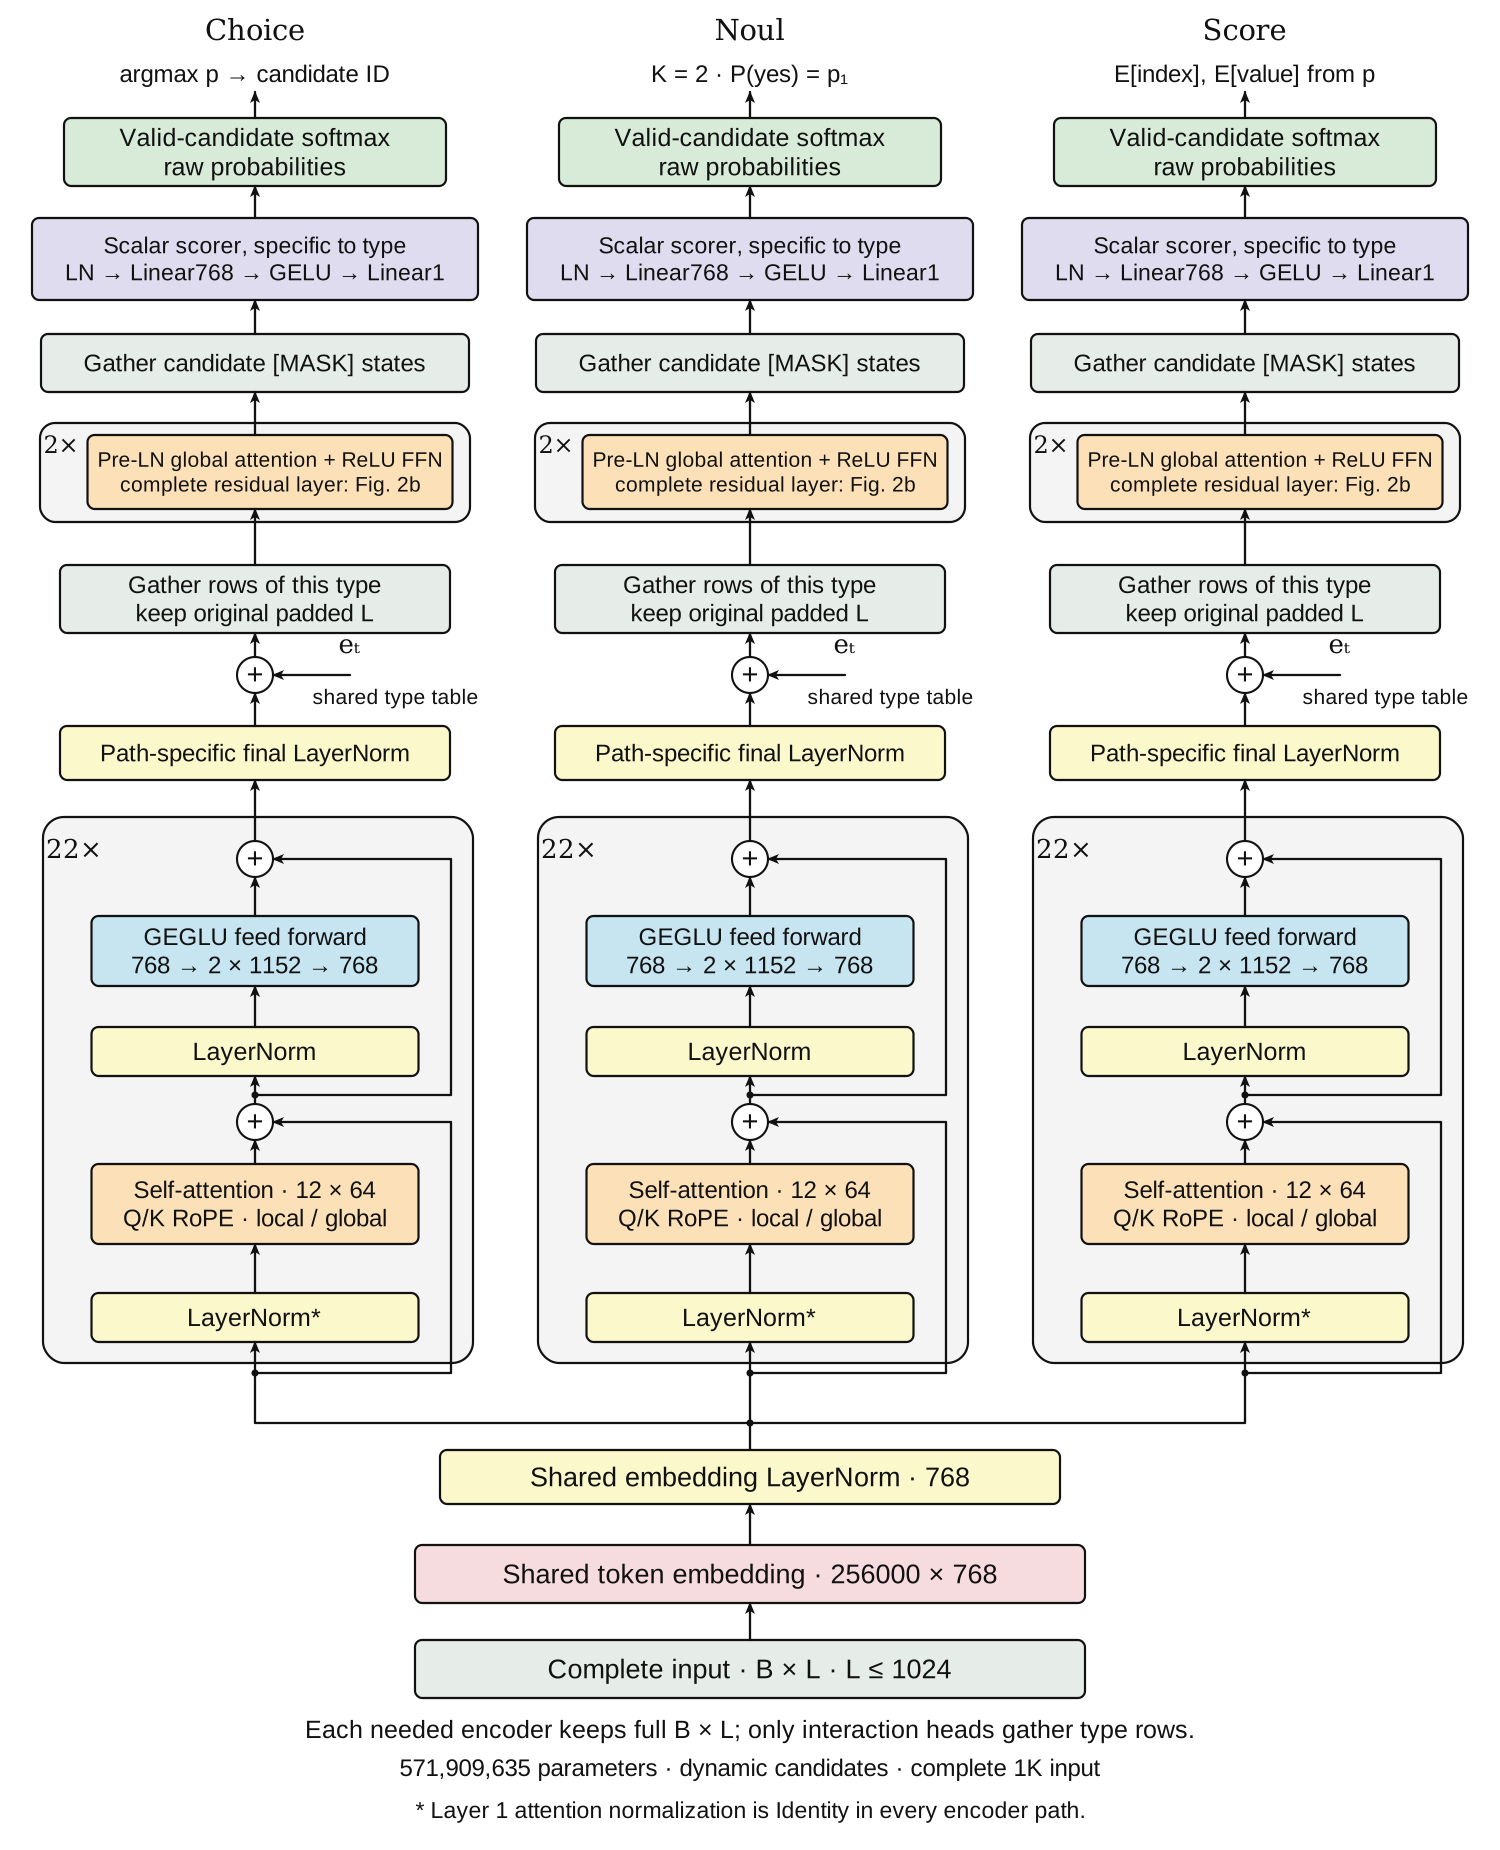
|
assets/attention-geglu.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:43b3485510971d29e66bc17b30b4bffe934ad66078598cc3e2efd63ae9b9bc7c
|
| 3 |
+
size 172797
|
assets/attention-geglu.png
ADDED

|
Git LFS Details
|
assets/attention-geglu.svg
ADDED
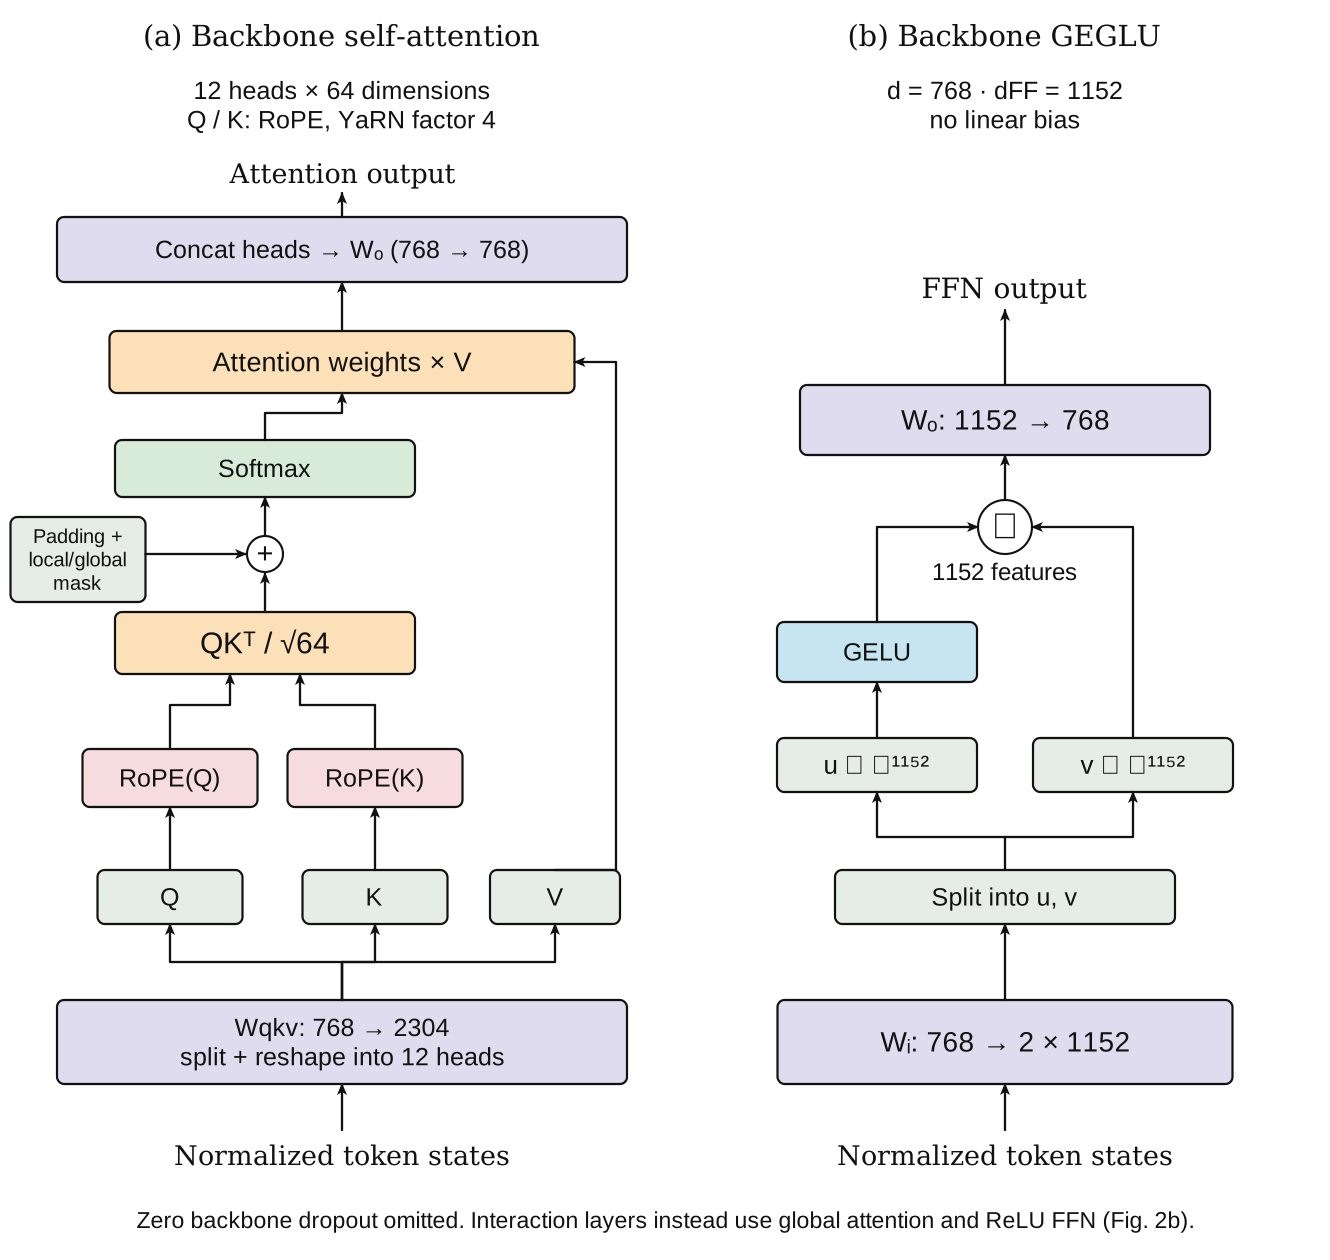
|
assets/candidate-readout.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:56b9e06a343e9044c38cfb8d1ba5ba121bdc7d763db5ce45b927aacdcb00c995
|
| 3 |
+
size 156814
|
assets/candidate-readout.png
ADDED

|
Git LFS Details
|
assets/candidate-readout.svg
ADDED
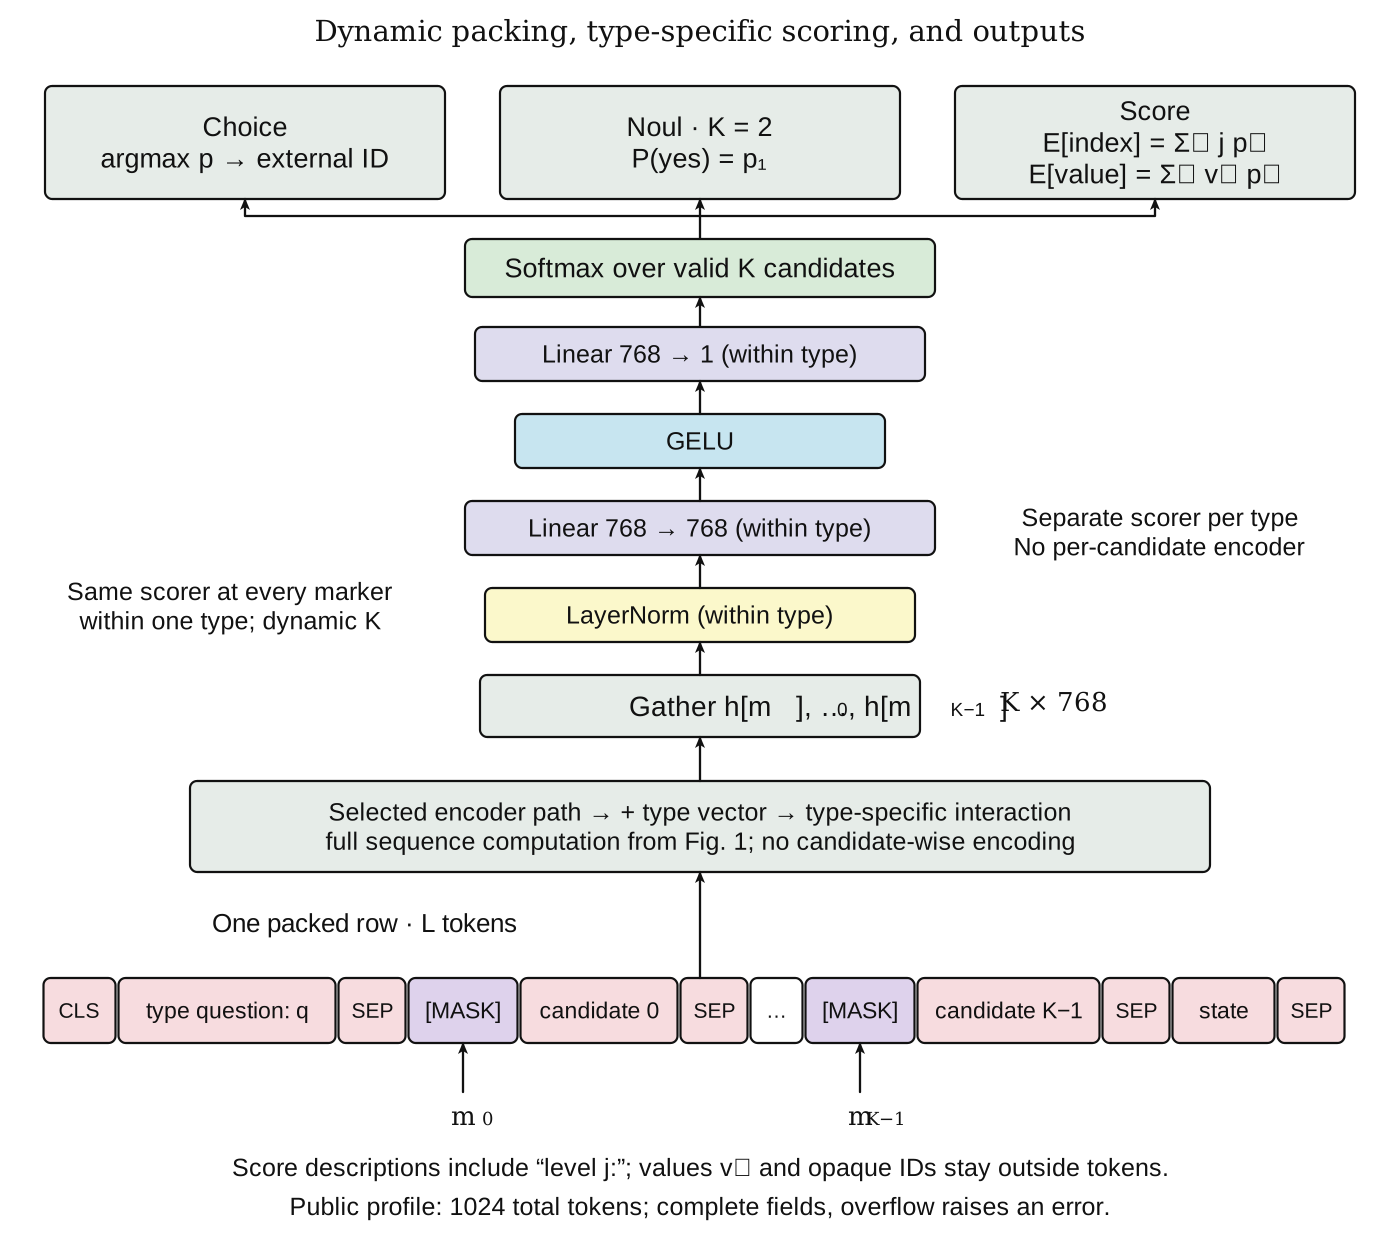
|
assets/decision-lex-header.png
ADDED

|
Git LFS Details
|
assets/residual-layers.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:2c5b50bb840ae115a1264b66d535a1048172e891a33d02d507c193525cc45630
|
| 3 |
+
size 131144
|
assets/residual-layers.png
ADDED

|
Git LFS Details
|
assets/residual-layers.svg
ADDED
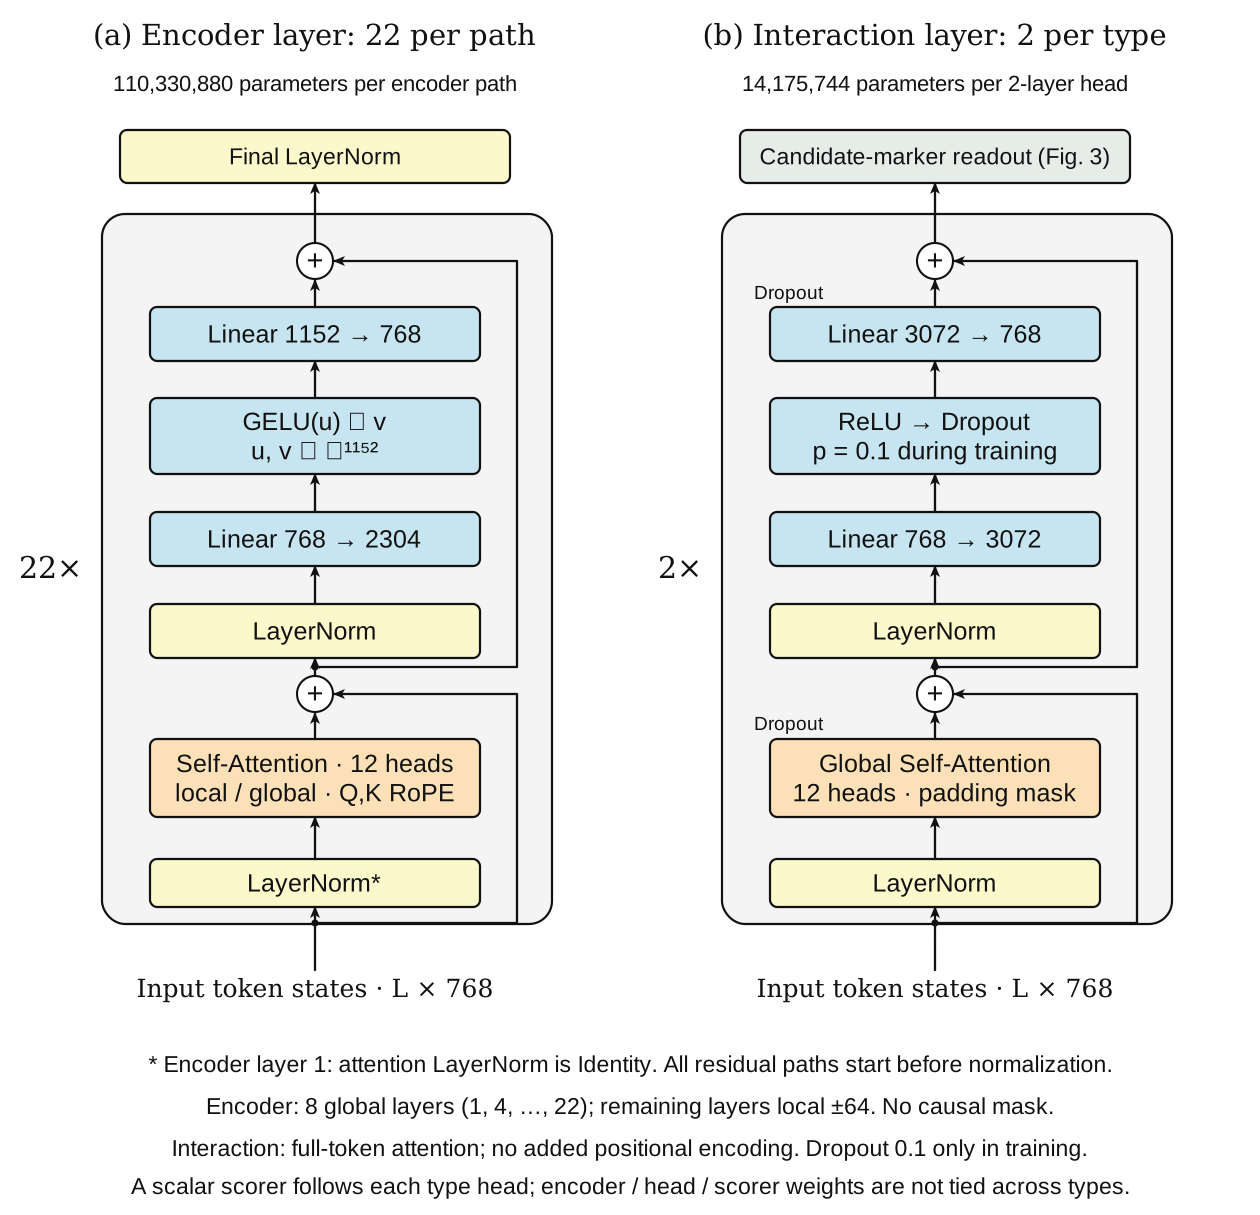
|
decision_finetune/__init__.py
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
"""Portable JSONL fine-tuning CLI; end-to-end AMD validation remains pending."""
|
decision_finetune/__main__.py
ADDED
|
@@ -0,0 +1,80 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Run with PYTHONPATH=<release directory> python -m decision_finetune."""
|
| 2 |
+
import argparse
|
| 3 |
+
import json
|
| 4 |
+
import math
|
| 5 |
+
import sys
|
| 6 |
+
from . import data
|
| 7 |
+
|
| 8 |
+
|
| 9 |
+
def parser():
|
| 10 |
+
p = argparse.ArgumentParser(description="Single-AMD full1K native Choice/Noul/Score fine-tuning")
|
| 11 |
+
commands = p.add_subparsers(dest="command", required=True)
|
| 12 |
+
v = commands.add_parser("validate-jsonl", help="Structural/split checks only; does NOT establish token support")
|
| 13 |
+
v.add_argument("--train", required=True); v.add_argument("--dev", required=True)
|
| 14 |
+
v.add_argument("--selection", choices=("macro-nll", "hard-accuracy"), default="macro-nll")
|
| 15 |
+
t = commands.add_parser("train", help="Loads a real AMD model; complete admission precedes every forward")
|
| 16 |
+
for name in ("native", "manifest-sha256", "train", "dev", "output"):
|
| 17 |
+
t.add_argument("--" + name, required=True)
|
| 18 |
+
t.add_argument("--epochs", type=int, default=4)
|
| 19 |
+
t.add_argument("--logical-batch-size", type=int, default=64)
|
| 20 |
+
t.add_argument("--micro-batch-size", type=int, default=8)
|
| 21 |
+
t.add_argument("--seed", type=int, default=20260921)
|
| 22 |
+
t.add_argument("--encoder-lr", type=float, default=2.5e-5)
|
| 23 |
+
t.add_argument("--head-lr", type=float, default=1e-4)
|
| 24 |
+
t.add_argument("--lr-min", type=float, default=1e-6)
|
| 25 |
+
t.add_argument("--weight-decay", type=float, default=.01)
|
| 26 |
+
t.add_argument("--clip-norm", type=float, default=1.)
|
| 27 |
+
t.add_argument("--score-rps-weight", type=float, default=.1)
|
| 28 |
+
t.add_argument("--warmup-steps", type=int)
|
| 29 |
+
t.add_argument("--warmup-ratio", type=float, default=.1)
|
| 30 |
+
t.add_argument("--max-steps", type=int)
|
| 31 |
+
t.add_argument("--eval-steps", help="Explicit comma-separated update steps including0/final; default epoch ends")
|
| 32 |
+
t.add_argument("--selection", choices=("macro-nll", "hard-accuracy"), default="macro-nll")
|
| 33 |
+
t.add_argument("--selection-tolerance", type=float, default=1e-8)
|
| 34 |
+
t.add_argument("--save-every", type=int, default=0, help="Additional update-boundary checkpoints;0 means evaluation points only")
|
| 35 |
+
t.add_argument("--cpu-threads", type=int, default=2)
|
| 36 |
+
t.add_argument("--max-reserved-gib", type=float, default=64.)
|
| 37 |
+
t.add_argument("--allow-nondeterministic-kernels", action="store_true", help="Explicitly opt out of PyTorch deterministic algorithm enforcement")
|
| 38 |
+
t.add_argument("--resume", help="Existing immutable update-boundary checkpoint directory")
|
| 39 |
+
t.add_argument("--resume-sha256", help="Trusted manifest SHA for --resume")
|
| 40 |
+
t.add_argument("--stop-after-step", type=int, help="Clean scheduling pause after this original update; does not change the LR horizon or training config")
|
| 41 |
+
return p
|
| 42 |
+
|
| 43 |
+
|
| 44 |
+
def configuration(args):
|
| 45 |
+
fields = ("epochs", "logical_batch_size", "micro_batch_size", "seed", "encoder_lr", "head_lr", "lr_min", "weight_decay",
|
| 46 |
+
"clip_norm", "score_rps_weight", "warmup_steps", "warmup_ratio", "max_steps", "selection", "selection_tolerance",
|
| 47 |
+
"save_every", "cpu_threads", "max_reserved_gib")
|
| 48 |
+
c = {k: getattr(args, k) for k in fields}
|
| 49 |
+
data.need(all(c[k] > 0 for k in ("epochs", "logical_batch_size", "micro_batch_size", "cpu_threads")), "Positive counts required")
|
| 50 |
+
data.need(c["micro_batch_size"] <= c["logical_batch_size"] and c["micro_batch_size"] <= 8, "Micro batch must fit logical batch and ≤8")
|
| 51 |
+
data.need(0 <= c["seed"] < 2**32 and c["save_every"] >= 0, "Invalid seed/save cadence")
|
| 52 |
+
data.need(all(math.isfinite(c[k]) and c[k] > 0 for k in ("encoder_lr", "head_lr", "clip_norm", "max_reserved_gib")), "Positive finite optimizer/memory values")
|
| 53 |
+
data.need(c["max_reserved_gib"] <= 64 and all(math.isfinite(c[k]) and c[k] >= 0 for k in ("weight_decay", "score_rps_weight", "selection_tolerance"))
|
| 54 |
+
and 0 <= c["warmup_ratio"] < 1, "Invalid budget/objective/warmup")
|
| 55 |
+
data.need(math.isfinite(c["lr_min"]) and 0 <= c["lr_min"] <= min(c["encoder_lr"], c["head_lr"]), "Invalid LR floor")
|
| 56 |
+
data.need(bool(args.resume) == bool(args.resume_sha256), "Resume directory AND manifest SHA required")
|
| 57 |
+
c.update(eval_steps=None if args.eval_steps is None else [int(v) for v in args.eval_steps.split(",")],
|
| 58 |
+
deterministic_algorithms=not args.allow_nondeterministic_kernels,
|
| 59 |
+
train_precision="bf16_autocast_fp32_parameters_loss", eval_precision="fp32", eval_batch_size=8,
|
| 60 |
+
lr_convention="linear warmup to base, then cosine to lr_min at final; with no warmup step1=base; one-step schedule uses base",
|
| 61 |
+
input_limit=1024, truncation="error", selection_weighting=("equal_present_types" if args.selection == "macro-nll" else "row"))
|
| 62 |
+
return c
|
| 63 |
+
|
| 64 |
+
|
| 65 |
+
def main():
|
| 66 |
+
sys.dont_write_bytecode = True
|
| 67 |
+
args = parser().parse_args()
|
| 68 |
+
if args.command == "validate-jsonl":
|
| 69 |
+
train, dev = data.load_splits(args.train, args.dev, args.selection)
|
| 70 |
+
print(json.dumps({"status": "PASS_JSONL_AND_EXACT_SPLIT_CHECKS", "train_rows": len(train), "dev_rows": len(dev),
|
| 71 |
+
"train_sha256": data.file_sha(args.train), "dev_sha256": data.file_sha(args.dev),
|
| 72 |
+
"token_admission_performed": False, "model_calls": 0}))
|
| 73 |
+
return
|
| 74 |
+
from .run import execute
|
| 75 |
+
result = execute(args, configuration(args))
|
| 76 |
+
print(json.dumps({k: result[k] for k in ("status", "native", "native_manifest_sha256", "selected0_no_adaptation", "checkpoint") if k in result}))
|
| 77 |
+
|
| 78 |
+
|
| 79 |
+
if __name__ == "__main__":
|
| 80 |
+
main()
|
decision_finetune/data.py
ADDED
|
@@ -0,0 +1,139 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""JSONL, split and deterministic schedule contracts. No model imports."""
|
| 2 |
+
import copy
|
| 3 |
+
import hashlib
|
| 4 |
+
import json
|
| 5 |
+
import math
|
| 6 |
+
from pathlib import Path
|
| 7 |
+
import unicodedata
|
| 8 |
+
|
| 9 |
+
KINDS = ("choice", "noul", "score")
|
| 10 |
+
DEFAULT_NO = "No. The statement or question is not satisfied."
|
| 11 |
+
DEFAULT_YES = "Yes. The statement or question is satisfied."
|
| 12 |
+
|
| 13 |
+
|
| 14 |
+
def need(ok, message):
|
| 15 |
+
if not ok:
|
| 16 |
+
raise ValueError(message)
|
| 17 |
+
|
| 18 |
+
|
| 19 |
+
def digest(value):
|
| 20 |
+
return hashlib.sha256(json.dumps(value, ensure_ascii=False, sort_keys=True,
|
| 21 |
+
separators=(",", ":"), allow_nan=False).encode()).hexdigest()
|
| 22 |
+
|
| 23 |
+
|
| 24 |
+
def file_sha(path):
|
| 25 |
+
h = hashlib.sha256()
|
| 26 |
+
with Path(path).open("rb") as stream:
|
| 27 |
+
for chunk in iter(lambda: stream.read(1 << 20), b""):
|
| 28 |
+
h.update(chunk)
|
| 29 |
+
return h.hexdigest()
|
| 30 |
+
|
| 31 |
+
|
| 32 |
+
def text(value):
|
| 33 |
+
need(isinstance(value, str) and value.strip(), "Nonempty text required")
|
| 34 |
+
return " ".join(unicodedata.normalize("NFKC", value).casefold().split())
|
| 35 |
+
|
| 36 |
+
|
| 37 |
+
def semantics(row):
|
| 38 |
+
need(isinstance(row, dict) and isinstance(row.get("question"), dict), "Record/question objects required")
|
| 39 |
+
text(row.get("id")); text(row.get("state_text"))
|
| 40 |
+
q = row["question"]; text(q.get("text"))
|
| 41 |
+
kind = str(q.get("type", "")).lower()
|
| 42 |
+
need(kind in KINDS, "Question type must be Choice, Noul or Score")
|
| 43 |
+
if kind == "noul":
|
| 44 |
+
options = [{"id": "no", "text": q.get("false_criterion", DEFAULT_NO)},
|
| 45 |
+
{"id": "yes", "text": q.get("true_criterion", DEFAULT_YES)}]
|
| 46 |
+
else:
|
| 47 |
+
options = q.get("options" if kind == "choice" else "levels")
|
| 48 |
+
need(isinstance(options, list) and 2 <= len(options) <= 255, "Require 2..255 candidates")
|
| 49 |
+
for option in options:
|
| 50 |
+
need(isinstance(option, dict), "Candidate object required")
|
| 51 |
+
text(option.get("id")); text(option.get("text"))
|
| 52 |
+
ids = [o["id"] for o in options]
|
| 53 |
+
need(len(set(ids)) == len(ids), "Candidate IDs must be unique")
|
| 54 |
+
values = [float(o["value"]) for o in options] if kind == "score" else list(range(len(ids)))
|
| 55 |
+
need(all(math.isfinite(v) for v in values) and all(a < b for a, b in zip(values, values[1:])), "Increasing finite Score values")
|
| 56 |
+
gold = row.get("target")
|
| 57 |
+
need(isinstance(gold, dict), "Explicit target required")
|
| 58 |
+
if kind == "noul":
|
| 59 |
+
need(set(gold) == {"probability"}, "Noul target is probability of yes")
|
| 60 |
+
yes = float(gold["probability"]); target = [1 - yes, yes]
|
| 61 |
+
elif set(gold) == {"probabilities"}:
|
| 62 |
+
target = [float(p) for p in gold["probabilities"]]
|
| 63 |
+
else:
|
| 64 |
+
need(kind == "choice" and set(gold) == {"choice_id"} and gold["choice_id"] in ids,
|
| 65 |
+
"Choice needs choice_id/probabilities; Score needs probabilities (one-hot is hard)")
|
| 66 |
+
target = [float(cid == gold["choice_id"]) for cid in ids]
|
| 67 |
+
need(len(target) == len(ids) and all(math.isfinite(p) and 0 <= p <= 1 for p in target)
|
| 68 |
+
and abs(sum(target) - 1) <= 1e-6, "Normalized finite hard/soft target required")
|
| 69 |
+
hard = row.get("hard_target_id")
|
| 70 |
+
need(hard is None or hard in ids, "hard_target_id must be an original candidate ID")
|
| 71 |
+
return kind, options, values, target
|
| 72 |
+
|
| 73 |
+
|
| 74 |
+
def input_signature(row):
|
| 75 |
+
kind, options, values, _ = semantics(row)
|
| 76 |
+
descriptions = [text(o["text"]) for o in options]
|
| 77 |
+
if kind == "choice":
|
| 78 |
+
descriptions.sort() # Reordering and opaque IDs cannot hide exact split overlap.
|
| 79 |
+
return digest({"kind": kind, "state": text(row["state_text"]),
|
| 80 |
+
"question": text(row["question"]["text"]), "descriptions": descriptions,
|
| 81 |
+
"values": values if kind == "score" else None})
|
| 82 |
+
|
| 83 |
+
|
| 84 |
+
def model_row(row):
|
| 85 |
+
# External hard evaluation labels are never passed to the collator/model.
|
| 86 |
+
return copy.deepcopy({k: v for k, v in row.items() if k != "hard_target_id"})
|
| 87 |
+
|
| 88 |
+
|
| 89 |
+
def read_jsonl(path):
|
| 90 |
+
rows = []
|
| 91 |
+
with Path(path).open(encoding="utf-8") as stream:
|
| 92 |
+
for number, line in enumerate(stream, 1):
|
| 93 |
+
need(bool(line.strip()), f"Blank JSONL line {number}")
|
| 94 |
+
row = json.loads(line); semantics(row); rows.append(row)
|
| 95 |
+
need(bool(rows) and len({r["id"] for r in rows}) == len(rows), "Nonempty split with unique IDs required")
|
| 96 |
+
return rows
|
| 97 |
+
|
| 98 |
+
|
| 99 |
+
def load_splits(train_path, dev_path, selection):
|
| 100 |
+
train, dev = read_jsonl(train_path), read_jsonl(dev_path)
|
| 101 |
+
need(not ({r["id"] for r in train} & {r["id"] for r in dev}), "TRAIN/DEV IDs overlap")
|
| 102 |
+
need(not ({input_signature(r) for r in train} & {input_signature(r) for r in dev}),
|
| 103 |
+
"TRAIN/DEV normalized complete inputs overlap")
|
| 104 |
+
# When both fields are supplied, also reject same-source dependency components.
|
| 105 |
+
components = lambda rows: {(r["source_id"], r["component_id"]) for r in rows
|
| 106 |
+
if r.get("source_id") and r.get("component_id")}
|
| 107 |
+
need(not (components(train) & components(dev)), "TRAIN/DEV source components overlap")
|
| 108 |
+
if selection == "hard-accuracy":
|
| 109 |
+
need(all(r.get("hard_target_id") is not None for r in dev),
|
| 110 |
+
"Hard-accuracy selection requires explicit hard_target_id on EVERY DEV row")
|
| 111 |
+
return train, dev
|
| 112 |
+
|
| 113 |
+
|
| 114 |
+
def make_schedule(rows, epochs, logical_batch, seed, max_steps=None):
|
| 115 |
+
steps, epoch_ends = [], []
|
| 116 |
+
for epoch in range(epochs):
|
| 117 |
+
order = sorted(range(len(rows)), key=lambda i: (digest([seed, epoch, rows[i]["id"]]), rows[i]["id"]))
|
| 118 |
+
steps.extend([order[i:i + logical_batch] for i in range(0, len(order), logical_batch)])
|
| 119 |
+
epoch_ends.append(len(steps))
|
| 120 |
+
if max_steps is not None:
|
| 121 |
+
need(1 <= max_steps <= len(steps), "max-steps must fit the declared epochs; no implicit extra epochs")
|
| 122 |
+
steps = steps[:max_steps]
|
| 123 |
+
return steps, sorted(set([0, len(steps)] + [s for s in epoch_ends if s <= len(steps)]))
|
| 124 |
+
|
| 125 |
+
|
| 126 |
+
def admit(collator, rows):
|
| 127 |
+
need(collator.max_length == 1024 and collator.state_truncation == "error", "Full1K collator required")
|
| 128 |
+
evidence = {}
|
| 129 |
+
for row in rows:
|
| 130 |
+
e = collator.encode(model_row(row), labeled=True)
|
| 131 |
+
kind, options, values, target = semantics(row)
|
| 132 |
+
need(e["id"] == row["id"] and e["kind"] == kind and e["target"] == target
|
| 133 |
+
and e["candidate_ids"] == [o["id"] for o in options] and e["values"] == values,
|
| 134 |
+
"CLI schema and loaded native collator disagree")
|
| 135 |
+
need(e["state_tokens_original"] == e["state_tokens_kept"] and e["input_tokens"] == len(e["ids"]) <= 1024,
|
| 136 |
+
"Complete input exceeds1K or was truncated; no rows are silently dropped")
|
| 137 |
+
evidence[row["id"]] = {"encoded_sha256": digest(e), "input_tokens": len(e["ids"]),
|
| 138 |
+
"token_ids_sha256": digest(e["ids"]), "record_sha256": digest(row)}
|
| 139 |
+
return evidence
|
decision_finetune/metrics.py
ADDED
|
@@ -0,0 +1,61 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Explicit DEV metrics/selectors; no external benchmark or hidden retention gates."""
|
| 2 |
+
import math
|
| 3 |
+
from collections import defaultdict
|
| 4 |
+
from .data import need, semantics
|
| 5 |
+
|
| 6 |
+
|
| 7 |
+
def summarize(rows, predictions):
|
| 8 |
+
need(len(rows) == len(predictions) > 0, "Complete DEV predictions required")
|
| 9 |
+
groups = defaultdict(list)
|
| 10 |
+
for row, p in zip(rows, predictions):
|
| 11 |
+
kind, options, values, target = semantics(row)
|
| 12 |
+
ids = [o["id"] for o in options]; z = p["logits"]; probs = p["probabilities"]
|
| 13 |
+
need(p["id"] == row["id"] and p["type"].lower() == kind and p["candidate_ids"] == ids,
|
| 14 |
+
"Prediction ID/type/order mismatch")
|
| 15 |
+
need(len(z) == len(probs) == len(ids) and all(math.isfinite(v) for v in z + probs)
|
| 16 |
+
and all(0 <= v <= 1 for v in probs) and abs(sum(probs) - 1) <= 1e-5, "Invalid probabilities/logits")
|
| 17 |
+
peak = max(z); logsum = peak + math.log(sum(math.exp(v - peak) for v in z))
|
| 18 |
+
need(max(abs(math.exp(v - logsum) - p) for v, p in zip(z, probs)) <= 2e-5,
|
| 19 |
+
"Probabilities disagree with saved logits")
|
| 20 |
+
# NLL from logits avoids an arbitrary probability floor.
|
| 21 |
+
nll = sum(t * (logsum - v) for t, v in zip(target, z))
|
| 22 |
+
native_hat = max(range(len(probs)), key=probs.__getitem__)
|
| 23 |
+
# Original typed evaluation convention, distinct from native first argmax at exact ties.
|
| 24 |
+
hat = int(probs[1] >= .5) if kind == "noul" else native_hat
|
| 25 |
+
item = {"nll": nll, "hard_accuracy": None if row.get("hard_target_id") is None else float(ids[hat] == row["hard_target_id"]),
|
| 26 |
+
"native_argmax_accuracy": None if row.get("hard_target_id") is None else float(ids[native_hat] == row["hard_target_id"])}
|
| 27 |
+
if kind == "score":
|
| 28 |
+
pc = tc = rps = 0.
|
| 29 |
+
for a, b in zip(probs[:-1], target[:-1]):
|
| 30 |
+
pc += a; tc += b; rps += (pc - tc) ** 2
|
| 31 |
+
item["rps"] = rps / (len(ids) - 1)
|
| 32 |
+
item["expected_value_squared_error"] = (sum(a * v for a, v in zip(probs, values)) - sum(a * v for a, v in zip(target, values))) ** 2
|
| 33 |
+
groups[kind].append(item)
|
| 34 |
+
def report(items):
|
| 35 |
+
result = {"rows": len(items), "soft_nll": sum(x["nll"] for x in items) / len(items)}
|
| 36 |
+
result["hard_accuracy"] = (sum(x["hard_accuracy"] for x in items) / len(items)
|
| 37 |
+
if all(x["hard_accuracy"] is not None for x in items) else None)
|
| 38 |
+
result["native_argmax_accuracy_diagnostic"] = (sum(x["native_argmax_accuracy"] for x in items) / len(items)
|
| 39 |
+
if all(x["native_argmax_accuracy"] is not None for x in items) else None)
|
| 40 |
+
if all("rps" in x for x in items):
|
| 41 |
+
result.update(rps=sum(x["rps"] for x in items) / len(items),
|
| 42 |
+
expected_value_rmse=math.sqrt(sum(x["expected_value_squared_error"] for x in items) / len(items)))
|
| 43 |
+
return result
|
| 44 |
+
by_type = {kind: report(items) for kind, items in groups.items()}
|
| 45 |
+
return {"by_type": by_type, "row": report([x for items in groups.values() for x in items]),
|
| 46 |
+
"macro_soft_nll": sum(x["soft_nll"] for x in by_type.values()) / len(by_type),
|
| 47 |
+
"macro_weighting": "equal weight for each type present in DEV; row mean within type",
|
| 48 |
+
"hard_rule": "Noul p_yes>=0.5; Choice/Score original-order first argmax",
|
| 49 |
+
"native_argmax_diagnostic": "original-order first argmax for every type; Noul exact tie no"}
|
| 50 |
+
|
| 51 |
+
|
| 52 |
+
def better(candidate, best, selection, tolerance=1e-8):
|
| 53 |
+
if best is None:
|
| 54 |
+
return True
|
| 55 |
+
a, b = candidate["metrics"], best["metrics"]
|
| 56 |
+
if selection == "macro-nll":
|
| 57 |
+
return a["macro_soft_nll"] < b["macro_soft_nll"] - tolerance
|
| 58 |
+
need(selection == "hard-accuracy" and a["row"]["hard_accuracy"] is not None
|
| 59 |
+
and b["row"]["hard_accuracy"] is not None, "Explicit complete hard labels required")
|
| 60 |
+
delta = a["row"]["hard_accuracy"] - b["row"]["hard_accuracy"]
|
| 61 |
+
return delta > tolerance or (abs(delta) <= tolerance and a["row"]["soft_nll"] < b["row"]["soft_nll"] - tolerance)
|
decision_finetune/run.py
ADDED
|
@@ -0,0 +1,237 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Single-device training orchestration over the public API, with no research paths."""
|
| 2 |
+
import gc
|
| 3 |
+
import importlib.metadata
|
| 4 |
+
import json
|
| 5 |
+
import os
|
| 6 |
+
from pathlib import Path
|
| 7 |
+
import random
|
| 8 |
+
import sys
|
| 9 |
+
import time
|
| 10 |
+
|
| 11 |
+
from . import data, metrics, state
|
| 12 |
+
|
| 13 |
+
|
| 14 |
+
def source_identity():
|
| 15 |
+
import decision_runtime
|
| 16 |
+
roots = {"decision_finetune": Path(__file__).parent,
|
| 17 |
+
"decision_runtime": Path(decision_runtime.__file__).parent}
|
| 18 |
+
return {package + "/" + p.name: data.file_sha(p) for package, root in roots.items()
|
| 19 |
+
for p in sorted(root.glob("*.py")) if p.name not in ("checks.py", "bridge_checks.py")}
|
| 20 |
+
|
| 21 |
+
|
| 22 |
+
def setup(config):
|
| 23 |
+
import numpy as np
|
| 24 |
+
import torch
|
| 25 |
+
data.need(torch.version.hip is not None and torch.cuda.is_available() and torch.cuda.device_count() == 1,
|
| 26 |
+
"Expose exactly one real AMD ROCm device; CPU/NVIDIA training is unsupported")
|
| 27 |
+
torch.cuda.set_device(0); torch.set_num_threads(config["cpu_threads"])
|
| 28 |
+
torch.backends.cuda.matmul.allow_tf32 = False; torch.backends.cudnn.allow_tf32 = False
|
| 29 |
+
torch.backends.mha.set_fastpath_enabled(False)
|
| 30 |
+
torch.use_deterministic_algorithms(config["deterministic_algorithms"])
|
| 31 |
+
torch.cuda.set_per_process_memory_fraction(min(1., config["max_reserved_gib"] * 2**30 / torch.cuda.get_device_properties(0).total_memory))
|
| 32 |
+
random.seed(config["seed"]); np.random.seed(config["seed"]); torch.manual_seed(config["seed"])
|
| 33 |
+
environment = {"python": sys.version.split()[0], "rocm": torch.version.hip,
|
| 34 |
+
"gpu": torch.cuda.get_device_name(0),
|
| 35 |
+
"versions": {n: importlib.metadata.version(n) for n in ("torch", "transformers", "tokenizers", "safetensors", "numpy")}}
|
| 36 |
+
return torch, environment
|
| 37 |
+
|
| 38 |
+
|
| 39 |
+
def check_memory(torch, config):
|
| 40 |
+
data.need(torch.cuda.max_memory_reserved() <= config["max_reserved_gib"] * 2**30, "Reserved GPU memory cap exceeded")
|
| 41 |
+
|
| 42 |
+
|
| 43 |
+
def evaluation(api, native, dev, admission, out, step, torch):
|
| 44 |
+
# Parameter objects and optimizer state survive policy restoration unchanged.
|
| 45 |
+
api.restore_native_policy_for_export(native)
|
| 46 |
+
predictions = api.predict(native, [data.model_row(r) for r in dev], batch_size=8)
|
| 47 |
+
for row, p in zip(dev, predictions):
|
| 48 |
+
data.need(p["input_tokens"] == admission[row["id"]]["input_tokens"] <= 1024
|
| 49 |
+
and p["state_tokens_original"] == p["state_tokens_kept"], "DEV admission mismatch")
|
| 50 |
+
point = {"step": step, "metrics": metrics.summarize(dev, predictions)}
|
| 51 |
+
state.write_json(out / f"evaluation-{step:06d}.json", point)
|
| 52 |
+
with (out / f"predictions-{step:06d}.jsonl").open("x", encoding="utf-8") as stream:
|
| 53 |
+
for p in predictions:
|
| 54 |
+
stream.write(json.dumps(p, ensure_ascii=False, allow_nan=False) + "\n")
|
| 55 |
+
api.configure_training(native, max_input_tokens=1024)
|
| 56 |
+
return point
|
| 57 |
+
|
| 58 |
+
|
| 59 |
+
def update(api, native, optimizer, rows, admission, config, step, total, torch):
|
| 60 |
+
api.set_training_mode(native, True); optimizer.zero_grad(set_to_none=True)
|
| 61 |
+
scale = state.learning_rate_scale(step, total, config["warmup_steps"])
|
| 62 |
+
for group in optimizer.param_groups:
|
| 63 |
+
base = config["encoder_lr"] if group["name"].endswith("encoder") else config["head_lr"]
|
| 64 |
+
group["lr"] = state.learning_rate(step, total, config["warmup_steps"], base, config["lr_min"])
|
| 65 |
+
sums = [0., 0., 0.]; tokens = padded = 0
|
| 66 |
+
for start in range(0, len(rows), config["micro_batch_size"]):
|
| 67 |
+
micro = rows[start:start + config["micro_batch_size"]]
|
| 68 |
+
batch, encoded = native.collator([data.model_row(r) for r in micro], labeled=True, device="cuda:0")
|
| 69 |
+
data.need(all(data.digest(e) == admission[r["id"]]["encoded_sha256"] for r, e in zip(micro, encoded)),
|
| 70 |
+
"Actual training tokens/labels changed after complete admission")
|
| 71 |
+
tokens += sum(e["input_tokens"] for e in encoded); padded += len(micro) * batch["input_ids"].shape[1]
|
| 72 |
+
with torch.autocast("cuda", dtype=torch.bfloat16):
|
| 73 |
+
logits = api.forward_for_training(native, batch)
|
| 74 |
+
losses = api.loss_for_training(native, logits, batch, score_rps_weight=config["score_rps_weight"])
|
| 75 |
+
(losses[0].sum() / len(rows)).backward()
|
| 76 |
+
for i, loss in enumerate(losses):
|
| 77 |
+
sums[i] += float(loss.detach().sum())
|
| 78 |
+
del logits, losses, batch
|
| 79 |
+
check_memory(torch, config)
|
| 80 |
+
present = {r["question"]["type"].lower() for r in rows}
|
| 81 |
+
proof = api.gradient_report(native, present_types=present) if step == 1 else None
|
| 82 |
+
# AdamW must never decay a path absent from the logical batch.
|
| 83 |
+
for group in optimizer.param_groups:
|
| 84 |
+
for p in group["params"]:
|
| 85 |
+
if group["name"].split(".")[0] not in present:
|
| 86 |
+
data.need(p.grad is None, "Absent type has stale gradient")
|
| 87 |
+
elif p.grad is not None:
|
| 88 |
+
data.need(torch.isfinite(p.grad).all().item(), "Nonfinite gradient")
|
| 89 |
+
active = [p for g in optimizer.param_groups for p in g["params"]]
|
| 90 |
+
norm = float(torch.nn.utils.clip_grad_norm_(active, config["clip_norm"], error_if_nonfinite=True))
|
| 91 |
+
optimizer.step(); optimizer.zero_grad(set_to_none=True)
|
| 92 |
+
check_memory(torch, config)
|
| 93 |
+
return {"step": step, "record_ids": [r["id"] for r in rows], "logical_rows": len(rows),
|
| 94 |
+
"denominator": len(rows), "micro_batches": (len(rows) + config["micro_batch_size"] - 1) // config["micro_batch_size"],
|
| 95 |
+
"mean_loss": sums[0] / len(rows), "mean_ce": sums[1] / len(rows), "mean_rps_all_types_diagnostic": sums[2] / len(rows),
|
| 96 |
+
"effective_tokens": tokens, "padded_tokens": padded, "gradient_norm_before_clip": norm,
|
| 97 |
+
"clipped": norm > config["clip_norm"], "lr_scale": scale,
|
| 98 |
+
"learning_rates": {g["name"]: g["lr"] for g in optimizer.param_groups}, "first_step_gradient_proof": proof}
|
| 99 |
+
|
| 100 |
+
|
| 101 |
+
def execute(args, config):
|
| 102 |
+
import decision_runtime as api
|
| 103 |
+
train, dev = data.load_splits(args.train, args.dev, config["selection"])
|
| 104 |
+
schedule, default_points = data.make_schedule(train, config["epochs"], config["logical_batch_size"], config["seed"], config["max_steps"])
|
| 105 |
+
points = default_points if config["eval_steps"] is None else config["eval_steps"]
|
| 106 |
+
data.need(points == sorted(set(points)) and points[0] == 0 and points[-1] == len(schedule)
|
| 107 |
+
and all(0 <= s <= len(schedule) for s in points), "Evaluation steps must be ordered, unique, and include0/final")
|
| 108 |
+
config = {**config, "eval_steps": points, "total_steps": len(schedule)}
|
| 109 |
+
data.need(args.stop_after_step is None or 1 <= args.stop_after_step < len(schedule),
|
| 110 |
+
"A scheduling pause must be an original update before final; it does not shorten training")
|
| 111 |
+
config["warmup_steps"] = (int(len(schedule) * config["warmup_ratio"]) if config["warmup_steps"] is None else config["warmup_steps"])
|
| 112 |
+
data.need(0 <= config["warmup_steps"] < len(schedule), "Warmup must be shorter than the original full schedule")
|
| 113 |
+
train_sha, dev_sha = data.file_sha(args.train), data.file_sha(args.dev)
|
| 114 |
+
torch, environment = setup(config)
|
| 115 |
+
identity = {"config": config, "sources": source_identity(), "native_manifest_sha256": args.manifest_sha256,
|
| 116 |
+
"train_sha256": train_sha, "dev_sha256": dev_sha, "schedule_sha256": data.digest(schedule), "environment": environment}
|
| 117 |
+
out = Path(args.output).resolve()
|
| 118 |
+
data.need(not (out / "COMPLETE.json").exists(), "Completed runs are immutable")
|
| 119 |
+
if args.resume:
|
| 120 |
+
data.need(out.is_dir() and state.read_json(out / "RUN.json")["identity"] == identity,
|
| 121 |
+
"Resume must use the original output/config/data/source/environment")
|
| 122 |
+
data.need(Path(args.resume).resolve().is_relative_to(out / "attempts"), "Resume checkpoint must belong to this run")
|
| 123 |
+
else:
|
| 124 |
+
data.need(not out.exists(), "Fresh output required; use explicit --resume for an interrupted run")
|
| 125 |
+
out.mkdir(parents=True); (out / "attempts").mkdir()
|
| 126 |
+
state.write_json(out / "RUN.json", {"identity": identity, "train_path": str(Path(args.train).resolve()),
|
| 127 |
+
"dev_path": str(Path(args.dev).resolve()), "native_path": str(Path(args.native).resolve()),
|
| 128 |
+
"model_validation": "CLI integration not yet externally validated"})
|
| 129 |
+
state.write_json(out / "SCHEDULE.json", {"train_ids": [r["id"] for r in train], "row_indices": schedule})
|
| 130 |
+
import fcntl
|
| 131 |
+
with (out / "LOCK").open("a") as lock:
|
| 132 |
+
fcntl.flock(lock, fcntl.LOCK_EX | fcntl.LOCK_NB)
|
| 133 |
+
attempt = out / "attempts" / f"{len(list((out / 'attempts').iterdir())) + 1:04d}"
|
| 134 |
+
attempt.mkdir(); started = time.monotonic()
|
| 135 |
+
try:
|
| 136 |
+
native = api.load_native(args.native, expected_manifest_sha256=args.manifest_sha256)
|
| 137 |
+
# Same native packing; the user profile lowers only the admission cap.
|
| 138 |
+
native.collator = type(native.collator)(native.collator.tokenizer, max_length=1024, state_truncation="error")
|
| 139 |
+
admitted_train, admitted_dev = data.admit(native.collator, train), data.admit(native.collator, dev)
|
| 140 |
+
admission = {"train": admitted_train, "dev": admitted_dev, "truncated": 0, "dropped": 0,
|
| 141 |
+
"full_input_limit": 1024, "identity_sha256": data.digest(identity)}
|
| 142 |
+
state.write_json(attempt / "ADMISSION.json", admission)
|
| 143 |
+
api.configure_training(native, max_input_tokens=1024)
|
| 144 |
+
frozen = api.frozen_snapshot(native)
|
| 145 |
+
optimizer = torch.optim.AdamW(api.optimizer_groups(native, encoder_lr=config["encoder_lr"], head_lr=config["head_lr"]),
|
| 146 |
+
weight_decay=config["weight_decay"], fused=False, foreach=False)
|
| 147 |
+
layout = state.optimizer_layout(native.model, optimizer)
|
| 148 |
+
parameter_ids = [id(p) for g in optimizer.param_groups for p in g["params"]]
|
| 149 |
+
curve, best, step = [], None, 0
|
| 150 |
+
if args.resume:
|
| 151 |
+
meta, rng = state.load_checkpoint(args.resume, args.resume_sha256, native, optimizer, identity, torch)
|
| 152 |
+
api.assert_frozen(native, frozen, content=True, versions=False)
|
| 153 |
+
data.need(meta["frozen_hashes"] == {n: x["sha256"] for n, x in frozen.items()}, "Checkpoint frozen content differs from parent")
|
| 154 |
+
frozen = api.frozen_snapshot(native)
|
| 155 |
+
curve, best, step = meta["curve"], meta["best"], meta["step"]
|
| 156 |
+
data.need(0 <= step <= len(schedule) and all(p["step"] <= step for p in curve), "Resume position invalid")
|
| 157 |
+
data.need(args.stop_after_step is None or args.stop_after_step > step, "Pause must follow the resumed checkpoint")
|
| 158 |
+
if best is not None and best.get("checkpoint_manifest_sha256") is None:
|
| 159 |
+
data.need(Path(best["checkpoint"]).resolve() == Path(args.resume).resolve()
|
| 160 |
+
and best["step"] == step, "Missing previous best checkpoint identity")
|
| 161 |
+
best = {**best, "checkpoint_manifest_sha256": args.resume_sha256}
|
| 162 |
+
state.restore_rng(torch, rng) # Last potentially RNG-sensitive setup operation.
|
| 163 |
+
def checkpoint(current):
|
| 164 |
+
nonlocal best
|
| 165 |
+
directory = attempt / f"checkpoint-{current:06d}"
|
| 166 |
+
if best is not None and best.get("checkpoint") is None:
|
| 167 |
+
best = {**best, "checkpoint": str(directory.resolve())}
|
| 168 |
+
api.assert_frozen(native, frozen, content=True)
|
| 169 |
+
receipt = state.save_checkpoint(directory, native, optimizer,
|
| 170 |
+
{"identity": identity, "step": current, "curve": curve, "best": best,
|
| 171 |
+
"frozen_hashes": {n: x["sha256"] for n, x in frozen.items()}}, torch)
|
| 172 |
+
if best is not None and best["checkpoint"] == str(directory.resolve()):
|
| 173 |
+
best = {**best, "checkpoint_manifest_sha256": receipt["manifest_sha256"]}
|
| 174 |
+
state.write_json(out / "LATEST.json", receipt)
|
| 175 |
+
return receipt
|
| 176 |
+
def evaluate(current):
|
| 177 |
+
nonlocal best
|
| 178 |
+
api.assert_frozen(native, frozen, content=True)
|
| 179 |
+
opt_states = {id(p): id(s) for p, s in optimizer.state.items()}
|
| 180 |
+
point = evaluation(api, native, dev, admitted_dev, attempt, current, torch)
|
| 181 |
+
data.need(parameter_ids == [id(p) for g in optimizer.param_groups for p in g["params"]]
|
| 182 |
+
and layout == state.optimizer_layout(native.model, optimizer)
|
| 183 |
+
and opt_states == {id(p): id(s) for p, s in optimizer.state.items()}, "Evaluation broke optimizer identity")
|
| 184 |
+
curve.append(point)
|
| 185 |
+
if metrics.better(point, best, config["selection"], config["selection_tolerance"]):
|
| 186 |
+
best = {**point, "checkpoint": None}
|
| 187 |
+
checkpoint(current)
|
| 188 |
+
if not args.resume:
|
| 189 |
+
evaluate(0)
|
| 190 |
+
with (attempt / "TRAIN_LOG.jsonl").open("x", encoding="utf-8") as log:
|
| 191 |
+
for current in range(step + 1, len(schedule) + 1):
|
| 192 |
+
report = update(api, native, optimizer, [train[i] for i in schedule[current - 1]], admitted_train, config, current, len(schedule), torch)
|
| 193 |
+
api.assert_frozen(native, frozen)
|
| 194 |
+
log.write(json.dumps(report, allow_nan=False) + "\n"); log.flush()
|
| 195 |
+
if current in points:
|
| 196 |
+
evaluate(current)
|
| 197 |
+
elif config["save_every"] and current % config["save_every"] == 0:
|
| 198 |
+
checkpoint(current)
|
| 199 |
+
if current == args.stop_after_step:
|
| 200 |
+
if current not in points and not (config["save_every"] and current % config["save_every"] == 0):
|
| 201 |
+
checkpoint(current)
|
| 202 |
+
paused = {"status": "PAUSED_DECISION_FINETUNE", "identity": identity, "step": current,
|
| 203 |
+
"checkpoint": state.read_json(out / "LATEST.json"), "total_steps": len(schedule),
|
| 204 |
+
"scheduling_pause_not_selection": True, "native_exported": False}
|
| 205 |
+
state.write_json(attempt / "PAUSED.json", paused)
|
| 206 |
+
return paused
|
| 207 |
+
data.need([p["step"] for p in curve] == points and best is not None, "Missing evaluation/selected checkpoint")
|
| 208 |
+
# A resume after final checkpoint can finish export without replaying training.
|
| 209 |
+
del optimizer; gc.collect(); torch.cuda.empty_cache()
|
| 210 |
+
from safetensors.torch import load_file
|
| 211 |
+
selected_dir = Path(best["checkpoint"])
|
| 212 |
+
selected_sha = best["checkpoint_manifest_sha256"]
|
| 213 |
+
_, selected_meta = state.verify_checkpoint(selected_dir, selected_sha)
|
| 214 |
+
data.need(selected_meta["identity"] == identity and selected_meta["step"] == best["step"], "Selected checkpoint identity")
|
| 215 |
+
native.model.load_state_dict(load_file(str(selected_dir / "model.safetensors"), device="cpu"), strict=True)
|
| 216 |
+
api.assert_frozen(native, frozen, content=True, versions=False)
|
| 217 |
+
api.restore_native_policy_for_export(native)
|
| 218 |
+
export_path = attempt / "selected-native"
|
| 219 |
+
api.export_native(native, export_path, provenance={"cli": "decision_finetune", "identity": identity,
|
| 220 |
+
"selected_step": best["step"], "selection": best["metrics"], "total_steps": len(schedule),
|
| 221 |
+
"selected0_no_adaptation": best["step"] == 0, "checkpoint_manifest_sha256": selected_sha,
|
| 222 |
+
"release_or_quality_qualification": False})
|
| 223 |
+
data.need(data.file_sha(args.train) == train_sha and data.file_sha(args.dev) == dev_sha
|
| 224 |
+
and source_identity() == identity["sources"], "Source/data changed during run")
|
| 225 |
+
check_memory(torch, config)
|
| 226 |
+
result = {"status": "COMPLETE_DECISION_FINETUNE", "identity": identity, "curve": curve,
|
| 227 |
+
"selected": best, "selected0_no_adaptation": best["step"] == 0,
|
| 228 |
+
"native": str(export_path), "native_manifest_sha256": data.file_sha(export_path / "MANIFEST.json"),
|
| 229 |
+
"attempt_elapsed_seconds": time.monotonic() - started,
|
| 230 |
+
"peak_reserved_bytes": torch.cuda.max_memory_reserved(), "resumed": bool(args.resume),
|
| 231 |
+
"independent_fresh_reload_performed": False, "release_qualified": False}
|
| 232 |
+
state.write_json(out / "COMPLETE.json", result)
|
| 233 |
+
return result
|
| 234 |
+
except BaseException as error:
|
| 235 |
+
state.write_json(attempt / "FAILURE.json", {"exception_type": type(error).__name__, "message": str(error),
|
| 236 |
+
"resume_requires_explicit_checkpoint": True})
|
| 237 |
+
raise
|
decision_finetune/state.py
ADDED
|
@@ -0,0 +1,110 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Atomic update-boundary checkpoints with named optimizer mapping and RNG state."""
|
| 2 |
+
import json
|
| 3 |
+
import os
|
| 4 |
+
from pathlib import Path
|
| 5 |
+
import random
|
| 6 |
+
import tempfile
|
| 7 |
+
from .data import need, file_sha
|
| 8 |
+
|
| 9 |
+
|
| 10 |
+
def write_json(path, value):
|
| 11 |
+
path = Path(path)
|
| 12 |
+
fd, temporary = tempfile.mkstemp(prefix="." + path.name + ".", suffix=".tmp", dir=path.parent)
|
| 13 |
+
try:
|
| 14 |
+
with os.fdopen(fd, "w", encoding="utf-8") as stream:
|
| 15 |
+
json.dump(value, stream, ensure_ascii=False, sort_keys=True, indent=2, allow_nan=False)
|
| 16 |
+
stream.write("\n"); stream.flush(); os.fsync(stream.fileno())
|
| 17 |
+
os.replace(temporary, path)
|
| 18 |
+
finally:
|
| 19 |
+
if os.path.exists(temporary):
|
| 20 |
+
os.unlink(temporary)
|
| 21 |
+
|
| 22 |
+
|
| 23 |
+
def read_json(path):
|
| 24 |
+
return json.loads(Path(path).read_text(encoding="utf-8"))
|
| 25 |
+
|
| 26 |
+
|
| 27 |
+
def optimizer_layout(model, optimizer):
|
| 28 |
+
names = {id(p): name for name, p in model.named_parameters()}
|
| 29 |
+
layout = [{"name": g["name"], "parameters": [names[id(p)] for p in g["params"]]}
|
| 30 |
+
for g in optimizer.param_groups]
|
| 31 |
+
flattened = [n for group in layout for n in group["parameters"]]
|
| 32 |
+
need(len(set(flattened)) == len(flattened), "Optimizer parameter alias")
|
| 33 |
+
return layout
|
| 34 |
+
|
| 35 |
+
|
| 36 |
+
def rng_state(torch):
|
| 37 |
+
import numpy as np
|
| 38 |
+
n = np.random.get_state()
|
| 39 |
+
return {"python": random.getstate(), "numpy": [n[0], n[1].tolist(), n[2], n[3], n[4]],
|
| 40 |
+
"torch_cpu": torch.get_rng_state(), "torch_cuda": torch.cuda.get_rng_state_all()}
|
| 41 |
+
|
| 42 |
+
|
| 43 |
+
def restore_rng(torch, saved):
|
| 44 |
+
import numpy as np
|
| 45 |
+
need(len(saved["torch_cuda"]) == torch.cuda.device_count(), "CUDA RNG device count changed")
|
| 46 |
+
random.setstate(saved["python"])
|
| 47 |
+
n = saved["numpy"]; np.random.set_state((n[0], np.asarray(n[1], dtype=np.uint32), n[2], n[3], n[4]))
|
| 48 |
+
torch.set_rng_state(saved["torch_cpu"]); torch.cuda.set_rng_state_all(saved["torch_cuda"])
|
| 49 |
+
|
| 50 |
+
|
| 51 |
+
def save_checkpoint(path, native, optimizer, metadata, torch):
|
| 52 |
+
from safetensors.torch import save_file
|
| 53 |
+
path = Path(path); temporary = path.with_name(path.name + ".tmp")
|
| 54 |
+
need(not path.exists() and not temporary.exists(), "Checkpoint destinations are immutable")
|
| 55 |
+
temporary.mkdir()
|
| 56 |
+
# CPU copies are serialization only; no CPU model or forward is constructed.
|
| 57 |
+
save_file({n: t.detach().cpu().contiguous() for n, t in native.model.state_dict().items()}, str(temporary / "model.safetensors"))
|
| 58 |
+
torch.save({"optimizer": optimizer.state_dict(), "rng": rng_state(torch)}, temporary / "state.pt")
|
| 59 |
+
write_json(temporary / "metadata.json", {**metadata, "optimizer_layout": optimizer_layout(native.model, optimizer)})
|
| 60 |
+
files = {p.name: {"sha256": file_sha(p), "bytes": p.stat().st_size} for p in sorted(temporary.iterdir())}
|
| 61 |
+
write_json(temporary / "MANIFEST.json", {"schema": "decision.finetune.checkpoint.v1", "files": files})
|
| 62 |
+
os.replace(temporary, path)
|
| 63 |
+
return {"path": str(path.resolve()), "manifest_sha256": file_sha(path / "MANIFEST.json")}
|
| 64 |
+
|
| 65 |
+
|
| 66 |
+
def verify_checkpoint(path, expected_sha):
|
| 67 |
+
path = Path(path).resolve(strict=True)
|
| 68 |
+
need(file_sha(path / "MANIFEST.json") == expected_sha, "Explicit checkpoint manifest SHA mismatch")
|
| 69 |
+
manifest = read_json(path / "MANIFEST.json")
|
| 70 |
+
need(manifest["schema"] == "decision.finetune.checkpoint.v1"
|
| 71 |
+
and set(manifest["files"]) == {"model.safetensors", "state.pt", "metadata.json"}, "Checkpoint roster mismatch")
|
| 72 |
+
need({p.name for p in path.iterdir()} == set(manifest["files"]) | {"MANIFEST.json"}, "Unexpected checkpoint file")
|
| 73 |
+
for name, ref in manifest["files"].items():
|
| 74 |
+
p = path / name
|
| 75 |
+
need(not p.is_symlink() and p.is_file() and p.stat().st_size == ref["bytes"] and file_sha(p) == ref["sha256"], "Checkpoint file changed")
|
| 76 |
+
return path, read_json(path / "metadata.json")
|
| 77 |
+
|
| 78 |
+
|
| 79 |
+
def load_checkpoint(path, expected_sha, native, optimizer, identity, torch):
|
| 80 |
+
from safetensors.torch import load_file
|
| 81 |
+
path, meta = verify_checkpoint(path, expected_sha)
|
| 82 |
+
need(meta["identity"] == identity, "Resume source/data/native/config/schedule/environment identity changed")
|
| 83 |
+
need(meta["optimizer_layout"] == optimizer_layout(native.model, optimizer), "Named optimizer group/order mismatch")
|
| 84 |
+
parameter_ids = [id(p) for p in native.model.parameters()]
|
| 85 |
+
native.model.load_state_dict(load_file(str(path / "model.safetensors"), device="cpu"), strict=True)
|
| 86 |
+
need([id(p) for p in native.model.parameters()] == parameter_ids, "Loading replaced parameters")
|
| 87 |
+
# Only trust locally produced, explicitly hash-verified checkpoints. No arbitrary pickle globals.
|
| 88 |
+
state = torch.load(path / "state.pt", map_location="cpu", weights_only=True)
|
| 89 |
+
optimizer.load_state_dict(state["optimizer"])
|
| 90 |
+
need(meta["optimizer_layout"] == optimizer_layout(native.model, optimizer), "Restored optimizer mapping drift")
|
| 91 |
+
for p, item in optimizer.state.items():
|
| 92 |
+
need(all(item[k].shape == p.shape and torch.isfinite(item[k]).all().item() for k in ("exp_avg", "exp_avg_sq")), "Invalid AdamW moments")
|
| 93 |
+
need(0 < float(item["step"]) <= meta["step"], "Invalid per-parameter AdamW step")
|
| 94 |
+
return meta, state["rng"]
|
| 95 |
+
|
| 96 |
+
|
| 97 |
+
def learning_rate_scale(step, total, warmup):
|
| 98 |
+
import math
|
| 99 |
+
need(1 <= step <= total and 0 <= warmup < total, "Invalid original LR horizon")
|
| 100 |
+
if warmup and step <= warmup:
|
| 101 |
+
return step / warmup
|
| 102 |
+
progress = ((step - warmup) / (total - warmup) if warmup
|
| 103 |
+
else (step - 1) / (total - 1) if total > 1 else 0.)
|
| 104 |
+
return .5 * (1 + math.cos(math.pi * progress))
|
| 105 |
+
|
| 106 |
+
|
| 107 |
+
def learning_rate(step, total, warmup, base, minimum):
|
| 108 |
+
need(0 <= minimum <= base, "LR floor must fit every optimizer group")
|
| 109 |
+
scale = learning_rate_scale(step, total, warmup)
|
| 110 |
+
return base * scale if warmup and step <= warmup else minimum + (base - minimum) * scale
|
decision_inference/__init__.py
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
from .profile import Complete1KCollator, MAX_INPUT_TOKENS, predict_1k
|
| 2 |
+
|
| 3 |
+
__all__ = ["Complete1KCollator", "MAX_INPUT_TOKENS", "predict_1k"]
|
decision_inference/profile.py
ADDED
|
@@ -0,0 +1,55 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Complete-input 1K product profile around an unchanged native runtime."""
|
| 2 |
+
from dataclasses import replace
|
| 3 |
+
|
| 4 |
+
MAX_INPUT_TOKENS = 1024
|
| 5 |
+
|
| 6 |
+
|
| 7 |
+
class Complete1KCollator:
|
| 8 |
+
"""Use the native collator's actual length error, never truncate fields.
|
| 9 |
+
|
| 10 |
+
Constructible with a tokenizer before any model is loaded. A whole request
|
| 11 |
+
is admitted before predict, and every physical batch before tensor assembly.
|
| 12 |
+
"""
|
| 13 |
+
def __init__(self, native_collator):
|
| 14 |
+
self.base = type(native_collator)(native_collator.tokenizer,
|
| 15 |
+
max_length=MAX_INPUT_TOKENS,
|
| 16 |
+
state_truncation="error")
|
| 17 |
+
self.tokenizer = self.base.tokenizer
|
| 18 |
+
self.marker, self.pad = self.base.marker, self.base.pad
|
| 19 |
+
self.tensor_batches = 0
|
| 20 |
+
|
| 21 |
+
def tokens(self, text):
|
| 22 |
+
return self.base.tokens(text)
|
| 23 |
+
|
| 24 |
+
def encode(self, row, labeled=False):
|
| 25 |
+
encoded = self.base.encode(row, labeled=labeled)
|
| 26 |
+
if (encoded["input_tokens"] > MAX_INPUT_TOKENS
|
| 27 |
+
or encoded["state_tokens_original"] != encoded["state_tokens_kept"]):
|
| 28 |
+
raise ValueError("Native collator violated the complete-input 1K profile")
|
| 29 |
+
return encoded
|
| 30 |
+
|
| 31 |
+
def admit(self, records):
|
| 32 |
+
return [self.encode(row, labeled=False) for row in records]
|
| 33 |
+
|
| 34 |
+
def __call__(self, records, labeled=False, device="cpu"):
|
| 35 |
+
records = list(records)
|
| 36 |
+
# All encodes finish before delegating any tensor allocation.
|
| 37 |
+
for row in records:
|
| 38 |
+
self.encode(row, labeled=labeled)
|
| 39 |
+
self.tensor_batches += 1
|
| 40 |
+
return self.base(records, labeled=labeled, device=device)
|
| 41 |
+
|
| 42 |
+
|
| 43 |
+
def predict_1k(native, records, *, batch_size=8):
|
| 44 |
+
"""FP32 native inference, B1..8, complete state/question/all candidates ≤1K.
|
| 45 |
+
|
| 46 |
+
The native object/config/runtime/weights are not mutated. No claim of
|
| 47 |
+
candidate permutation invariance or task quality is made by this wrapper.
|
| 48 |
+
"""
|
| 49 |
+
if type(batch_size) is not int or not 1 <= batch_size <= 8:
|
| 50 |
+
raise ValueError("The product profile permits integer batch sizes 1..8")
|
| 51 |
+
records = list(records)
|
| 52 |
+
guard = Complete1KCollator(native.collator)
|
| 53 |
+
guard.admit(records) # Reject any oversized request before the first forward.
|
| 54 |
+
from decision_runtime import predict
|
| 55 |
+
return predict(replace(native, collator=guard), records, batch_size=batch_size)
|
decision_runtime/__init__.py
ADDED
|
@@ -0,0 +1,11 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Source-only portable training adapter; real AMD validation is still pending."""
|
| 2 |
+
from .native import load_native, export_native, predict
|
| 3 |
+
from .training import (configure_training, set_training_mode, forward_for_training,
|
| 4 |
+
loss_for_training, optimizer_groups, inventory,
|
| 5 |
+
frozen_snapshot, assert_frozen, gradient_report,
|
| 6 |
+
restore_native_policy_for_export)
|
| 7 |
+
|
| 8 |
+
__all__ = ["load_native", "export_native", "predict", "configure_training",
|
| 9 |
+
"set_training_mode", "forward_for_training", "loss_for_training",
|
| 10 |
+
"optimizer_groups", "inventory", "frozen_snapshot", "assert_frozen",
|
| 11 |
+
"gradient_report", "restore_native_policy_for_export"]
|
decision_runtime/_compat.py
ADDED
|
@@ -0,0 +1,20 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Supported self-contained runtime revision; weights may differ. No path bindings."""
|
| 2 |
+
RUNTIME_SHA256 = {'__init__.py': '1afb9dbcfc379f28049486fe6acb7acfdaa8d16b6773d6084ca4b82ead26f010',
|
| 3 |
+
'artifacts.py': 'c98adaf6d782e9fc592cd78b1307d63faffa9ba622b9d508c63337c29156e4d3',
|
| 4 |
+
'contract.py': '51a24800792bb3e5bf2a11f50f7bc384770641f4f44ed46277dc01e891bf4726',
|
| 5 |
+
'infer.py': '9d14841935c836a0765c705d5a24e8fa97437ae35fff65bc6e690b397f0d0315',
|
| 6 |
+
'model.py': '8fe91e2a77f372d32117e62281ccb58a054c144228b73b4987f1e1a3fca9ee5b',
|
| 7 |
+
'packing.py': 'f1dab7f032f4aaab27118606397ca67d71b1f4a2ba49e65bebcfd83a64b27819',
|
| 8 |
+
'policy/__init__.py': '0cb0bad7d3d0f258ecf95f52297ee8733a75f8504cabb86b9aea4b8256885114',
|
| 9 |
+
'policy/artifacts.py': '5838d2ea747d912789f3fc813a212af919cbc24ee185073576d9fbe32ed31cf2',
|
| 10 |
+
'policy/contract.py': '0b8eeeeebe9e367564a3c57f48364c5e94ae060f759e220b1326caf152276b67',
|
| 11 |
+
'policy/infer.py': '672bfae798060d51fcccac03143ac881fe7512893ffdacdb36b0618d4b160896',
|
| 12 |
+
'policy/model.py': 'eaeebac8fd6bd96243a5c4b6225c86ee3359c067784f1595979ee603cba9acca',
|
| 13 |
+
'policy/packing.py': 'f1dab7f032f4aaab27118606397ca67d71b1f4a2ba49e65bebcfd83a64b27819',
|
| 14 |
+
'policy/reference/__init__.py': 'c8d6fd86207752407f94437544a97266b9529f88d2b341d35aafcd911c942b28',
|
| 15 |
+
'policy/reference/artifacts.py': '3f59428b7a05608ac01c73c7db89c38fcc3e2c5030219df8d053af92b32e6159',
|
| 16 |
+
'policy/reference/infer.py': '672bfae798060d51fcccac03143ac881fe7512893ffdacdb36b0618d4b160896',
|
| 17 |
+
'policy/reference/model.py': '733ea4a48ea03089dac8c3e6a175920704fac50f93313b0214cec4052f25bd26',
|
| 18 |
+
'policy/reference/modernbert_sdpa_layout.py': '0fb3a22db93ad76e30dfbfb3011de442149d97c565e139a3a55738287a1fbbc8',
|
| 19 |
+
'policy/reference/packing.py': 'f1dab7f032f4aaab27118606397ca67d71b1f4a2ba49e65bebcfd83a64b27819',
|
| 20 |
+
'training_policy.py': '6f7fad91c5089b304a1d637b594027a9379a63600792766ce0abca6b24bd2ec5'}
|
decision_runtime/native.py
ADDED
|
@@ -0,0 +1,152 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Load the export's own verified runtime; never import an experiment package."""
|
| 2 |
+
from dataclasses import dataclass, field
|
| 3 |
+
from pathlib import Path, PurePosixPath
|
| 4 |
+
import copy
|
| 5 |
+
import hashlib
|
| 6 |
+
import importlib
|
| 7 |
+
import importlib.util
|
| 8 |
+
import json
|
| 9 |
+
import re
|
| 10 |
+
import sys
|
| 11 |
+
import uuid
|
| 12 |
+
|
| 13 |
+
from ._compat import RUNTIME_SHA256
|
| 14 |
+
|
| 15 |
+
|
| 16 |
+
def sha256(path):
|
| 17 |
+
digest = hashlib.sha256()
|
| 18 |
+
with Path(path).open("rb") as stream:
|
| 19 |
+
for chunk in iter(lambda: stream.read(1 << 20), b""):
|
| 20 |
+
digest.update(chunk)
|
| 21 |
+
return digest.hexdigest()
|
| 22 |
+
|
| 23 |
+
|
| 24 |
+
def verify_files(directory, expected_manifest_sha256):
|
| 25 |
+
"""Stdlib pre-import verification, including every weight and runtime file."""
|
| 26 |
+
root = Path(directory).resolve(strict=True)
|
| 27 |
+
if not re.fullmatch(r"[0-9a-f]{64}", expected_manifest_sha256 or ""):
|
| 28 |
+
raise ValueError("An explicit trusted MANIFEST SHA256 is required")
|
| 29 |
+
if sha256(root / "MANIFEST.json") != expected_manifest_sha256:
|
| 30 |
+
raise ValueError("Native manifest identity mismatch")
|
| 31 |
+
manifest = json.loads((root / "MANIFEST.json").read_text())
|
| 32 |
+
files = manifest.get("files")
|
| 33 |
+
if manifest.get("schema") != "decision.files.v1" or not isinstance(files, dict):
|
| 34 |
+
raise ValueError("Unsupported native manifest")
|
| 35 |
+
for name, ref in files.items():
|
| 36 |
+
if not isinstance(name, str) or not isinstance(ref, dict):
|
| 37 |
+
raise ValueError("Invalid manifest entry")
|
| 38 |
+
rel = PurePosixPath(name)
|
| 39 |
+
if (rel.is_absolute() or ".." in rel.parts
|
| 40 |
+
or rel.as_posix() != name or "\\" in name or not rel.parts):
|
| 41 |
+
raise ValueError("Unsafe manifest path")
|
| 42 |
+
path = root / name
|
| 43 |
+
if (not path.is_file() or path.is_symlink()
|
| 44 |
+
or set(ref) != {"bytes", "sha256"}
|
| 45 |
+
or path.stat().st_size != ref["bytes"] or sha256(path) != ref["sha256"]):
|
| 46 |
+
raise ValueError("Native file mismatch: " + name)
|
| 47 |
+
actual = set()
|
| 48 |
+
for path in root.rglob("*"):
|
| 49 |
+
if path.is_symlink():
|
| 50 |
+
raise ValueError("Materialized native required; symlinks are not supported")
|
| 51 |
+
rel = path.relative_to(root)
|
| 52 |
+
if path.is_file() and rel.as_posix() != "MANIFEST.json":
|
| 53 |
+
if "__pycache__" in rel.parts and path.suffix == ".pyc":
|
| 54 |
+
continue
|
| 55 |
+
actual.add(rel.as_posix())
|
| 56 |
+
if actual != set(files):
|
| 57 |
+
raise ValueError("Native file roster mismatch")
|
| 58 |
+
runtime = {name: ref["sha256"] for name, ref in files.items() if name.endswith(".py")}
|
| 59 |
+
if runtime != RUNTIME_SHA256:
|
| 60 |
+
raise ValueError("Unsupported runtime revision; architecture name alone is insufficient")
|
| 61 |
+
return root, manifest
|
| 62 |
+
|
| 63 |
+
|
| 64 |
+
@dataclass
|
| 65 |
+
class Native:
|
| 66 |
+
directory: Path
|
| 67 |
+
manifest_sha256: str
|
| 68 |
+
model: object
|
| 69 |
+
collator: object
|
| 70 |
+
config: dict
|
| 71 |
+
model_api: object
|
| 72 |
+
contract: object
|
| 73 |
+
artifacts: object
|
| 74 |
+
training_state: dict | None = None
|
| 75 |
+
last_training_provenance: dict | None = None
|
| 76 |
+
package_name: str = field(default="", repr=False)
|
| 77 |
+
|
| 78 |
+
|
| 79 |
+
def _amd_device(device):
|
| 80 |
+
import torch
|
| 81 |
+
selected = torch.device(device)
|
| 82 |
+
if selected.type != "cuda" or torch.version.hip is None or not torch.cuda.is_available():
|
| 83 |
+
raise ValueError("This runtime requires a real ROCm CUDA device; no CPU fallback")
|
| 84 |
+
if selected.index is None:
|
| 85 |
+
selected = torch.device("cuda", torch.cuda.current_device())
|
| 86 |
+
return selected
|
| 87 |
+
|
| 88 |
+
|
| 89 |
+
def load_native(directory, *, expected_manifest_sha256, device="cuda:0"):
|
| 90 |
+
"""Load any compatible weight export with the pinned public runtime revision.
|
| 91 |
+
|
| 92 |
+
Verification precedes executing bundled Python. This function loads a model;
|
| 93 |
+
importing decision_runtime or running its stdlib checks does not.
|
| 94 |
+
"""
|
| 95 |
+
root, manifest = verify_files(directory, expected_manifest_sha256)
|
| 96 |
+
selected = _amd_device(device)
|
| 97 |
+
namespace = "_decision_native_" + uuid.uuid4().hex
|
| 98 |
+
spec = importlib.util.spec_from_file_location(namespace, root / "__init__.py",
|
| 99 |
+
submodule_search_locations=[str(root)])
|
| 100 |
+
package = importlib.util.module_from_spec(spec)
|
| 101 |
+
sys.modules[namespace] = package
|
| 102 |
+
try:
|
| 103 |
+
spec.loader.exec_module(package)
|
| 104 |
+
artifacts = importlib.import_module(namespace + ".artifacts")
|
| 105 |
+
contract = importlib.import_module(namespace + ".contract")
|
| 106 |
+
api = importlib.import_module(namespace + ".model")
|
| 107 |
+
declared = contract.validate_config(json.loads((root / "decision_config.json").read_text()))
|
| 108 |
+
if (declared["arm"], declared["training_arm"]) != ("all22", "S22"):
|
| 109 |
+
raise ValueError("Only the complete three-path all22/S22 architecture is supported")
|
| 110 |
+
model, collator, cfg = artifacts.load_export(root, device=str(selected))
|
| 111 |
+
if (cfg["arm"], cfg["training_arm"]) != ("all22", "S22"):
|
| 112 |
+
raise ValueError("Only the complete three-path all22/S22 architecture is supported")
|
| 113 |
+
if type(model) is not api.DecisionModel or artifacts.verify_native(root) != (manifest, cfg):
|
| 114 |
+
raise ValueError("Loaded class or native identity mismatch")
|
| 115 |
+
return Native(root, expected_manifest_sha256, model, collator, cfg, api,
|
| 116 |
+
contract, artifacts, package_name=namespace)
|
| 117 |
+
except BaseException:
|
| 118 |
+
for name in tuple(sys.modules):
|
| 119 |
+
if name == namespace or name.startswith(namespace + "."):
|
| 120 |
+
del sys.modules[name]
|
| 121 |
+
raise
|
| 122 |
+
|
| 123 |
+
|
| 124 |
+
def _native_mode(native):
|
| 125 |
+
if native.training_state is not None:
|
| 126 |
+
raise ValueError("Restore native policy before native inference or export")
|
| 127 |
+
native.model.verify_inventory(check_values=False)
|
| 128 |
+
|
| 129 |
+
|
| 130 |
+
def predict(native, records, *, batch_size=8):
|
| 131 |
+
"""Unchanged bundled inference, FP32; no training graph is used here."""
|
| 132 |
+
_native_mode(native)
|
| 133 |
+
device = next(native.model.parameters()).device
|
| 134 |
+
_amd_device(device)
|
| 135 |
+
return native.model_api.predict(native.model, native.collator, records,
|
| 136 |
+
batch_size=batch_size, device=str(device), precision="fp32")
|
| 137 |
+
|
| 138 |
+
|
| 139 |
+
def export_native(native, directory, *, provenance):
|
| 140 |
+
"""Use the original strict exporter after explicit policy restoration."""
|
| 141 |
+
_native_mode(native)
|
| 142 |
+
if native.last_training_provenance is None or not isinstance(provenance, dict):
|
| 143 |
+
raise ValueError("Restored training provenance and an explicit user provenance dict required")
|
| 144 |
+
if Path(directory).exists():
|
| 145 |
+
raise ValueError("Export destination must be fresh")
|
| 146 |
+
details = {"parent_native_manifest_sha256": native.manifest_sha256,
|
| 147 |
+
"parent_provenance": copy.deepcopy(native.config.get("provenance", {})),
|
| 148 |
+
"training_adapter": copy.deepcopy(native.last_training_provenance),
|
| 149 |
+
"user": copy.deepcopy(provenance)}
|
| 150 |
+
json.dumps(details, allow_nan=False)
|
| 151 |
+
return native.artifacts.export_model(native.model, native.collator.tokenizer,
|
| 152 |
+
directory, native.config, details)
|
decision_runtime/training.py
ADDED
|
@@ -0,0 +1,310 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Explicit all-types training graph for the unchanged three-path native."""
|
| 2 |
+
import math
|
| 3 |
+
from pathlib import Path
|
| 4 |
+
from .native import sha256, _amd_device
|
| 5 |
+
|
| 6 |
+
KINDS = ("choice", "noul", "score")
|
| 7 |
+
FROZEN = ("encoder.embeddings.tok_embeddings.weight",
|
| 8 |
+
"encoder.embeddings.norm.weight", "type_embedding.weight")
|
| 9 |
+
COUNTS = {"tensors": 489, "parameters": 571909635, "active_tensors": 486,
|
| 10 |
+
"active_parameters": 375298563, "frozen_tensors": 3,
|
| 11 |
+
"frozen_parameters": 196611072}
|
| 12 |
+
|
| 13 |
+
|
| 14 |
+
def parameter_group(name):
|
| 15 |
+
if name in FROZEN:
|
| 16 |
+
return "frozen"
|
| 17 |
+
for kind, prefixes in {"choice": ("choice_blocks.", "choice_final_norm."),
|
| 18 |
+
"noul": ("encoder.layers.", "encoder.final_norm."),
|
| 19 |
+
"score": ("score_blocks.", "score_final_norm.")}.items():
|
| 20 |
+
if name.startswith(prefixes):
|
| 21 |
+
return kind + ".encoder"
|
| 22 |
+
for kind in KINDS:
|
| 23 |
+
for suffix, prefix in (("head", "heads."), ("scorer", "scorers.")):
|
| 24 |
+
if name.startswith(prefix + kind + "."):
|
| 25 |
+
return kind + "." + suffix
|
| 26 |
+
raise ValueError("Unsupported parameter name: " + name)
|
| 27 |
+
|
| 28 |
+
|
| 29 |
+
def _roots(model):
|
| 30 |
+
return {"choice": (model.choice_blocks, model.choice_final_norm, model.heads["choice"], model.scorers["choice"]),
|
| 31 |
+
"noul": (model.encoder.layers, model.encoder.final_norm, model.heads["noul"], model.scorers["noul"]),
|
| 32 |
+
"score": (model.score_blocks, model.score_final_norm, model.heads["score"], model.scorers["score"])}
|
| 33 |
+
|
| 34 |
+
|
| 35 |
+
def _identities(model):
|
| 36 |
+
return {n: (id(p), p.untyped_storage().data_ptr()) for n, p in model.named_parameters()}
|
| 37 |
+
|
| 38 |
+
|
| 39 |
+
def _api(native):
|
| 40 |
+
m, c, api = native.model, native.contract, native.model_api
|
| 41 |
+
if (type(m) is not api.DecisionModel or m.arm != "all22" or m.training_arm != "S22"
|
| 42 |
+
or m.trainability_mode != c.training_policy("S22")):
|
| 43 |
+
raise ValueError("Original all22/S22 native class and metadata required")
|
| 44 |
+
api.runtime_gate()
|
| 45 |
+
return api
|
| 46 |
+
|
| 47 |
+
|
| 48 |
+
def inventory(native):
|
| 49 |
+
import torch
|
| 50 |
+
_api(native)
|
| 51 |
+
m = native.model
|
| 52 |
+
shapes = native.contract.all_shapes(m.arm, m.training_arm)
|
| 53 |
+
raw = list(m.named_parameters(remove_duplicate=False))
|
| 54 |
+
names = {n for n, _ in raw}
|
| 55 |
+
if names != set(shapes) or set(m.state_dict()) != names or len(raw) != len(names):
|
| 56 |
+
raise ValueError("Exact native parameter/state roster required")
|
| 57 |
+
if len({id(p) for _, p in raw}) != len(raw) or len({p.untyped_storage().data_ptr() for _, p in raw}) != len(raw):
|
| 58 |
+
raise ValueError("Aliased parameters/storage are unsupported")
|
| 59 |
+
if any(tuple(p.shape) != tuple(shapes[n]) or p.dtype != torch.float32
|
| 60 |
+
or p.requires_grad != (parameter_group(n) != "frozen") for n, p in raw):
|
| 61 |
+
raise ValueError("Training shape, FP32 parameter dtype or policy drift")
|
| 62 |
+
active = [p for n, p in raw if parameter_group(n) != "frozen"]
|
| 63 |
+
counts = {"tensors": len(raw), "parameters": sum(p.numel() for _, p in raw),
|
| 64 |
+
"active_tensors": len(active), "active_parameters": sum(p.numel() for p in active),
|
| 65 |
+
"frozen_tensors": len(raw) - len(active),
|
| 66 |
+
"frozen_parameters": sum(p.numel() for n, p in raw if parameter_group(n) == "frozen")}
|
| 67 |
+
if counts != COUNTS:
|
| 68 |
+
raise ValueError("Unsupported native geometry")
|
| 69 |
+
groups = {g: [n for n, _ in raw if parameter_group(n) == g]
|
| 70 |
+
for g in ("frozen", *(k + "." + part for k in KINDS for part in ("encoder", "head", "scorer")))}
|
| 71 |
+
return {"counts": counts, "groups": groups}
|
| 72 |
+
|
| 73 |
+
|
| 74 |
+
def configure_training(native, *, max_input_tokens=1024):
|
| 75 |
+
"""Enable all three existing encoder/head/scorer paths; allocate no parameters."""
|
| 76 |
+
api = _api(native)
|
| 77 |
+
if native.training_state is not None:
|
| 78 |
+
raise ValueError("Restore before configuring again")
|
| 79 |
+
if type(max_input_tokens) is not int or not 1 <= max_input_tokens <= native.config["packing"]["max_length"]:
|
| 80 |
+
raise ValueError("Training token limit must fit the native complete-input cap")
|
| 81 |
+
m = native.model
|
| 82 |
+
m.verify_inventory(check_values=False)
|
| 83 |
+
native.contract.validate_encoder_config(m.encoder.config)
|
| 84 |
+
for blocks, _, _, _ in _roots(m).values():
|
| 85 |
+
if len(blocks) != 22:
|
| 86 |
+
raise ValueError("Three full 22-layer paths required")
|
| 87 |
+
for index, layer in enumerate(blocks):
|
| 88 |
+
api.layer_gate(layer, index)
|
| 89 |
+
for name, p in m.named_parameters():
|
| 90 |
+
p.requires_grad_(parameter_group(name) != "frozen")
|
| 91 |
+
p.grad = None
|
| 92 |
+
native.training_state = {"identities": _identities(m), "training": False,
|
| 93 |
+
"max_input_tokens": max_input_tokens}
|
| 94 |
+
set_training_mode(native, False)
|
| 95 |
+
return inventory(native)
|
| 96 |
+
|
| 97 |
+
|
| 98 |
+
def _assert_modes(native):
|
| 99 |
+
m, state = native.model, native.training_state
|
| 100 |
+
if state is None:
|
| 101 |
+
raise ValueError("Call configure_training first")
|
| 102 |
+
selected = {id(child) for roots in _roots(m).values() for root in roots for child in root.modules()}
|
| 103 |
+
if m.training != state["training"] or _identities(m) != state["identities"]:
|
| 104 |
+
raise ValueError("Mode or parameter/optimizer identity changed")
|
| 105 |
+
for module in m.modules():
|
| 106 |
+
if module is not m and module.training != (state["training"] and id(module) in selected):
|
| 107 |
+
raise ValueError("Active/frozen module mode drift; use set_training_mode")
|
| 108 |
+
if any(p.requires_grad != (parameter_group(n) != "frozen") for n, p in m.named_parameters()):
|
| 109 |
+
raise ValueError("Training requires_grad drift")
|
| 110 |
+
|
| 111 |
+
|
| 112 |
+
def set_training_mode(native, training=True):
|
| 113 |
+
if type(training) is not bool or native.training_state is None:
|
| 114 |
+
raise ValueError("Configured boolean training mode required")
|
| 115 |
+
m = native.model
|
| 116 |
+
m.eval()
|
| 117 |
+
m.training = training
|
| 118 |
+
for roots in _roots(m).values():
|
| 119 |
+
for module in roots:
|
| 120 |
+
module.train(training)
|
| 121 |
+
native.training_state["training"] = training
|
| 122 |
+
_assert_modes(native)
|
| 123 |
+
|
| 124 |
+
|
| 125 |
+
def optimizer_groups(native, *, encoder_lr, head_lr):
|
| 126 |
+
"""Return disjoint complete groups; no optimizer or scheduler is created."""
|
| 127 |
+
if any(not math.isfinite(x) or x <= 0 for x in (encoder_lr, head_lr)):
|
| 128 |
+
raise ValueError("Positive finite learning rates required")
|
| 129 |
+
info = inventory(native)
|
| 130 |
+
params = dict(native.model.named_parameters())
|
| 131 |
+
return [{"name": group, "params": [params[n] for n in names],
|
| 132 |
+
"lr": encoder_lr if group.endswith("encoder") else head_lr}
|
| 133 |
+
for group, names in info["groups"].items() if group != "frozen"]
|
| 134 |
+
|
| 135 |
+
|
| 136 |
+
def _validate_batch(native, batch):
|
| 137 |
+
import torch
|
| 138 |
+
required = {"input_ids", "attention_mask", "marker_positions", "valid_candidates", "targets", "values", "kind_ids"}
|
| 139 |
+
if set(batch) != required or any(not isinstance(t, torch.Tensor) for t in batch.values()):
|
| 140 |
+
raise ValueError("Use the native collator's complete batch dictionary")
|
| 141 |
+
ids, mask, kinds = batch["input_ids"], batch["attention_mask"], batch["kind_ids"]
|
| 142 |
+
pos, valid = batch["marker_positions"], batch["valid_candidates"]
|
| 143 |
+
_amd_device(ids.device)
|
| 144 |
+
if any(p.device != ids.device for p in native.model.parameters()) or any(t.device != ids.device for t in batch.values()):
|
| 145 |
+
raise ValueError("All parameters and batch tensors must share the actual AMD device")
|
| 146 |
+
if (ids.dtype != torch.long or ids.ndim != 2 or ids.shape[0] < 1
|
| 147 |
+
or not 1 <= ids.shape[1] <= native.training_state["max_input_tokens"]
|
| 148 |
+
or mask.dtype != torch.bool or mask.shape != ids.shape
|
| 149 |
+
or kinds.dtype != torch.long or kinds.shape != (ids.shape[0],)):
|
| 150 |
+
raise ValueError("Invalid complete B x L input")
|
| 151 |
+
if (pos.dtype != torch.long or valid.dtype != torch.bool or pos.ndim != 2
|
| 152 |
+
or pos.shape != valid.shape or pos.shape[0] != ids.shape[0]
|
| 153 |
+
or not 2 <= pos.shape[1] <= 255 or (pos < 0).any().item()
|
| 154 |
+
or (pos >= ids.shape[1]).any().item()):
|
| 155 |
+
raise ValueError("Invalid candidate markers")
|
| 156 |
+
counts = valid.sum(-1)
|
| 157 |
+
prefix = torch.arange(valid.shape[1], device=ids.device)[None] < counts[:, None]
|
| 158 |
+
if (counts < 2).any().item() or not torch.equal(prefix, valid):
|
| 159 |
+
raise ValueError("At least two candidates, then contiguous padding required")
|
| 160 |
+
if not mask.gather(1, pos)[valid].all().item() or not mask.any(-1).all().item():
|
| 161 |
+
raise ValueError("Candidate marker points into padding")
|
| 162 |
+
if not torch.equal(mask, torch.arange(ids.shape[1], device=ids.device)[None] < mask.sum(-1)[:, None]):
|
| 163 |
+
raise ValueError("Native right-padding layout required")
|
| 164 |
+
if ((pos[:, 1:] <= pos[:, :-1]) & valid[:, 1:]).any().item():
|
| 165 |
+
raise ValueError("Candidate markers must retain their original sequence order")
|
| 166 |
+
if ((kinds < 0) | (kinds > 2)).any().item() or (counts[kinds == 1] != 2).any().item():
|
| 167 |
+
raise ValueError("Unknown type or non-binary Noul")
|
| 168 |
+
if batch["targets"].shape != valid.shape or batch["values"].shape != valid.shape:
|
| 169 |
+
raise ValueError("Target/value shape mismatch")
|
| 170 |
+
values = batch["values"]
|
| 171 |
+
if values.dtype != torch.float32 or not torch.isfinite(values).all().item():
|
| 172 |
+
raise ValueError("Finite FP32 values required")
|
| 173 |
+
scored = (kinds == 2)[:, None] & valid[:, 1:]
|
| 174 |
+
if ((values[:, 1:] <= values[:, :-1]) & scored).any().item():
|
| 175 |
+
raise ValueError("Score values must remain strictly increasing")
|
| 176 |
+
|
| 177 |
+
|
| 178 |
+
def forward_for_training(native, batch):
|
| 179 |
+
"""Full-B×L suffixes, typed row gathering only at heads; no native monkeypatch."""
|
| 180 |
+
import torch
|
| 181 |
+
from torch.utils.checkpoint import checkpoint
|
| 182 |
+
api = _api(native)
|
| 183 |
+
_assert_modes(native)
|
| 184 |
+
_validate_batch(native, batch)
|
| 185 |
+
if native.training_state["training"] and not torch.is_grad_enabled():
|
| 186 |
+
raise ValueError("Training forward requires autograd")
|
| 187 |
+
m = native.model
|
| 188 |
+
ids, mask = batch["input_ids"], batch["attention_mask"]
|
| 189 |
+
kinds, valid, positions = batch["kind_ids"], batch["valid_candidates"], batch["marker_positions"]
|
| 190 |
+
routes = api.route_indices(kinds)
|
| 191 |
+
m.encoder._maybe_set_compile()
|
| 192 |
+
position_ids = torch.arange(ids.shape[1], device=ids.device).unsqueeze(0)
|
| 193 |
+
global_mask, local_mask = m.encoder._update_attention_mask(mask, output_attentions=False)
|
| 194 |
+
kwargs = dict(attention_mask=global_mask, sliding_window_mask=local_mask,
|
| 195 |
+
position_ids=position_ids, cu_seqlens=None, max_seqlen=None, output_attentions=False)
|
| 196 |
+
with torch.no_grad():
|
| 197 |
+
embedded = m.encoder.embeddings(input_ids=ids, inputs_embeds=None)
|
| 198 |
+
hidden = {}
|
| 199 |
+
roots = _roots(m)
|
| 200 |
+
for name, indices in routes:
|
| 201 |
+
if indices.numel() == 0:
|
| 202 |
+
continue
|
| 203 |
+
blocks, norm, _, _ = roots[name]
|
| 204 |
+
h = m._suffix(embedded, blocks, norm, kwargs)
|
| 205 |
+
with torch.no_grad():
|
| 206 |
+
type_value = m.type_embedding(kinds)[:, None, :]
|
| 207 |
+
hidden[name] = h + type_value.to(h.dtype)
|
| 208 |
+
pad = ~mask.bool()
|
| 209 |
+
out = torch.empty(positions.shape, device=ids.device, dtype=torch.float32)
|
| 210 |
+
for name, indices in routes:
|
| 211 |
+
if indices.numel() == 0:
|
| 212 |
+
continue
|
| 213 |
+
h = hidden[name].index_select(0, indices)
|
| 214 |
+
branch_pad = pad.index_select(0, indices)
|
| 215 |
+
for layer in m.heads[name]:
|
| 216 |
+
h = (checkpoint(layer, h, src_key_padding_mask=branch_pad, use_reentrant=False)
|
| 217 |
+
if layer.training and m.head_config["gradient_checkpointing"]
|
| 218 |
+
else layer(h, src_key_padding_mask=branch_pad))
|
| 219 |
+
loc = positions.index_select(0, indices)
|
| 220 |
+
markers = torch.gather(h, 1, loc[:, :, None].expand(-1, -1, h.shape[-1]))
|
| 221 |
+
logits = m.scorers[name](markers).squeeze(-1).float()
|
| 222 |
+
out = api.scatter_rows(out, indices, logits)
|
| 223 |
+
return out.masked_fill(~valid, torch.finfo(torch.float32).min)
|
| 224 |
+
|
| 225 |
+
|
| 226 |
+
def loss_for_training(native, logits, batch, *, score_rps_weight=0.0):
|
| 227 |
+
"""Return (per-row total, CE, RPS); caller chooses the logical-batch denominator."""
|
| 228 |
+
import torch
|
| 229 |
+
if not math.isfinite(score_rps_weight) or score_rps_weight < 0:
|
| 230 |
+
raise ValueError("Nonnegative finite Score RPS weight required")
|
| 231 |
+
target, valid = batch["targets"], batch["valid_candidates"]
|
| 232 |
+
if (logits.shape != target.shape or target.shape != valid.shape
|
| 233 |
+
or target.dtype != torch.float32 or not torch.isfinite(logits).all().item()
|
| 234 |
+
or not torch.isfinite(target).all().item() or ((target < 0) | (target > 1)).any().item()
|
| 235 |
+
or target[~valid].count_nonzero().item() or not torch.allclose(target.sum(-1), torch.ones_like(target[:, 0]), atol=1e-6, rtol=0)):
|
| 236 |
+
raise ValueError("Explicit normalized hard/soft targets and finite masked logits required")
|
| 237 |
+
return native.model_api.typed_loss(logits, batch, score_rps_weight=score_rps_weight)
|
| 238 |
+
|
| 239 |
+
|
| 240 |
+
def _tensor_sha(tensor):
|
| 241 |
+
import hashlib
|
| 242 |
+
return hashlib.sha256(tensor.detach().cpu().contiguous().numpy().tobytes()).hexdigest()
|
| 243 |
+
|
| 244 |
+
|
| 245 |
+
def frozen_snapshot(native):
|
| 246 |
+
inventory(native)
|
| 247 |
+
_assert_modes(native)
|
| 248 |
+
ps = dict(native.model.named_parameters())
|
| 249 |
+
return {n: {"version": int(ps[n]._version), "sha256": _tensor_sha(ps[n])} for n in FROZEN}
|
| 250 |
+
|
| 251 |
+
|
| 252 |
+
def assert_frozen(native, snapshot, *, content=False, versions=True):
|
| 253 |
+
_assert_modes(native)
|
| 254 |
+
ps = dict(native.model.named_parameters())
|
| 255 |
+
if set(snapshot) != set(FROZEN):
|
| 256 |
+
raise ValueError("Expected exactly the three shared frozen parameters")
|
| 257 |
+
for name, saved in snapshot.items():
|
| 258 |
+
p = ps[name]
|
| 259 |
+
if (p.requires_grad or p.grad is not None or (versions and int(p._version) != saved["version"])
|
| 260 |
+
or (content and _tensor_sha(p) != saved["sha256"])):
|
| 261 |
+
raise ValueError("Frozen parameter changed: " + name)
|
| 262 |
+
return True
|
| 263 |
+
|
| 264 |
+
|
| 265 |
+
def gradient_report(native, *, present_types):
|
| 266 |
+
"""Check groups actually present in the logical batch; absent grads must be None."""
|
| 267 |
+
import torch
|
| 268 |
+
if not present_types or not set(present_types) <= set(KINDS):
|
| 269 |
+
raise ValueError("Explicit nonempty logical-batch type set required")
|
| 270 |
+
info = inventory(native)
|
| 271 |
+
ps = dict(native.model.named_parameters())
|
| 272 |
+
report = {}
|
| 273 |
+
for group, names in info["groups"].items():
|
| 274 |
+
active = group != "frozen" and group.split(".")[0] in present_types
|
| 275 |
+
gradients = [ps[n].grad for n in names]
|
| 276 |
+
if not active:
|
| 277 |
+
if any(g is not None for g in gradients):
|
| 278 |
+
raise ValueError("Frozen/absent group has stale gradients: " + group)
|
| 279 |
+
continue
|
| 280 |
+
if any(g is None or not torch.isfinite(g).all().item() for g in gradients):
|
| 281 |
+
raise ValueError("Missing or nonfinite gradient: " + group)
|
| 282 |
+
norms = [float(g.float().norm().item()) for g in gradients]
|
| 283 |
+
if not any(n > 0 for n in norms):
|
| 284 |
+
raise ValueError("No nonzero gradient: " + group)
|
| 285 |
+
report[group] = {"tensors": len(names), "nonzero_tensors": sum(n > 0 for n in norms),
|
| 286 |
+
"l2": math.sqrt(sum(n * n for n in norms))}
|
| 287 |
+
return report
|
| 288 |
+
|
| 289 |
+
|
| 290 |
+
def restore_native_policy_for_export(native):
|
| 291 |
+
"""Clear gradients and restore the original strict metadata, without replacing parameters."""
|
| 292 |
+
_assert_modes(native)
|
| 293 |
+
inventory(native)
|
| 294 |
+
m, state, contract = native.model, native.training_state, native.contract
|
| 295 |
+
policy = contract.training_policy(m.training_arm)
|
| 296 |
+
sources = {p.name: sha256(p) for p in sorted(Path(__file__).parent.glob("*.py")) if p.name != "checks.py"}
|
| 297 |
+
provenance = {"actual_training_policy": "all_three_full22_paths_and_heads",
|
| 298 |
+
"counts": dict(COUNTS), "complete_input_limit": state["max_input_tokens"],
|
| 299 |
+
"native_policy_is_not_actual_training_provenance": True,
|
| 300 |
+
"restored_native_trainability_mode": policy, "adapter_sources_sha256": sources}
|
| 301 |
+
for n, p in m.named_parameters():
|
| 302 |
+
p.requires_grad_(contract.trainable_name(n, policy))
|
| 303 |
+
p.grad = None
|
| 304 |
+
m.eval()
|
| 305 |
+
m.verify_inventory(check_values=False)
|
| 306 |
+
if _identities(m) != state["identities"]:
|
| 307 |
+
raise ValueError("Restoration replaced parameter objects")
|
| 308 |
+
native.training_state = None
|
| 309 |
+
native.last_training_provenance = provenance
|
| 310 |
+
return provenance
|
examples/decisions.jsonl
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{"id":"route","state_text":"The customer asks for a refund for a duplicate charge.","question":{"id":"route-q","type":"Choice","text":"Which team should handle this request?","options":[{"id":"billing","text":"Billing and payments"},{"id":"technical","text":"Technical support"},{"id":"sales","text":"Sales enquiries"}]}}
|
| 2 |
+
{"id":"evidence","state_text":"The package was delivered on Monday. A signed receipt is available.","question":{"id":"evidence-q","type":"Noul","text":"Does the evidence confirm that the package was delivered?"}}
|
| 3 |
+
{"id":"sentiment","state_text":"The replacement arrived quickly and works perfectly.","question":{"id":"sentiment-q","type":"Score","text":"How positive is the customer's sentiment?","levels":[{"id":"negative","text":"Negative","value":0},{"id":"neutral","text":"Neutral","value":1},{"id":"positive","text":"Positive","value":2}]}}
|
examples/finetune.sh
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
#!/usr/bin/env bash
|
| 2 |
+
set -euo pipefail
|
| 3 |
+
# Run from the package root in an existing compatible AMD ROCm environment.
|
| 4 |
+
# Replace these paths with your own isolated TRAIN and DEV JSONL files.
|
| 5 |
+
: "${TRAIN:?Set TRAIN to your training JSONL}"
|
| 6 |
+
: "${DEV:?Set DEV to your development JSONL}"
|
| 7 |
+
: "${OUTPUT:?Set OUTPUT to a fresh run directory}"
|
| 8 |
+
NATIVE="${NATIVE:-./native}"
|
| 9 |
+
MANIFEST_SHA256="${MANIFEST_SHA256:-f288d873999832a3f37c6a7c4268c2ab309691e621794dbf7acab891acbbb7e6}"
|
| 10 |
+
export PYTHONPATH="${PWD}${PYTHONPATH:+:${PYTHONPATH}}"
|
| 11 |
+
export PYTHONDONTWRITEBYTECODE=1 HF_HUB_OFFLINE=1 TRANSFORMERS_OFFLINE=1 TOKENIZERS_PARALLELISM=false
|
| 12 |
+
python -m decision_finetune validate-jsonl --train "$TRAIN" --dev "$DEV" --selection macro-nll
|
| 13 |
+
# Device visibility is supplied by the caller, e.g. ROCR_VISIBLE_DEVICES=0.
|
| 14 |
+
python -m decision_finetune train \
|
| 15 |
+
--native "$NATIVE" --manifest-sha256 "$MANIFEST_SHA256" \
|
| 16 |
+
--train "$TRAIN" --dev "$DEV" --output "$OUTPUT" \
|
| 17 |
+
--epochs 4 --logical-batch-size 64 --micro-batch-size 8 --seed 20260921 \
|
| 18 |
+
--encoder-lr 2.5e-5 --head-lr 1e-4 --lr-min 1e-6 \
|
| 19 |
+
--weight-decay 0.01 --clip-norm 1 --score-rps-weight 0.1 \
|
| 20 |
+
--warmup-ratio 0.1 --selection macro-nll --selection-tolerance 1e-8 \
|
| 21 |
+
--cpu-threads 2 --max-reserved-gib 64
|