


Add English and Chinese model cards with showcase assets
Browse files- .gitattributes +9 -0
- README.md +198 -0
- README_CN.md +201 -0
- assets/loop-mhc-overview.jpg +3 -0
- assets/loop9b-architecture.svg +37 -0
- assets/loop9b-benchmark-results.png +3 -0
- examples/chocolate/chocolate-horizontal.jpg +3 -0
- examples/energy-analysis/energy-analysis.png +3 -0
- examples/iceland/iceland-horizontal-v2.jpg +3 -0
- examples/ink-journey/ink-journey-demo.mp4 +3 -0
- examples/ink-journey/ink-journey-preview.gif +3 -0
- examples/moon-simulation/moon-simulation.gif +3 -0
- examples/teacher-day/teacher-day-horizontal.jpg +3 -0
.gitattributes
CHANGED
|
@@ -33,3 +33,12 @@ saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
assets/loop-mhc-overview.jpg filter=lfs diff=lfs merge=lfs -text
|
| 37 |
+
assets/loop9b-benchmark-results.png filter=lfs diff=lfs merge=lfs -text
|
| 38 |
+
examples/chocolate/chocolate-horizontal.jpg filter=lfs diff=lfs merge=lfs -text
|
| 39 |
+
examples/energy-analysis/energy-analysis.png filter=lfs diff=lfs merge=lfs -text
|
| 40 |
+
examples/iceland/iceland-horizontal-v2.jpg filter=lfs diff=lfs merge=lfs -text
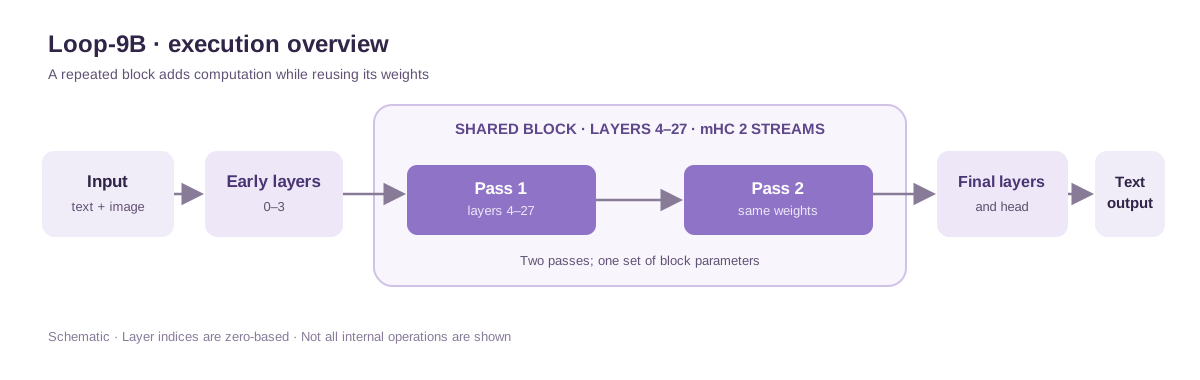
|
| 41 |
+
examples/ink-journey/ink-journey-demo.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 42 |
+
examples/ink-journey/ink-journey-preview.gif filter=lfs diff=lfs merge=lfs -text
|
| 43 |
+
examples/moon-simulation/moon-simulation.gif filter=lfs diff=lfs merge=lfs -text
|
| 44 |
+
examples/teacher-day/teacher-day-horizontal.jpg filter=lfs diff=lfs merge=lfs -text
|
README.md
CHANGED
|
@@ -1,3 +1,201 @@
|
|
| 1 |
---
|
| 2 |
license: apache-2.0
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 3 |
---
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
---
|
| 2 |
license: apache-2.0
|
| 3 |
+
language:
|
| 4 |
+
- en
|
| 5 |
+
- zh
|
| 6 |
+
library_name: transformers
|
| 7 |
+
pipeline_tag: image-text-to-text
|
| 8 |
+
tags:
|
| 9 |
+
- multimodal
|
| 10 |
+
- text-generation
|
| 11 |
+
- image-text-to-text
|
| 12 |
+
- looped-transformer
|
| 13 |
+
- mhc
|
| 14 |
+
- custom_code
|
| 15 |
---
|
| 16 |
+
|
| 17 |
+
# SenseNova-6.8-Loop-9B-Preview
|
| 18 |
+
|
| 19 |
+
<p align="center">
|
| 20 |
+
<strong>English</strong> | <a href="https://huggingface.co/sensenova/SenseNova-6.8-Loop-9B-Preview/blob/main/README_CN.md">简体中文</a>
|
| 21 |
+
</p>
|
| 22 |
+
|
| 23 |
+

|
| 24 |
+
|
| 25 |
+
## 📣 News
|
| 26 |
+
|
| 27 |
+
- `[2026.10.30]` We release **SenseNova-6.8-Loop-9B-Preview**, a looped multimodal model for long-context and agentic workflows.
|
| 28 |
+
|
| 29 |
+
## Overview
|
| 30 |
+
|
| 31 |
+
**SenseNova-6.8-Loop-9B-Preview** is a multimodal language model developed for long-context and agentic workflows. It accepts text and images and generates text for applications that combine document understanding, coding, and interaction with external tools.
|
| 32 |
+
|
| 33 |
+
The model combines a **looped decoder with two-stream manifold-constrained hyper-connections (mHC)**. A contiguous block of decoder layers is executed twice with shared weights, while learned mappings manage information flow between two residual streams in the looped section. Together, these components provide a deeper execution path without duplicating the repeated block's parameters.
|
| 34 |
+
|
| 35 |
+
Documented training recipes combine long sequences, multimodal inputs, and supervised task trajectories, with a maximum training sequence length of 262,144 tokens. Model behavior and deployment limits depend on the released checkpoint and inference implementation.
|
| 36 |
+
|
| 37 |
+
### Model highlights
|
| 38 |
+
|
| 39 |
+
- **Shared looped block:** 24 decoder layers are applied twice in sequence, producing 56 decoder-layer executions from 32 distinct layers.
|
| 40 |
+
- **Two-stream mHC:** learned mappings route and combine information across two residual streams in the looped section.
|
| 41 |
+
- **Hybrid attention:** the decoder interleaves linear and full attention in a repeating four-layer pattern.
|
| 42 |
+
- **Long-context multimodal training:** documented recipes include text, images, code, and tool trajectories at sequence lengths up to 256K tokens.
|
| 43 |
+
|
| 44 |
+
## Showcase (Created by Raccoon Work)
|
| 45 |
+
|
| 46 |
+
### Motion Design
|
| 47 |
+
|
| 48 |
+
[](examples/ink-journey/ink-journey-demo.mp4)
|
| 49 |
+
|
| 50 |
+
### PPT Design
|
| 51 |
+
|
| 52 |
+

|
| 53 |
+
|
| 54 |
+

|
| 55 |
+
|
| 56 |
+

|
| 57 |
+
|
| 58 |
+
### Data Analysis
|
| 59 |
+
|
| 60 |
+

|
| 61 |
+
|
| 62 |
+

|
| 63 |
+
|
| 64 |
+
## 📊 Key Benchmarks
|
| 65 |
+
|
| 66 |
+

|
| 67 |
+
|
| 68 |
+
## Model Specifications
|
| 69 |
+
|
| 70 |
+
| Property | SenseNova-6.8-Loop-9B-Preview |
|
| 71 |
+
| --- | --- |
|
| 72 |
+
| Architecture | Autoregressive multimodal decoder; looped block with two-stream mHC |
|
| 73 |
+
| Backbone scale | ~9B total parameters; ~14.6B inference parameters |
|
| 74 |
+
| Input / output | Text and images / text |
|
| 75 |
+
| Distinct decoder layers | 32 |
|
| 76 |
+
| Looped layers / passes | [4, 28) / 2, with shared weights |
|
| 77 |
+
| Decoder layer executions | 56 per forward pass |
|
| 78 |
+
| mHC streams | 2 |
|
| 79 |
+
| Training context | Up to 262,144 tokens |
|
| 80 |
+
| Existing export precision | BF16 backbone; FP32 mHC routing parameters |
|
| 81 |
+
|
| 82 |
+
Training sequence length is a configuration, not a guarantee of inference support or performance at every length.
|
| 83 |
+
|
| 84 |
+
## Model Architecture
|
| 85 |
+
|
| 86 |
+
SenseNova-6.8-Loop-9B-Preview combines a 32-layer multimodal decoder with a repeated middle block. The figure illustrates the order of computation; the detailed operations inside each layer and the vision encoder are omitted.
|
| 87 |
+
|
| 88 |
+

|
| 89 |
+
|
| 90 |
+
*Figure 1. Decoder execution order. Layer indices are zero-based; the two passes share block weights.*
|
| 91 |
+
|
| 92 |
+
### Looped decoder
|
| 93 |
+
|
| 94 |
+
The decoder first processes the input through layers 0–3. The same block of layers 4–27 is then applied twice in sequence, after which layers 28–31 and the output head produce the model's output. If *B* represents the repeated block and *h* its input, the looped computation can be written as **B(B(h))**.
|
| 95 |
+
|
| 96 |
+
The second pass takes the first pass's output as its input. Because both passes use the same layer weights, the model has **32 distinct decoder layers but 56 decoder-layer executions** per forward pass. Parameter sharing avoids duplicating the repeated block, while the additional pass still adds computation.
|
| 97 |
+
|
| 98 |
+
### Hybrid attention
|
| 99 |
+
|
| 100 |
+
The decoder interleaves linear-attention and full-attention layers. Each four-layer group contains three linear-attention layers followed by one full-attention layer. The loop boundaries align with complete four-layer groups, so the attention pattern is preserved across both passes.
|
| 101 |
+
|
| 102 |
+
### Two-stream mHC
|
| 103 |
+
|
| 104 |
+
Inside the looped section, mHC carries two residual streams around the decoder-layer computations. Learned mappings govern how a layer reads from the streams, mixes stream information, and incorporates the layer output into the residual state. Sinkhorn normalization constrains the stream-mixing map; the documented configuration uses 20 iterations.
|
| 105 |
+
|
| 106 |
+
The loop range, pass count, and mHC routing parameters form part of the checkpoint's execution configuration. A compatible inference implementation must load these parameters and reproduce the same execution order.
|
| 107 |
+
|
| 108 |
+
| Configuration | Value |
|
| 109 |
+
| --- | --- |
|
| 110 |
+
| Distinct decoder layers / executions | 32 / 56 |
|
| 111 |
+
| Repeated block / passes | [4, 28) / 2 |
|
| 112 |
+
| Hidden dimension | 4,096 |
|
| 113 |
+
| Feed-forward dimension | 12,288 |
|
| 114 |
+
| Vocabulary size | 248,320 |
|
| 115 |
+
| Full-attention heads / KV heads | 16 / 4 |
|
| 116 |
+
| mHC streams / Sinkhorn iterations | 2 / 20 |
|
| 117 |
+
|
| 118 |
+
## Inference Acceleration
|
| 119 |
+
|
| 120 |
+
SenseNova-6.8-Loop-9B-Preview supports **MTP** for accelerated inference. **Dspark** and **Dflash2** are under development, with training currently in progress.
|
| 121 |
+
|
| 122 |
+
| Method | Status |
|
| 123 |
+
| --- | --- |
|
| 124 |
+
| MTP | Available |
|
| 125 |
+
| Dspark | Training in progress |
|
| 126 |
+
| Dflash2 | Training in progress |
|
| 127 |
+
|
| 128 |
+
Practical speedups depend on the workload, hardware, and serving configuration.
|
| 129 |
+
|
| 130 |
+
See [OpenSenseNova/SenseSpec](https://github.com/OpenSenseNova/SenseSpec) for our speculative decoding training code.
|
| 131 |
+
|
| 132 |
+
## Models and Resources
|
| 133 |
+
|
| 134 |
+
| Resource | Status |
|
| 135 |
+
| --- | --- |
|
| 136 |
+
| Model weights | [Hugging Face model page](https://huggingface.co/sensenova/SenseNova-6.8-Loop-9B-Preview) |
|
| 137 |
+
| Transformers inference implementation | Publication details to be announced |
|
| 138 |
+
| Technical report | To be announced |
|
| 139 |
+
|
| 140 |
+
## Quick Start
|
| 141 |
+
|
| 142 |
+
Use Transformers to load the model and its custom implementation from a prepared model directory. The example below runs text generation on a single GPU.
|
| 143 |
+
|
| 144 |
+
### Requirements
|
| 145 |
+
|
| 146 |
+
The checked inference environment uses **Transformers 5.18.0** and **PyTorch 2.11.0 with CUDA 13.0**. The model directory must include the configuration, tokenizer, chat template, model code, and accessible weight shards.
|
| 147 |
+
|
| 148 |
+
### Text generation with Transformers
|
| 149 |
+
|
| 150 |
+
Set `model_id` to the prepared model directory, then run:
|
| 151 |
+
|
| 152 |
+
```python
|
| 153 |
+
import torch
|
| 154 |
+
from transformers import AutoModelForCausalLM, AutoTokenizer
|
| 155 |
+
|
| 156 |
+
model_id = "/path/to/model-directory"
|
| 157 |
+
device = "cuda:0"
|
| 158 |
+
|
| 159 |
+
tokenizer = AutoTokenizer.from_pretrained(model_id, trust_remote_code=True)
|
| 160 |
+
model = AutoModelForCausalLM.from_pretrained(
|
| 161 |
+
model_id,
|
| 162 |
+
trust_remote_code=True,
|
| 163 |
+
dtype=torch.bfloat16,
|
| 164 |
+
device_map={"": device},
|
| 165 |
+
).eval()
|
| 166 |
+
|
| 167 |
+
messages = [{"role": "user", "content": "What is 13 times 7? Reply with the number only."}]
|
| 168 |
+
prompt = tokenizer.apply_chat_template(
|
| 169 |
+
messages,
|
| 170 |
+
tokenize=False,
|
| 171 |
+
add_generation_prompt=True,
|
| 172 |
+
enable_thinking=False,
|
| 173 |
+
)
|
| 174 |
+
inputs = tokenizer(prompt, return_tensors="pt").to(device)
|
| 175 |
+
|
| 176 |
+
with torch.inference_mode():
|
| 177 |
+
outputs = model.generate(
|
| 178 |
+
**inputs,
|
| 179 |
+
max_new_tokens=256,
|
| 180 |
+
do_sample=False,
|
| 181 |
+
use_cache=True,
|
| 182 |
+
)
|
| 183 |
+
|
| 184 |
+
response = tokenizer.decode(
|
| 185 |
+
outputs[0, inputs.input_ids.shape[1]:],
|
| 186 |
+
skip_special_tokens=True,
|
| 187 |
+
)
|
| 188 |
+
print(response)
|
| 189 |
+
```
|
| 190 |
+
|
| 191 |
+
The example uses greedy decoding and generates up to 256 new tokens. Set `enable_thinking=True` to enable thinking mode, or change `device` to select another GPU.
|
| 192 |
+
|
| 193 |
+
`trust_remote_code=True` loads the custom model implementation from the model directory. Review model code before loading it from an untrusted source. The example follows the previously validated single-GPU inference script; image input and tool calling are not covered by this example.
|
| 194 |
+
|
| 195 |
+
### Training
|
| 196 |
+
|
| 197 |
+
The model is trained using [OpenSenseNova/torchtitan](https://github.com/OpenSenseNova/torchtitan); see the `example/train` directory in the repository for training examples.
|
| 198 |
+
|
| 199 |
+
## License and citation
|
| 200 |
+
|
| 201 |
+
**License:** To be determined for the released weights and code.<br>**Citation:** To be added with the release.
|
README_CN.md
ADDED
|
@@ -0,0 +1,201 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
license: apache-2.0
|
| 3 |
+
language:
|
| 4 |
+
- en
|
| 5 |
+
- zh
|
| 6 |
+
library_name: transformers
|
| 7 |
+
pipeline_tag: image-text-to-text
|
| 8 |
+
tags:
|
| 9 |
+
- multimodal
|
| 10 |
+
- text-generation
|
| 11 |
+
- image-text-to-text
|
| 12 |
+
- looped-transformer
|
| 13 |
+
- mhc
|
| 14 |
+
- custom_code
|
| 15 |
+
---
|
| 16 |
+
|
| 17 |
+
# SenseNova-6.8-Loop-9B-Preview
|
| 18 |
+
|
| 19 |
+
<p align="center">
|
| 20 |
+
<a href="https://huggingface.co/sensenova/SenseNova-6.8-Loop-9B-Preview/blob/main/README.md">English</a> | <strong>简体中文</strong>
|
| 21 |
+
</p>
|
| 22 |
+
|
| 23 |
+

|
| 24 |
+
|
| 25 |
+
## 📣 最新动态
|
| 26 |
+
|
| 27 |
+
- `[2026.10.30]` 我们发布了 **SenseNova-6.8-Loop-9B-Preview**,一个面向长上下文与智能体工作流的循环多模态模型。
|
| 28 |
+
|
| 29 |
+
## 模型概述
|
| 30 |
+
|
| 31 |
+
**SenseNova-6.8-Loop-9B-Preview** 是一个面向长上下文和智能体工作流的多模态语言模型。模型接收文本和图像输入,生成文本输出,适用于结合文档理解、编程及外部工具交互的应用。
|
| 32 |
+
|
| 33 |
+
模型将**循环解码器与双流流形约束超连接(mHC)**相结合。一段连续的解码器层共享权重,依次执行两遍;循环模块中的可学习映射负责管理两条残差流之间的信息流动。通过这种设计,模型无需复制循环模块的参数,就能增加实际执行深度。
|
| 34 |
+
|
| 35 |
+
已有训练方案结合了长序列、多模态输入和带监督的任务轨迹,最长训练序列为 262,144 个 token。模型的实际表现和部署限制取决于发布的模型检查点及推理实现。
|
| 36 |
+
|
| 37 |
+
### 模型亮点
|
| 38 |
+
|
| 39 |
+
- **共享循环模块:**24 个解码器层依次执行两遍,使 32 个独立层在一次前向传播中完成 56 次层计算。
|
| 40 |
+
- **双流 mHC:**通过可学习映射,对循环模块中两条残差流的信息进行路由与融合。
|
| 41 |
+
- **混合注意力:**解码器以四层为一个循环单元,交替使用线性注意力与全注意力。
|
| 42 |
+
- **长上下文多模态训练:**已有训练方案涵盖文本、图像、代码和工具调用轨迹,序列长度最长为 256K token。
|
| 43 |
+
|
| 44 |
+
## 效果展示(由商汤小浣熊创作)
|
| 45 |
+
|
| 46 |
+
### 动效设计
|
| 47 |
+
|
| 48 |
+
[](examples/ink-journey/ink-journey-demo.mp4)
|
| 49 |
+
|
| 50 |
+
### PPT 设计
|
| 51 |
+
|
| 52 |
+

|
| 53 |
+
|
| 54 |
+

|
| 55 |
+
|
| 56 |
+

|
| 57 |
+
|
| 58 |
+
### 数据分析
|
| 59 |
+
|
| 60 |
+

|
| 61 |
+
|
| 62 |
+

|
| 63 |
+
|
| 64 |
+
## 📊 核心评测
|
| 65 |
+
|
| 66 |
+

|
| 67 |
+
|
| 68 |
+
## 模型规格
|
| 69 |
+
|
| 70 |
+
| 项目 | SenseNova-6.8-Loop-9B-Preview |
|
| 71 |
+
| --- | --- |
|
| 72 |
+
| 架构 | 自回归多模态解码器;循环模块采用双流 mHC |
|
| 73 |
+
| 参数规模 | 总共约 9B 参数,推理实际约 14.6B 参数 |
|
| 74 |
+
| 输入 / 输出 | 文本和图像 / 文本 |
|
| 75 |
+
| 独立解码器层数 | 32 |
|
| 76 |
+
| 循环层范围 / 执行次数 | [4, 28) / 2 次,共享权重 |
|
| 77 |
+
| 解码器层执行次数 | 每次前向传播执行 56 次 |
|
| 78 |
+
| mHC 残差流数量 | 2 |
|
| 79 |
+
| 训练上下文长度 | 最长 262,144 个 token |
|
| 80 |
+
| 现有导出精度 | 主干为 BF16;mHC 路由参数为 FP32 |
|
| 81 |
+
|
| 82 |
+
训练序列长度属于训练配置,并不代表推理实现支持所有对应长度,也不构成各长度下的性能保证。
|
| 83 |
+
|
| 84 |
+
## 模型架构
|
| 85 |
+
|
| 86 |
+
SenseNova-6.8-Loop-9B-Preview 采用 32 层多模态解码器,其中的中间层模块会重复执行。下图展示了计算顺序,省略了各层内部操作和视觉编码器的细节。
|
| 87 |
+
|
| 88 |
+

|
| 89 |
+
|
| 90 |
+
*图 1:解码器的执行顺序。层编号从 0 开始,两次循环执行共享模块权重。*
|
| 91 |
+
|
| 92 |
+
### 循环解码器
|
| 93 |
+
|
| 94 |
+
输入首先经过第 0–3 层,随后依次通过同一组第 4–27 层两次,最后由第 28–31 层和输出头生成模型输出。若用 *B* 表示循环模块、*h* 表示其输入,则循环计算可写为 **B(B(h))**。
|
| 95 |
+
|
| 96 |
+
第二次执行以第一次的输出作为输入。由于两次执行共享层权重,模型拥有 **32 个独立解码器层,但每次前向传播会执行 56 次解码器层计算**。参数共享避免了复制循环模块,但额外执行一遍仍会增加计算量。
|
| 97 |
+
|
| 98 |
+
### 混合注意力
|
| 99 |
+
|
| 100 |
+
解码器交替使用线性注意力层与全注意力层。每四层为一组,依次包含三层线性注意力和一层全注意力。循环模块的边界与完整的四层组对齐,因此两次执行都保持相同的注意力排列。
|
| 101 |
+
|
| 102 |
+
### 双流 mHC
|
| 103 |
+
|
| 104 |
+
在循环模��中,mHC 使用两条残差流传递解码器层计算前后的信息。可学习映射决定各层如何读取残差流、混合流间信息,以及将层输出写入残差状态。流间混合映射采用 Sinkhorn 归一化进行约束;已有配置使用 20 次迭代。
|
| 105 |
+
|
| 106 |
+
循环层范围、执行次数和 mHC 路由参数共同构成模型检查点的执行配置。兼容的推理实现需要加载这些参数,并保持相同的计算顺序。
|
| 107 |
+
|
| 108 |
+
| 配置 | 数值 |
|
| 109 |
+
| --- | --- |
|
| 110 |
+
| 独立解码器层数 / 执行次数 | 32 / 56 |
|
| 111 |
+
| 循环层范围 / 执行次数 | [4, 28) / 2 |
|
| 112 |
+
| 隐藏层维度 | 4,096 |
|
| 113 |
+
| 前馈网络维度 | 12,288 |
|
| 114 |
+
| 词表大小 | 248,320 |
|
| 115 |
+
| 全注意力头数 / KV 头数 | 16 / 4 |
|
| 116 |
+
| mHC 残差流数量 / Sinkhorn 迭代次数 | 2 / 20 |
|
| 117 |
+
|
| 118 |
+
## 推理加速
|
| 119 |
+
|
| 120 |
+
SenseNova-6.8-Loop-9B-Preview 已支持 **MTP** 推理加速。**Dspark** 和 **Dflash2** 正在开发中,目前处于训练阶段。
|
| 121 |
+
|
| 122 |
+
| 方法 | 状态 |
|
| 123 |
+
| --- | --- |
|
| 124 |
+
| MTP | 已可用 |
|
| 125 |
+
| Dspark | 训练中 |
|
| 126 |
+
| Dflash2 | 训练中 |
|
| 127 |
+
|
| 128 |
+
实际加速效果取决于任务负载、硬件和服务配置。
|
| 129 |
+
|
| 130 |
+
投机解码训练代码请参见 [OpenSenseNova/SenseSpec](https://github.com/OpenSenseNova/SenseSpec)。
|
| 131 |
+
|
| 132 |
+
## 模型与资源
|
| 133 |
+
|
| 134 |
+
| 资源 | 状态 |
|
| 135 |
+
| --- | --- |
|
| 136 |
+
| 模型权重 | [Hugging Face 模型页面](https://huggingface.co/sensenova/SenseNova-6.8-Loop-9B-Preview) |
|
| 137 |
+
| Transformers 推理实现 | 发布详情待公布 |
|
| 138 |
+
| 技术报告 | 待公布 |
|
| 139 |
+
|
| 140 |
+
## 快速开始
|
| 141 |
+
|
| 142 |
+
使用 Transformers 从准备好的模型目录中加载模型及其自定义实现。下面的示例展示了如何在单张 GPU 上进行文本生成。
|
| 143 |
+
|
| 144 |
+
### 环境要求
|
| 145 |
+
|
| 146 |
+
已核对的推理环境使用 **Transformers 5.18.0** 和 **PyTorch 2.11.0(CUDA 13.0)**。模型目录需要包含配置、分词器、对话模板、模型代码,以及可访问的权重分片。
|
| 147 |
+
|
| 148 |
+
### 使用 Transformers 生成文本
|
| 149 |
+
|
| 150 |
+
将 `model_id` 设置为准备好的模型目录,然后运行:
|
| 151 |
+
|
| 152 |
+
```python
|
| 153 |
+
import torch
|
| 154 |
+
from transformers import AutoModelForCausalLM, AutoTokenizer
|
| 155 |
+
|
| 156 |
+
model_id = "/path/to/model-directory"
|
| 157 |
+
device = "cuda:0"
|
| 158 |
+
|
| 159 |
+
tokenizer = AutoTokenizer.from_pretrained(model_id, trust_remote_code=True)
|
| 160 |
+
model = AutoModelForCausalLM.from_pretrained(
|
| 161 |
+
model_id,
|
| 162 |
+
trust_remote_code=True,
|
| 163 |
+
dtype=torch.bfloat16,
|
| 164 |
+
device_map={"": device},
|
| 165 |
+
).eval()
|
| 166 |
+
|
| 167 |
+
messages = [{"role": "user", "content": "13 乘以 7 等于多少?只回答数字。"}]
|
| 168 |
+
prompt = tokenizer.apply_chat_template(
|
| 169 |
+
messages,
|
| 170 |
+
tokenize=False,
|
| 171 |
+
add_generation_prompt=True,
|
| 172 |
+
enable_thinking=False,
|
| 173 |
+
)
|
| 174 |
+
inputs = tokenizer(prompt, return_tensors="pt").to(device)
|
| 175 |
+
|
| 176 |
+
with torch.inference_mode():
|
| 177 |
+
outputs = model.generate(
|
| 178 |
+
**inputs,
|
| 179 |
+
max_new_tokens=256,
|
| 180 |
+
do_sample=False,
|
| 181 |
+
use_cache=True,
|
| 182 |
+
)
|
| 183 |
+
|
| 184 |
+
response = tokenizer.decode(
|
| 185 |
+
outputs[0, inputs.input_ids.shape[1]:],
|
| 186 |
+
skip_special_tokens=True,
|
| 187 |
+
)
|
| 188 |
+
print(response)
|
| 189 |
+
```
|
| 190 |
+
|
| 191 |
+
示例采用贪心解码,最多生成 256 个新 token。将 `enable_thinking=True` 可开启思考模式,修改 `device` 可选择其他 GPU。
|
| 192 |
+
|
| 193 |
+
`trust_remote_code=True` 会从模型目录加载自定义模型实现。加载不可信来源的模型前,请先检查模型代码。此示例沿用此前已验证的单卡推理脚本,不包含图像输入和工具调用。
|
| 194 |
+
|
| 195 |
+
### 训练
|
| 196 |
+
|
| 197 |
+
模型训练使用 [OpenSenseNova/torchtitan](https://github.com/OpenSenseNova/torchtitan) 中的代码,训练示例请参见仓库中的 `example/train` 目录。
|
| 198 |
+
|
| 199 |
+
## 许可证与引用
|
| 200 |
+
|
| 201 |
+
**许可证:**发布权重与代码所适用的许可证待确定。<br>**引用:**将在发布时补充。
|
assets/loop-mhc-overview.jpg
ADDED

|
Git LFS Details
|
assets/loop9b-architecture.svg
ADDED
|
assets/loop9b-benchmark-results.png
ADDED

|
Git LFS Details
|
examples/chocolate/chocolate-horizontal.jpg
ADDED

|
Git LFS Details
|
examples/energy-analysis/energy-analysis.png
ADDED

|
Git LFS Details
|
examples/iceland/iceland-horizontal-v2.jpg
ADDED

|
Git LFS Details
|
examples/ink-journey/ink-journey-demo.mp4
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:4ba4cfa9128f28149210f54ed03f16a10c8bed112a4064ece6bef5adb932de9a
|
| 3 |
+
size 15477410
|
examples/ink-journey/ink-journey-preview.gif
ADDED

|
Git LFS Details
|
examples/moon-simulation/moon-simulation.gif
ADDED

|
Git LFS Details
|
examples/teacher-day/teacher-day-horizontal.jpg
ADDED

|
Git LFS Details
|