

Publish mini-Jev step 010626 interim checkpoint
Browse files- LICENSE +26 -0
- README.md +46 -248
- adapter/adapter_config.json +79 -0
- adapter/adapter_model.safetensors +3 -0
- assets/bfcl-by-candidates.svg +40 -0
- assets/bfcl-step-comparison.svg +24 -0
- assets/evaluation-summary.svg +32 -0
- config.json +13 -8
- decision_head.safetensors +3 -0
- inference.py +262 -0
- requirements.txt +6 -0
LICENSE
CHANGED
|
@@ -1,3 +1,4 @@
|
|
|
|
|
| 1 |
Apache License
|
| 2 |
Version 2.0, January 2004
|
| 3 |
http://www.apache.org/licenses/
|
|
@@ -174,3 +175,28 @@
|
|
| 174 |
of your accepting any such warranty or additional liability.
|
| 175 |
|
| 176 |
END OF TERMS AND CONDITIONS
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
|
| 2 |
Apache License
|
| 3 |
Version 2.0, January 2004
|
| 4 |
http://www.apache.org/licenses/
|
|
|
|
| 175 |
of your accepting any such warranty or additional liability.
|
| 176 |
|
| 177 |
END OF TERMS AND CONDITIONS
|
| 178 |
+
|
| 179 |
+
APPENDIX: How to apply the Apache License to your work.
|
| 180 |
+
|
| 181 |
+
To apply the Apache License to your work, attach the following
|
| 182 |
+
boilerplate notice, with the fields enclosed by brackets "[]"
|
| 183 |
+
replaced with your own identifying information. (Don't include
|
| 184 |
+
the brackets!) The text should be enclosed in the appropriate
|
| 185 |
+
comment syntax for the file format. We also recommend that a
|
| 186 |
+
file or class name and description of purpose be included on the
|
| 187 |
+
same "printed page" as the copyright notice for easier
|
| 188 |
+
identification within third-party archives.
|
| 189 |
+
|
| 190 |
+
Copyright [yyyy] [name of copyright owner]
|
| 191 |
+
|
| 192 |
+
Licensed under the Apache License, Version 2.0 (the "License");
|
| 193 |
+
you may not use this file except in compliance with the License.
|
| 194 |
+
You may obtain a copy of the License at
|
| 195 |
+
|
| 196 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 197 |
+
|
| 198 |
+
Unless required by applicable law or agreed to in writing, software
|
| 199 |
+
distributed under the License is distributed on an "AS IS" BASIS,
|
| 200 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 201 |
+
See the License for the specific language governing permissions and
|
| 202 |
+
limitations under the License.
|
README.md
CHANGED
|
@@ -1,277 +1,75 @@
|
|
| 1 |
---
|
| 2 |
license: apache-2.0
|
| 3 |
-
base_model:
|
| 4 |
-
- Qwen/Qwen3-0.6B
|
| 5 |
-
library_name: pytorch
|
| 6 |
tags:
|
| 7 |
-
- jev
|
| 8 |
- mini-jev
|
| 9 |
- decision-model
|
| 10 |
-
- agent
|
| 11 |
-
- agentic-ai
|
| 12 |
- tool-selection
|
| 13 |
-
- tool-
|
| 14 |
-
-
|
| 15 |
-
-
|
| 16 |
-
-
|
| 17 |
-
-
|
| 18 |
-
-
|
| 19 |
-
-
|
| 20 |
---
|
| 21 |
|
| 22 |
-
# mini-Jev
|
| 23 |
|
| 24 |
-
**
|
| 25 |
|
| 26 |
-
|
| 27 |
|
| 28 |
-
|
| 29 |
-
state + available candidates → probabilities + selected decision
|
| 30 |
-
```
|
| 31 |
|
| 32 |
-
|
| 33 |
-
-
|
| 34 |
-
-
|
| 35 |
-
-
|
| 36 |
-
|
| 37 |
-
-
|
| 38 |
|
| 39 |
-
|
| 40 |
|
| 41 |
-
--
|
| 42 |
-
|
| 43 |
-
## 1. What is mini-Jev?
|
| 44 |
-
|
| 45 |
-
AI agents frequently encounter situations where they must make small, structured decisions rather than generate free-form text. Common examples include:
|
| 46 |
-
|
| 47 |
-
- **Tool selection:** Deciding which tool or external integration to invoke.
|
| 48 |
-
- **Function routing:** Selecting the specific API or method to execute next.
|
| 49 |
-
- **Next-action prediction:** Choosing between continuing investigation, asking for clarification, or concluding.
|
| 50 |
-
- **Continue / finish decisions:** Deciding whether an assigned task is satisfied or requires another step.
|
| 51 |
-
- **Model routing:** Directing incoming tasks to appropriate candidate downstream models.
|
| 52 |
-
|
| 53 |
-
Rather than invoking a large generative language model for every routing and control decision, mini-Jev explores using a small, specialized decision model to evaluate candidate options directly over agent state.
|
| 54 |
-
|
| 55 |
-
*mini-Jev is an experimental baseline and is not intended for unmonitored production use.*
|
| 56 |
-
|
| 57 |
-
---
|
| 58 |
-
|
| 59 |
-
## 2. Current model
|
| 60 |
-
|
| 61 |
-
**Current release: Qwen3-0.6B-based mini-Jev v1**
|
| 62 |
-
|
| 63 |
-
### Architecture
|
| 64 |
-
|
| 65 |
-
```text
|
| 66 |
-
Frozen Qwen3-0.6B → candidate representation → lightweight decision head → grouped softmax
|
| 67 |
-
```
|
| 68 |
-
|
| 69 |
-
1. **Backbone:** The base model is [`Qwen/Qwen3-0.6B`](https://huggingface.co/Qwen/Qwen3-0.6B), which remains completely frozen. The weights in this repository contain only the trained decision head; the Qwen backbone is downloaded separately by the loader.
|
| 70 |
-
2. **Representation pooling:** State text and candidate descriptions are passed through the model. Only candidate-description tokens are mean-pooled. Candidate IDs, prompt formatting headers, state tokens, and padding tokens are excluded from the pooling mask.
|
| 71 |
-
3. **Decision head:** A lightweight two-layer MLP:
|
| 72 |
-
- `Linear(1024, 256)`
|
| 73 |
-
- `GELU`
|
| 74 |
-
- `Linear(256, 1)`
|
| 75 |
-
- Total head parameters: **262,657** (~1.1 MB).
|
| 76 |
-
4. **Scoring:** The resulting scalar logits are normalized across candidate options using a grouped softmax to yield probabilities, a selected candidate, confidence, and decision margin.
|
| 77 |
-
|
| 78 |
-
---
|
| 79 |
-
|
| 80 |
-
## 3. Quick start
|
| 81 |
|
| 82 |
-
|
| 83 |
|
| 84 |
-
|
| 85 |
-
pip install torch transformers safetensors huggingface_hub
|
| 86 |
-
```
|
| 87 |
|
| 88 |
-
|
| 89 |
|
| 90 |
-
|
| 91 |
-
hf download samatv256/mini-Jev odm_mini.py --local-dir .
|
| 92 |
-
```
|
| 93 |
|
| 94 |
-
##
|
| 95 |
|
| 96 |
-
|
| 97 |
-
from odm_mini import ODMMiniModel
|
| 98 |
|
| 99 |
-
|
| 100 |
|
| 101 |
-
|
| 102 |
-
|
| 103 |
-
|
| 104 |
-
|
| 105 |
-
|
| 106 |
-
|
| 107 |
-
|
| 108 |
-
|
| 109 |
-
"id": "
|
| 110 |
-
|
| 111 |
-
|
| 112 |
-
|
| 113 |
-
)
|
| 114 |
-
|
| 115 |
-
print("Selected:", choice.selected)
|
| 116 |
-
print("Probabilities:", choice.probabilities)
|
| 117 |
-
```
|
| 118 |
-
|
| 119 |
-
### Full snapshot download and usage
|
| 120 |
-
|
| 121 |
-
You can also download all repository files to a local directory before loading:
|
| 122 |
-
|
| 123 |
-
```python
|
| 124 |
-
import sys
|
| 125 |
-
from pathlib import Path
|
| 126 |
-
from huggingface_hub import snapshot_download
|
| 127 |
-
|
| 128 |
-
release_dir = Path(
|
| 129 |
-
snapshot_download(
|
| 130 |
-
repo_id="samatv256/mini-Jev",
|
| 131 |
-
allow_patterns=[
|
| 132 |
-
"README.md",
|
| 133 |
-
"model.safetensors",
|
| 134 |
-
"config.json",
|
| 135 |
-
"odm_mini.py",
|
| 136 |
-
"LICENSE",
|
| 137 |
],
|
| 138 |
)
|
| 139 |
-
)
|
| 140 |
-
|
| 141 |
-
|
| 142 |
-
from odm_mini import ODMMiniModel
|
| 143 |
-
|
| 144 |
-
model = ODMMiniModel.from_pretrained(release_dir)
|
| 145 |
-
|
| 146 |
-
state = {
|
| 147 |
-
"user_request": "Find the current weather in Boston.",
|
| 148 |
-
"available_context": "The user has not provided weather data.",
|
| 149 |
-
}
|
| 150 |
-
candidates = [
|
| 151 |
-
{
|
| 152 |
-
"id": "weather.lookup",
|
| 153 |
-
"description": "Look up current weather for a specified city.",
|
| 154 |
-
},
|
| 155 |
-
{
|
| 156 |
-
"id": "calendar.list",
|
| 157 |
-
"description": "List upcoming calendar events for the user.",
|
| 158 |
-
},
|
| 159 |
-
{
|
| 160 |
-
"id": "control.finish",
|
| 161 |
-
"description": "Finish because the request has already been completed.",
|
| 162 |
-
},
|
| 163 |
-
]
|
| 164 |
-
|
| 165 |
-
choice = model.predict_choice(state=state, candidates=candidates)
|
| 166 |
-
print("Selected candidate:", choice.selected)
|
| 167 |
-
print("Probabilities:", choice.probabilities)
|
| 168 |
-
print("Confidence:", choice.confidence)
|
| 169 |
-
print("Decision margin:", choice.decision_margin)
|
| 170 |
-
print("Latency (ms):", choice.latency_ms)
|
| 171 |
-
```
|
| 172 |
-
|
| 173 |
-
`ODMMiniModel.from_pretrained()` accepts either the Hugging Face repo ID or a local directory path. CUDA runs in BF16 by default; CPU runs in FP32.
|
| 174 |
-
|
| 175 |
-
---
|
| 176 |
-
|
| 177 |
-
## 4. Example use cases
|
| 178 |
-
|
| 179 |
-
mini-Jev can be used for several structured agent-control patterns:
|
| 180 |
-
|
| 181 |
-
- **Tool selection:** Choosing the right tool from a list of available integrations.
|
| 182 |
-
- **Function routing:** Determining which endpoint or handler to call.
|
| 183 |
-
- **Next-action prediction:** Selecting intermediate steps in a reasoning or execution plan.
|
| 184 |
-
- **Agent-control research:** Investigating small-footprint models for local agent decision-making.
|
| 185 |
-
- **Model-routing experiments:** Evaluating routing policies between different candidate models. *(Note: Model routing is a conceptual application of the candidate-selection interface, not a validated production routing capability.)*
|
| 186 |
-
|
| 187 |
-
### Conceptual example
|
| 188 |
|
| 189 |
-
|
| 190 |
-
State:
|
| 191 |
-
User wants to find the weather in Boston.
|
| 192 |
|
| 193 |
-
|
| 194 |
-
- web_search
|
| 195 |
-
- weather_tool
|
| 196 |
-
- calculator
|
| 197 |
-
- finish
|
| 198 |
-
|
| 199 |
-
Decision:
|
| 200 |
-
weather_tool
|
| 201 |
-
```
|
| 202 |
-
|
| 203 |
-
---
|
| 204 |
-
|
| 205 |
-
## 5. Jev Decisions v1
|
| 206 |
-
|
| 207 |
-
Researchers interested in training and evaluating decision models can explore the [Jev Decisions v1 dataset](https://huggingface.co/datasets/samatv256/jev-decisions-v1).
|
| 208 |
-
|
| 209 |
-
- **Dataset card:** [https://huggingface.co/datasets/samatv256/jev-decisions-v1](https://huggingface.co/datasets/samatv256/jev-decisions-v1)
|
| 210 |
-
- **Description:** A public dataset containing nearly 12 million canonical agent-decision records (over 6.2M choice-eligible decisions across 1.06M task trajectories) with explicit candidate sets, chosen actions, and eligibility flags.
|
| 211 |
-
|
| 212 |
-
> **Important:** The current mini-Jev Qwen3-0.6B baseline was **NOT trained on Jev Decisions v1**. It is provided as an open project resource for community research.
|
| 213 |
-
|
| 214 |
-
---
|
| 215 |
-
|
| 216 |
-
## 6. Current verified results
|
| 217 |
-
|
| 218 |
-
The results below reflect the public Qwen3-0.6B baseline checkpoint:
|
| 219 |
-
|
| 220 |
-
### Training configuration
|
| 221 |
-
|
| 222 |
-
- **Training data:** 50,000 synthetic decision examples
|
| 223 |
-
- **Backbone:** Frozen `Qwen/Qwen3-0.6B`
|
| 224 |
-
- **Trained components:** DecisionHead weights only (grouped cross-entropy objective)
|
| 225 |
-
- **Checkpoint:** Seed 41, epoch 4
|
| 226 |
-
- **Temperature:** Fixed at 1.0; maximum softmax output is reported as confidence.
|
| 227 |
-
|
| 228 |
-
### Synthetic held-out evaluation
|
| 229 |
-
|
| 230 |
-
| Metric | Result |
|
| 231 |
-
|---|---:|
|
| 232 |
-
| Semantic Choice accuracy | **72.97%** |
|
| 233 |
-
| Stress Choice accuracy | **67.64%** |
|
| 234 |
-
| Counterfactual pair consistency | **67.12%** |
|
| 235 |
-
|
| 236 |
-
- **Latency measurements:** On an NVIDIA GH200 using BF16 backbone inference and a shared-prefix KV-cache path, total latency was approximately **76–85 ms** for contexts of 256–1,024 state tokens across 3–16 candidates (measured range: 76.11–82.36 ms). Candidate representation extraction reached 831.3 candidates/second at batch size 512.
|
| 237 |
-
|
| 238 |
-
### Real shadow-agent evaluation
|
| 239 |
-
|
| 240 |
-
In an offline evaluation on real agent executions across **75 multi-step trajectories and 243 decisions**, the baseline achieved:
|
| 241 |
-
|
| 242 |
-
- **Action accuracy:** **27.98%**
|
| 243 |
-
- **Controller agreement:** **26.34%**
|
| 244 |
-
|
| 245 |
-
These metrics are reported to transparently show the significant transfer gap between synthetic single-step decisions and dynamic, multi-step agent trajectories.
|
| 246 |
-
|
| 247 |
-
---
|
| 248 |
-
|
| 249 |
-
## 7. Limitations
|
| 250 |
-
|
| 251 |
-
> **mini-Jev v1 is an experimental research prototype and is not ready for unmonitored production agent control.**
|
| 252 |
-
|
| 253 |
-
- **Limited real-agent transfer:** While performance on synthetic single-step benchmarks is moderate (~73%), accuracy drops substantially (~28%) in real multi-step agent environments.
|
| 254 |
-
- **Premature completion:** The model exhibits a known failure mode of high-confidence premature `finish` decisions. After making partial progress, it frequently over-indexes on successful intermediate receipts and chooses `control.finish` before completing remaining steps.
|
| 255 |
-
- **Uncalibrated confidence:** Grouped softmax probabilities indicate relative preference among the provided candidates, not calibrated real-world uncertainty.
|
| 256 |
-
- **No autonomous control:** Do not use this baseline as the sole decision-maker for consequential actions or mission-critical workflows without a human or supervising controller in the loop.
|
| 257 |
-
|
| 258 |
-
---
|
| 259 |
-
|
| 260 |
-
## 8. Public project links
|
| 261 |
-
|
| 262 |
-
- **Dataset:** [Jev Decisions v1](https://huggingface.co/datasets/samatv256/jev-decisions-v1)
|
| 263 |
-
- **Collection:** [mini-Jev Hugging Face Collection](https://huggingface.co/collections/samatv256/mini-jev-small-decision-models-for-ai-agents-6ab3e559bed2124120973013)
|
| 264 |
-
|
| 265 |
-
Future work will continue exploring improved decision models and training on larger real agent/tool-use datasets.
|
| 266 |
-
|
| 267 |
-
---
|
| 268 |
|
| 269 |
-
|
| 270 |
|
| 271 |
-
|
| 272 |
-
- `config.json` — Architecture specification and backbone reference
|
| 273 |
-
- `odm_mini.py` — Inference loader module
|
| 274 |
-
- `README.md` — Model card and usage documentation
|
| 275 |
-
- `LICENSE` — Apache License 2.0
|
| 276 |
|
| 277 |
-
|
|
|
|
| 1 |
---
|
| 2 |
license: apache-2.0
|
| 3 |
+
base_model: Qwen/Qwen3-0.6B
|
|
|
|
|
|
|
| 4 |
tags:
|
|
|
|
| 5 |
- mini-jev
|
| 6 |
- decision-model
|
|
|
|
|
|
|
| 7 |
- tool-selection
|
| 8 |
+
- tool-use
|
| 9 |
+
- agents
|
| 10 |
+
- action-selection
|
| 11 |
+
- decision-making
|
| 12 |
+
- finite-choice
|
| 13 |
+
- qwen3
|
| 14 |
+
- peft
|
| 15 |
---
|
| 16 |
|
| 17 |
+
# mini-Jev Qwen3-0.6B - step 10,626
|
| 18 |
|
| 19 |
+
mini-Jev is a **0.6B agentic decision model specialized for finite-choice tool and action selection**. Give it a state, a question, and candidate actions; it returns a probability for each candidate. It uses a Qwen3-0.6B backbone with an adapter and a compact decision head. Candidate scoring is permutation equivariant, and the model returns finite-choice probabilities rather than generated text or tool arguments.
|
| 20 |
|
| 21 |
+
This is an **early 10,626-update checkpoint**. Training is planned through 50,000 updates; more training and broader decision supervision are coming. This release candidate is not the final checkpoint.
|
| 22 |
|
| 23 |
+
## Measured results
|
|
|
|
|
|
|
| 24 |
|
| 25 |
+
| Evaluation | Result | Scope |
|
| 26 |
+
|---|---:|---|
|
| 27 |
+
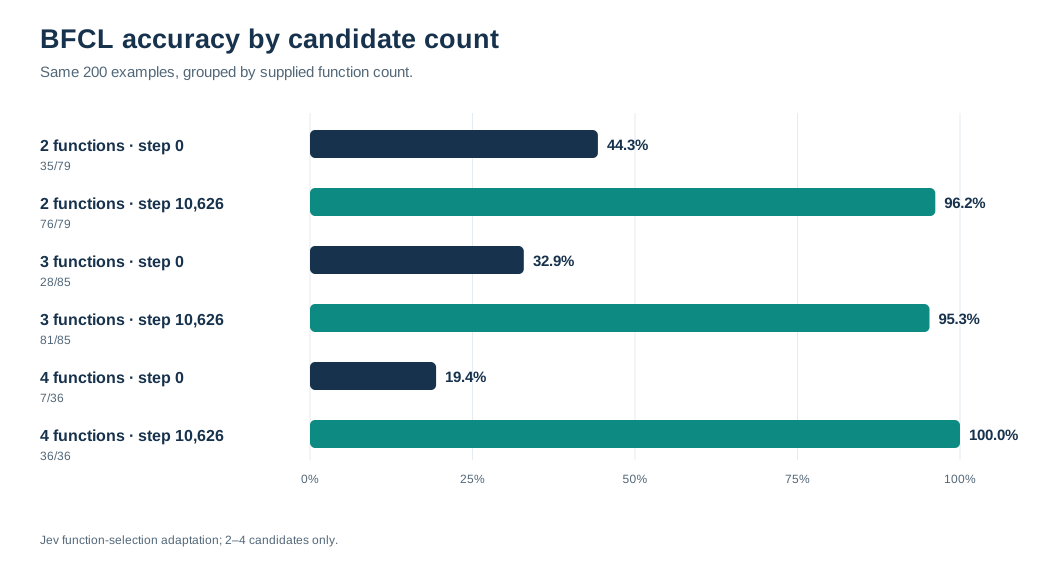
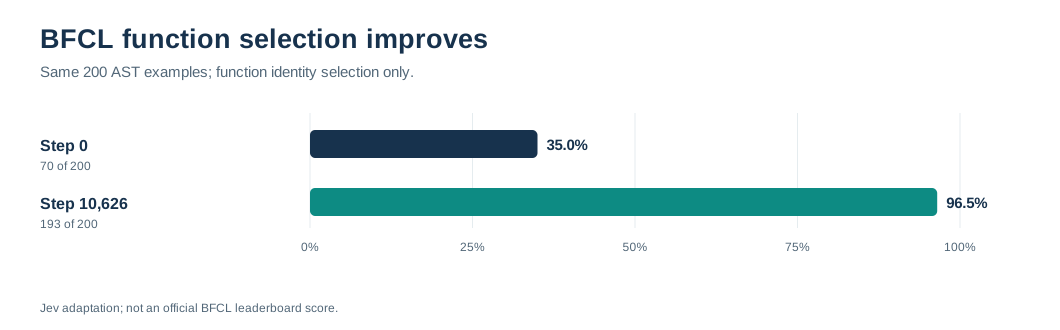
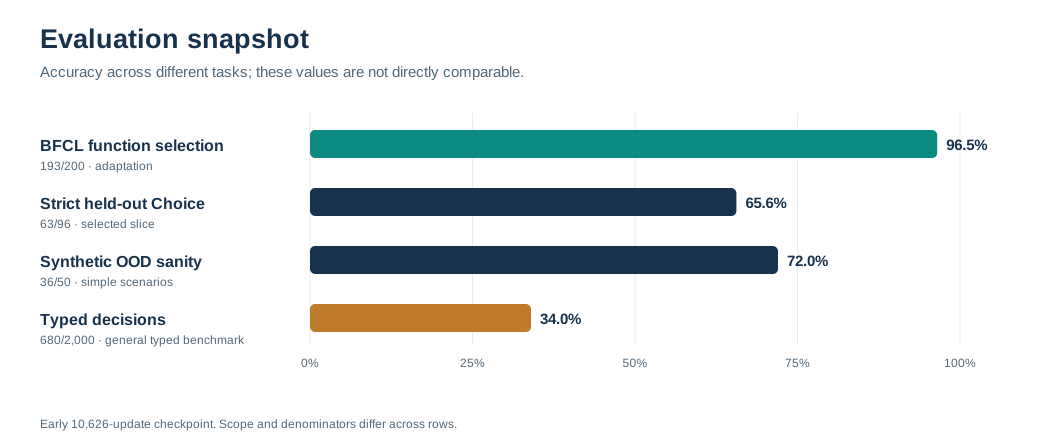
| BFCL V1 Multiple Function - Jev function-selection adaptation | **96.5% (193/200)** | Selects the supplied function identity from 2-4 definitions. **Not an official BFCL leaderboard score**; does not generate arguments or execute calls. |
|
| 28 |
+
| Strict held-out Choice | **65.6% (63/96)** | A selected, bucket-balanced validation slice, not the full validation split. |
|
| 29 |
+
| Bespoke OOD typed decisions | **72.0% (36/50)** | Small synthetic sanity check with straightforward distractors; not a public benchmark. |
|
| 30 |
+
| LocalLLaMA/typed-decisions, full test set | **34.0% (680/2,000)** | Choice 27.0%, Noul 52.2%, Score 25.6%. General typed decisions remain a weakness. |
|
| 31 |
|
| 32 |
+

|
| 33 |
|
| 34 |
+

|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 35 |
|
| 36 |
+

|
| 37 |
|
| 38 |
+
These evaluations have different datasets and denominators; their percentages are not directly comparable. The BFCL adaptation uses the [BFCL V1 Multiple Function AST examples](https://github.com/EnlightenedAI/BFCL/blob/main/berkeley-function-call-leaderboard/bfcl_eval/data/README.md). The typed-decision result uses the [LocalLLaMA/typed-decisions test split](https://huggingface.co/datasets/LocalLLaMA/typed-decisions).
|
|
|
|
|
|
|
| 39 |
|
| 40 |
+
## Intended use and limits
|
| 41 |
|
| 42 |
+
The current strength is **finite-choice tool and action selection** from state and supplied candidates. The model is less reliable for general typed decisions and for large candidate sets. It is not a general probability or classification model, and its probabilities have not been calibrated for arbitrary domains. A selected 17+ candidate held-out slice scored 4/17, so large sets need particular care.
|
|
|
|
|
|
|
| 43 |
|
| 44 |
+
## Use
|
| 45 |
|
| 46 |
+
A CUDA GPU with BF16 support is required for this 4-bit package. Install the tested dependencies from requirements.txt. The [Qwen3-0.6B base model](https://huggingface.co/Qwen/Qwen3-0.6B) is downloaded separately on first load; this repository contains only the adapter and decision head.
|
|
|
|
| 47 |
|
| 48 |
+
from inference import MiniJev
|
| 49 |
|
| 50 |
+
model = MiniJev.load(".")
|
| 51 |
+
result = model.predict(
|
| 52 |
+
state={"user_goal": "Find tomorrow's weather forecast for Paris."},
|
| 53 |
+
question="Given the current state and available options,\nwhich option should be selected?",
|
| 54 |
+
question_type="choice",
|
| 55 |
+
answer_options=[
|
| 56 |
+
{"id": "weather", "type": "tool", "label": "get_weather_forecast",
|
| 57 |
+
"description": "Look up the weather forecast for a place and date."},
|
| 58 |
+
{"id": "invoice", "type": "tool", "label": "calculate_invoice_total",
|
| 59 |
+
"description": "Add amounts on an invoice."},
|
| 60 |
+
{"id": "email", "type": "tool", "label": "send_email",
|
| 61 |
+
"description": "Send an email message."},
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 62 |
],
|
| 63 |
)
|
| 64 |
+
print(result["selected_id"])
|
| 65 |
+
print(result["options"])
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 66 |
|
| 67 |
+
Option IDs are bookkeeping and are excluded from model text. The model scores each supplied option and normalizes probabilities over the finite set. Input branches are limited to 8,192 tokens.
|
|
|
|
|
|
|
| 68 |
|
| 69 |
+
## Data attribution
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 70 |
|
| 71 |
+
Decision supervision for this checkpoint draws in part on [Jev Decisions v1](https://huggingface.co/datasets/samatv256/jev-decisions-v1), a public dataset released under CC BY 4.0. Its public upstream datasets carry their own attribution and licensing terms; see the [dataset card](https://huggingface.co/datasets/samatv256/jev-decisions-v1) and [upstream license notes](https://huggingface.co/datasets/samatv256/jev-decisions-v1/blob/main/SOURCE_LICENSES.md).
|
| 72 |
|
| 73 |
+
## License
|
|
|
|
|
|
|
|
|
|
|
|
|
| 74 |
|
| 75 |
+
Apache-2.0. The Qwen3-0.6B base model is separately licensed by Qwen under Apache-2.0. See LICENSE and the [base model card](https://huggingface.co/Qwen/Qwen3-0.6B).
|
adapter/adapter_config.json
ADDED
|
@@ -0,0 +1,79 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"alora_invocation_tokens": null,
|
| 3 |
+
"alpha_pattern": {},
|
| 4 |
+
"arrow_config": null,
|
| 5 |
+
"auto_mapping": {
|
| 6 |
+
"base_model_class": "Qwen3Model",
|
| 7 |
+
"parent_library": "transformers.models.qwen3.modeling_qwen3"
|
| 8 |
+
},
|
| 9 |
+
"base_model_name_or_path": "Qwen/Qwen3-0.6B",
|
| 10 |
+
"bias": "none",
|
| 11 |
+
"corda_config": null,
|
| 12 |
+
"ensure_weight_tying": false,
|
| 13 |
+
"eva_config": null,
|
| 14 |
+
"exclude_modules": null,
|
| 15 |
+
"fan_in_fan_out": false,
|
| 16 |
+
"inference_mode": true,
|
| 17 |
+
"init_lora_weights": true,
|
| 18 |
+
"kasa_config": null,
|
| 19 |
+
"layer_replication": null,
|
| 20 |
+
"layers_pattern": null,
|
| 21 |
+
"layers_to_transform": null,
|
| 22 |
+
"loftq_config": {},
|
| 23 |
+
"lora_alpha": 32,
|
| 24 |
+
"lora_bias": false,
|
| 25 |
+
"lora_dropout": 0.0,
|
| 26 |
+
"lora_ga_config": null,
|
| 27 |
+
"megatron_config": null,
|
| 28 |
+
"megatron_core": "megatron.core",
|
| 29 |
+
"modules_to_save": null,
|
| 30 |
+
"monteclora_config": null,
|
| 31 |
+
"peft_type": "LORA",
|
| 32 |
+
"peft_version": "0.21.0",
|
| 33 |
+
"qalora_group_size": 16,
|
| 34 |
+
"r": 16,
|
| 35 |
+
"rank_pattern": {},
|
| 36 |
+
"revision": null,
|
| 37 |
+
"target_modules": [
|
| 38 |
+
"layers.22.self_attn.v_proj",
|
| 39 |
+
"layers.21.self_attn.v_proj",
|
| 40 |
+
"layers.27.self_attn.v_proj",
|
| 41 |
+
"layers.22.self_attn.k_proj",
|
| 42 |
+
"layers.27.self_attn.o_proj",
|
| 43 |
+
"layers.20.self_attn.v_proj",
|
| 44 |
+
"layers.21.self_attn.o_proj",
|
| 45 |
+
"layers.21.self_attn.q_proj",
|
| 46 |
+
"layers.24.self_attn.v_proj",
|
| 47 |
+
"layers.25.self_attn.o_proj",
|
| 48 |
+
"layers.26.self_attn.v_proj",
|
| 49 |
+
"layers.25.self_attn.q_proj",
|
| 50 |
+
"layers.27.self_attn.q_proj",
|
| 51 |
+
"layers.24.self_attn.q_proj",
|
| 52 |
+
"layers.27.self_attn.k_proj",
|
| 53 |
+
"layers.26.self_attn.q_proj",
|
| 54 |
+
"layers.26.self_attn.k_proj",
|
| 55 |
+
"layers.23.self_attn.q_proj",
|
| 56 |
+
"layers.24.self_attn.o_proj",
|
| 57 |
+
"layers.25.self_attn.k_proj",
|
| 58 |
+
"layers.23.self_attn.v_proj",
|
| 59 |
+
"layers.22.self_attn.o_proj",
|
| 60 |
+
"layers.20.self_attn.o_proj",
|
| 61 |
+
"layers.20.self_attn.k_proj",
|
| 62 |
+
"layers.23.self_attn.o_proj",
|
| 63 |
+
"layers.26.self_attn.o_proj",
|
| 64 |
+
"layers.25.self_attn.v_proj",
|
| 65 |
+
"layers.21.self_attn.k_proj",
|
| 66 |
+
"layers.22.self_attn.q_proj",
|
| 67 |
+
"layers.20.self_attn.q_proj",
|
| 68 |
+
"layers.23.self_attn.k_proj",
|
| 69 |
+
"layers.24.self_attn.k_proj"
|
| 70 |
+
],
|
| 71 |
+
"target_parameters": null,
|
| 72 |
+
"task_type": null,
|
| 73 |
+
"trainable_token_indices": null,
|
| 74 |
+
"use_bdlora": null,
|
| 75 |
+
"use_dora": false,
|
| 76 |
+
"use_qalora": false,
|
| 77 |
+
"use_rslora": false,
|
| 78 |
+
"velora_config": null
|
| 79 |
+
}
|
adapter/adapter_model.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:765e987436517f18ef902641a197c719a415292d082615ca891e38590fbffeda
|
| 3 |
+
size 5251016
|
assets/bfcl-by-candidates.svg
ADDED
|
assets/bfcl-step-comparison.svg
ADDED
|
assets/evaluation-summary.svg
ADDED
|
config.json
CHANGED
|
@@ -1,11 +1,16 @@
|
|
| 1 |
{
|
| 2 |
-
"architectures": ["ODMMiniModel"],
|
| 3 |
-
"model_type": "odm_mini",
|
| 4 |
"base_model": "Qwen/Qwen3-0.6B",
|
| 5 |
-
"
|
| 6 |
-
"
|
| 7 |
-
"
|
| 8 |
-
"
|
| 9 |
-
"
|
| 10 |
-
"
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 11 |
}
|
|
|
|
| 1 |
{
|
|
|
|
|
|
|
| 2 |
"base_model": "Qwen/Qwen3-0.6B",
|
| 3 |
+
"base_revision": "c1899de289a04d12100db370d81485cdf75e47ca",
|
| 4 |
+
"max_tokens": 8192,
|
| 5 |
+
"pooler": "mean",
|
| 6 |
+
"projection_dim": 256,
|
| 7 |
+
"set_layers": 2,
|
| 8 |
+
"set_heads": 4,
|
| 9 |
+
"quantization": {
|
| 10 |
+
"format": "nf4",
|
| 11 |
+
"double_quantization": true,
|
| 12 |
+
"compute_dtype": "bfloat16"
|
| 13 |
+
},
|
| 14 |
+
"adapter_dir": "adapter",
|
| 15 |
+
"head_file": "decision_head.safetensors"
|
| 16 |
}
|
decision_head.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:f06d990297b23ffabc7a0d5eba3670830c337b742f8e3a30fe3907783e0bac88
|
| 3 |
+
size 7631364
|
inference.py
ADDED
|
@@ -0,0 +1,262 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Public, inference-only loader for the mini-Jev step 10,626 adapter and decision head."""
|
| 2 |
+
from __future__ import annotations
|
| 3 |
+
|
| 4 |
+
import json
|
| 5 |
+
from collections.abc import Mapping, Sequence
|
| 6 |
+
from pathlib import Path
|
| 7 |
+
from typing import Any
|
| 8 |
+
|
| 9 |
+
import torch
|
| 10 |
+
from peft import PeftModel, prepare_model_for_kbit_training
|
| 11 |
+
from safetensors.torch import load_file
|
| 12 |
+
from torch import nn
|
| 13 |
+
from transformers import AutoModel, AutoTokenizer, BitsAndBytesConfig
|
| 14 |
+
|
| 15 |
+
|
| 16 |
+
def _text(value: Any) -> str:
|
| 17 |
+
if value is None:
|
| 18 |
+
return ""
|
| 19 |
+
if isinstance(value, str):
|
| 20 |
+
try:
|
| 21 |
+
value = json.loads(value)
|
| 22 |
+
except (ValueError, TypeError):
|
| 23 |
+
return value.strip()
|
| 24 |
+
if isinstance(value, (dict, list)):
|
| 25 |
+
return json.dumps(value, ensure_ascii=False, sort_keys=True, separators=(",", ":"))
|
| 26 |
+
return str(value)
|
| 27 |
+
|
| 28 |
+
|
| 29 |
+
def _section(name: str, content: str) -> str:
|
| 30 |
+
return f"<{name}>\n{content}\n</{name}>\n"
|
| 31 |
+
|
| 32 |
+
|
| 33 |
+
def _option_text(option: Mapping[str, Any]) -> str:
|
| 34 |
+
label = option.get("label") or option.get("name")
|
| 35 |
+
if not label:
|
| 36 |
+
raise ValueError("each answer option needs a nonempty label")
|
| 37 |
+
fields = (
|
| 38 |
+
("type", option.get("type") or option.get("option_type") or "action"),
|
| 39 |
+
("label", label),
|
| 40 |
+
("description", option.get("description")),
|
| 41 |
+
("schema", option.get("schema") or option.get("parameters_json") or option.get("parameters")),
|
| 42 |
+
)
|
| 43 |
+
lines = [f"{name}: {_text(value)}" for name, value in fields if value is not None and _text(value)]
|
| 44 |
+
return _section("ANSWER_OPTION", "\n".join(lines))
|
| 45 |
+
|
| 46 |
+
|
| 47 |
+
def _encode(tokenizer, value: str) -> list[int]:
|
| 48 |
+
return list(tokenizer.encode(value, add_special_tokens=False))
|
| 49 |
+
|
| 50 |
+
|
| 51 |
+
def encode_branch(
|
| 52 |
+
tokenizer,
|
| 53 |
+
state: Mapping[str, Any] | str,
|
| 54 |
+
question: str,
|
| 55 |
+
question_type: str,
|
| 56 |
+
option: Mapping[str, Any],
|
| 57 |
+
max_tokens: int = 8192,
|
| 58 |
+
) -> tuple[list[int], list[bool]]:
|
| 59 |
+
"""Serialize one option branch; preserve the question and option within the 8K budget."""
|
| 60 |
+
if not 1 <= max_tokens <= 8192:
|
| 61 |
+
raise ValueError("max_tokens must be 1..8192")
|
| 62 |
+
if not question or not question_type:
|
| 63 |
+
raise ValueError("question and question_type must be nonempty")
|
| 64 |
+
if isinstance(state, str):
|
| 65 |
+
state = {"summary": state}
|
| 66 |
+
if not isinstance(state, Mapping):
|
| 67 |
+
raise TypeError("state must be a string or a mapping")
|
| 68 |
+
history = state.get("history") or []
|
| 69 |
+
if not isinstance(history, Sequence) or isinstance(history, (str, bytes)):
|
| 70 |
+
raise TypeError("state.history must be a sequence")
|
| 71 |
+
state_open = _encode(tokenizer, "<STATE>\n")
|
| 72 |
+
system = _encode(tokenizer, _section("SYSTEM", _text(state.get("system"))))
|
| 73 |
+
goal = _encode(tokenizer, _section("USER_GOAL", _text(state.get("user_goal"))))
|
| 74 |
+
summary_open = _encode(tokenizer, "<SUMMARY>\n")
|
| 75 |
+
summary_content = _encode(tokenizer, _text(state.get("summary")))
|
| 76 |
+
summary_close = _encode(tokenizer, "\n</SUMMARY>\n")
|
| 77 |
+
environment_open = _encode(tokenizer, "<ENVIRONMENT>\n")
|
| 78 |
+
environment_content = _encode(tokenizer, _text(state.get("environment")))
|
| 79 |
+
environment_close = _encode(tokenizer, "\n</ENVIRONMENT>\n")
|
| 80 |
+
open_history = _encode(tokenizer, "<HISTORY>\n")
|
| 81 |
+
close_history = _encode(tokenizer, "</HISTORY>\n")
|
| 82 |
+
state_close = _encode(tokenizer, "</STATE>\n")
|
| 83 |
+
question_ids = _encode(tokenizer, _section("QUESTION", question))
|
| 84 |
+
type_ids = _encode(tokenizer, _section("QUESTION_TYPE", question_type))
|
| 85 |
+
history_ids = []
|
| 86 |
+
for event in history:
|
| 87 |
+
if not isinstance(event, Mapping):
|
| 88 |
+
raise TypeError("history events must be mappings")
|
| 89 |
+
role = str(event.get("role") or "unknown")
|
| 90 |
+
label = "OBSERVATION" if role.lower() in {"tool", "observation", "environment"} else "ACTION"
|
| 91 |
+
content = _text(event.get("content"))
|
| 92 |
+
history_ids.append(_encode(tokenizer, _section(label, f"role: {role}\n{content}")))
|
| 93 |
+
option_ids = _encode(tokenizer, _option_text(option))
|
| 94 |
+
fixed = sum(map(len, (
|
| 95 |
+
state_open, system, goal, summary_open, summary_close, environment_open,
|
| 96 |
+
environment_close, open_history, close_history, state_close, question_ids,
|
| 97 |
+
type_ids, option_ids,
|
| 98 |
+
)))
|
| 99 |
+
if fixed > max_tokens:
|
| 100 |
+
raise ValueError("protected state, question, and option exceed 8192 tokens")
|
| 101 |
+
budget = max_tokens - fixed
|
| 102 |
+
summary_reserve = min(len(summary_content), max(0, budget // 3))
|
| 103 |
+
budget -= summary_reserve
|
| 104 |
+
environment_reserve = min(len(environment_content), max(0, budget // 3))
|
| 105 |
+
budget -= environment_reserve
|
| 106 |
+
selected = []
|
| 107 |
+
for event, item in reversed(list(zip(history, history_ids, strict=True))):
|
| 108 |
+
if len(item) <= budget:
|
| 109 |
+
selected.append(item)
|
| 110 |
+
budget -= len(item)
|
| 111 |
+
elif not selected and budget > 0:
|
| 112 |
+
role = str(event.get("role") or "unknown")
|
| 113 |
+
label = "OBSERVATION" if role.lower() in {"tool", "observation", "environment"} else "ACTION"
|
| 114 |
+
start = _encode(tokenizer, f"<{label}>\nrole: {role}\n")
|
| 115 |
+
end = _encode(tokenizer, f"\n</{label}>\n")
|
| 116 |
+
available = budget - len(start) - len(end)
|
| 117 |
+
if available > 0:
|
| 118 |
+
payload = _encode(tokenizer, _text(event.get("content")))
|
| 119 |
+
selected.append(start + payload[-available:] + end)
|
| 120 |
+
budget -= len(selected[-1])
|
| 121 |
+
selected.reverse()
|
| 122 |
+
extra_summary = min(budget, len(summary_content) - summary_reserve)
|
| 123 |
+
kept_summary = summary_content[:summary_reserve + extra_summary]
|
| 124 |
+
budget -= extra_summary
|
| 125 |
+
kept_environment = environment_content[:environment_reserve + budget]
|
| 126 |
+
prefix = (
|
| 127 |
+
state_open + system + goal + summary_open + kept_summary + summary_close
|
| 128 |
+
+ environment_open + kept_environment + environment_close + open_history
|
| 129 |
+
+ [token for item in selected for token in item] + close_history + state_close
|
| 130 |
+
+ question_ids + type_ids
|
| 131 |
+
)
|
| 132 |
+
ids = prefix + option_ids
|
| 133 |
+
if len(ids) > max_tokens:
|
| 134 |
+
raise AssertionError("serialization exceeded max_tokens")
|
| 135 |
+
return ids, [False] * len(prefix) + [True] * len(option_ids)
|
| 136 |
+
|
| 137 |
+
|
| 138 |
+
class _SetBlock(nn.Module):
|
| 139 |
+
def __init__(self, width: int, heads: int):
|
| 140 |
+
super().__init__()
|
| 141 |
+
self.norm1 = nn.RMSNorm(width)
|
| 142 |
+
self.attn = nn.MultiheadAttention(width, heads, dropout=0.0, batch_first=True)
|
| 143 |
+
self.norm2 = nn.RMSNorm(width)
|
| 144 |
+
self.ff = nn.Sequential(nn.Linear(width, 4 * width), nn.SiLU(),
|
| 145 |
+
nn.Dropout(0.0), nn.Linear(4 * width, width))
|
| 146 |
+
|
| 147 |
+
def forward(self, x: torch.Tensor, valid: torch.Tensor) -> torch.Tensor:
|
| 148 |
+
normed = self.norm1(x)
|
| 149 |
+
attended, _ = self.attn(normed, normed, normed,
|
| 150 |
+
key_padding_mask=~valid, need_weights=False)
|
| 151 |
+
x = x + attended
|
| 152 |
+
x = x + self.ff(self.norm2(x))
|
| 153 |
+
return x.masked_fill(~valid.unsqueeze(-1), 0)
|
| 154 |
+
|
| 155 |
+
|
| 156 |
+
class _SetHead(nn.Module):
|
| 157 |
+
def __init__(self, width: int, layers: int, heads: int):
|
| 158 |
+
super().__init__()
|
| 159 |
+
self.input = nn.Linear(width, width)
|
| 160 |
+
self.blocks = nn.ModuleList([_SetBlock(width, heads) for _ in range(layers)])
|
| 161 |
+
self.output = nn.Sequential(nn.RMSNorm(width), nn.Linear(width, 1))
|
| 162 |
+
|
| 163 |
+
def forward(self, vectors: torch.Tensor, valid: torch.Tensor) -> torch.Tensor:
|
| 164 |
+
x = self.input(vectors.float()).masked_fill(~valid.unsqueeze(-1), 0)
|
| 165 |
+
for block in self.blocks:
|
| 166 |
+
x = block(x, valid)
|
| 167 |
+
return self.output(x).squeeze(-1).masked_fill(~valid, -torch.inf)
|
| 168 |
+
|
| 169 |
+
|
| 170 |
+
class MiniJev:
|
| 171 |
+
"""Score state + question + finite options, returning a probability per option."""
|
| 172 |
+
|
| 173 |
+
def __init__(self, release_dir: str | Path, device: str = "cuda"):
|
| 174 |
+
if not device.startswith("cuda") or not torch.cuda.is_available():
|
| 175 |
+
raise RuntimeError("this 4-bit BF16 release requires a CUDA GPU")
|
| 176 |
+
root = Path(release_dir)
|
| 177 |
+
config = json.loads((root / "config.json").read_text(encoding="utf-8"))
|
| 178 |
+
quant = config["quantization"]
|
| 179 |
+
if (quant["format"] != "nf4" or not quant["double_quantization"]
|
| 180 |
+
or quant["compute_dtype"] != "bfloat16" or config["pooler"] != "mean"):
|
| 181 |
+
raise ValueError("unsupported release configuration")
|
| 182 |
+
model_id = config["base_model"]
|
| 183 |
+
revision = config["base_revision"]
|
| 184 |
+
self.tokenizer = AutoTokenizer.from_pretrained(model_id, revision=revision)
|
| 185 |
+
base = AutoModel.from_pretrained(
|
| 186 |
+
model_id, revision=revision, dtype=torch.bfloat16,
|
| 187 |
+
quantization_config=BitsAndBytesConfig(
|
| 188 |
+
load_in_4bit=True, bnb_4bit_quant_type="nf4",
|
| 189 |
+
bnb_4bit_use_double_quant=True, bnb_4bit_compute_dtype=torch.bfloat16,
|
| 190 |
+
),
|
| 191 |
+
device_map={"": device}, attn_implementation="sdpa",
|
| 192 |
+
)
|
| 193 |
+
if type(base).__name__ != "Qwen3Model":
|
| 194 |
+
raise TypeError("expected a Qwen3Model hidden-state backbone")
|
| 195 |
+
base = prepare_model_for_kbit_training(base, use_gradient_checkpointing=False)
|
| 196 |
+
self.encoder = PeftModel.from_pretrained(
|
| 197 |
+
base, root / config["adapter_dir"], is_trainable=False,
|
| 198 |
+
).eval()
|
| 199 |
+
self.backbone = self.encoder.base_model.model
|
| 200 |
+
width = int(config["projection_dim"])
|
| 201 |
+
self.projection = nn.Linear(self.backbone.config.hidden_size, width).to(device)
|
| 202 |
+
self.scorer = _SetHead(width, int(config["set_layers"]), int(config["set_heads"])).to(device)
|
| 203 |
+
weights = load_file(root / config["head_file"], device="cpu")
|
| 204 |
+
self.projection.load_state_dict({
|
| 205 |
+
key.removeprefix("projection."): value for key, value in weights.items()
|
| 206 |
+
if key.startswith("projection.")
|
| 207 |
+
}, strict=True)
|
| 208 |
+
self.scorer.load_state_dict({
|
| 209 |
+
key.removeprefix("scorer."): value for key, value in weights.items()
|
| 210 |
+
if key.startswith("scorer.")
|
| 211 |
+
}, strict=True)
|
| 212 |
+
self.projection.eval()
|
| 213 |
+
self.scorer.eval()
|
| 214 |
+
self.device = device
|
| 215 |
+
self.max_tokens = int(config["max_tokens"])
|
| 216 |
+
|
| 217 |
+
@classmethod
|
| 218 |
+
def load(cls, release_dir: str | Path, device: str = "cuda") -> MiniJev:
|
| 219 |
+
return cls(release_dir, device)
|
| 220 |
+
|
| 221 |
+
def predict(
|
| 222 |
+
self,
|
| 223 |
+
state: Mapping[str, Any] | str,
|
| 224 |
+
question: str,
|
| 225 |
+
question_type: str,
|
| 226 |
+
answer_options: Sequence[Mapping[str, Any]],
|
| 227 |
+
) -> dict[str, Any]:
|
| 228 |
+
if len(answer_options) < 2:
|
| 229 |
+
raise ValueError("provide at least two answer options")
|
| 230 |
+
labels = [str(option.get("label") or option.get("name") or "") for option in answer_options]
|
| 231 |
+
if any(not label for label in labels):
|
| 232 |
+
raise ValueError("every option needs a label")
|
| 233 |
+
option_ids = [str(option.get("id", i)) for i, option in enumerate(answer_options)]
|
| 234 |
+
if len(set(option_ids)) != len(option_ids):
|
| 235 |
+
raise ValueError("option IDs must be unique")
|
| 236 |
+
vectors = []
|
| 237 |
+
lengths = []
|
| 238 |
+
with torch.inference_mode():
|
| 239 |
+
for option in answer_options:
|
| 240 |
+
ids, suffix_mask = encode_branch(
|
| 241 |
+
self.tokenizer, state, question, question_type, option, self.max_tokens,
|
| 242 |
+
)
|
| 243 |
+
input_ids = torch.tensor([ids], dtype=torch.long, device=self.device)
|
| 244 |
+
mask = torch.tensor([suffix_mask], dtype=torch.bool, device=self.device)
|
| 245 |
+
with torch.autocast(device_type="cuda", dtype=torch.bfloat16):
|
| 246 |
+
hidden = self.backbone(input_ids=input_ids, use_cache=False).last_hidden_state
|
| 247 |
+
pooled = (hidden.float() * mask.unsqueeze(-1)).sum(1) / mask.sum(1, keepdim=True)
|
| 248 |
+
vectors.append(self.projection(pooled).squeeze(0))
|
| 249 |
+
lengths.append(len(ids))
|
| 250 |
+
valid = torch.ones((1, len(vectors)), dtype=torch.bool, device=self.device)
|
| 251 |
+
logits = self.scorer(torch.stack(vectors).unsqueeze(0), valid)
|
| 252 |
+
probs = torch.softmax(logits.float(), dim=1)[0].cpu().tolist()
|
| 253 |
+
winner = max(range(len(probs)), key=lambda i: probs[i])
|
| 254 |
+
return {
|
| 255 |
+
"selected_id": option_ids[winner],
|
| 256 |
+
"selected_label": labels[winner],
|
| 257 |
+
"options": [
|
| 258 |
+
{"id": option_ids[i], "label": labels[i], "probability": probs[i]}
|
| 259 |
+
for i in range(len(probs))
|
| 260 |
+
],
|
| 261 |
+
"branch_tokens": lengths,
|
| 262 |
+
}
|
requirements.txt
ADDED
|
@@ -0,0 +1,6 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
torch==2.14.0
|
| 2 |
+
transformers==5.17.0
|
| 3 |
+
peft==0.21.0
|
| 4 |
+
bitsandbytes==0.50.2
|
| 5 |
+
safetensors==0.8.0
|
| 6 |
+
accelerate==1.15.0
|