

v0.2.1: shorter card, storyboard, base-vs-fine-tuned table, latency profiling
Browse files- .gitattributes +3 -0
- NOTICE +2 -1
- README.md +31 -122
- eval/rtx4090.json +122 -84
- figures/androidcontrol_generalization.svg +34 -34
- figures/candidate_scaling.png +0 -0
- figures/candidate_scaling.svg +380 -119
- figures/overview.png +3 -0
- figures/overview.svg +194 -0
- figures/replay_mixed.png +3 -0
- figures/replay_success.png +3 -0
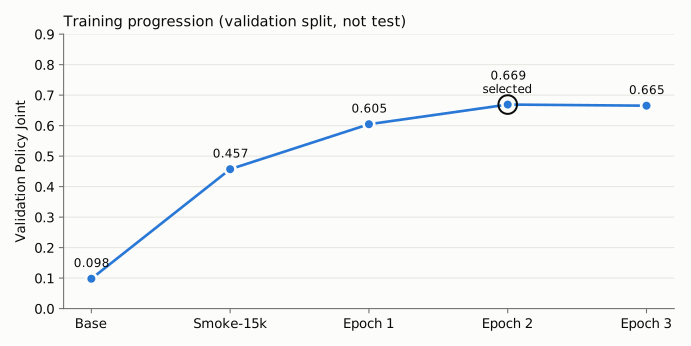
- figures/training_progression.svg +41 -41
.gitattributes
CHANGED
|
@@ -34,3 +34,6 @@ saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
tokenizer/tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
|
|
|
|
|
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
tokenizer/tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
| 37 |
+
figures/overview.png filter=lfs diff=lfs merge=lfs -text
|
| 38 |
+
figures/replay_mixed.png filter=lfs diff=lfs merge=lfs -text
|
| 39 |
+
figures/replay_success.png filter=lfs diff=lfs merge=lfs -text
|
NOTICE
CHANGED
|
@@ -23,7 +23,8 @@ This project builds on the following third-party work:
|
|
| 23 |
Copyright 2024 The Google Research Authors.
|
| 24 |
Licensed under the Apache License, Version 2.0.
|
| 25 |
Li et al., "On the Effects of Data Scale on Computer Control Agents", arXiv:2406.03679.
|
| 26 |
-
The dataset is not redistributed in this repository
|
|
|
|
| 27 |
|
| 28 |
4. Accessibility proto field layout follows google-deepmind/android_env
|
| 29 |
(Apache License, Version 2.0). No android_env code is included.
|
|
|
|
| 23 |
Copyright 2024 The Google Research Authors.
|
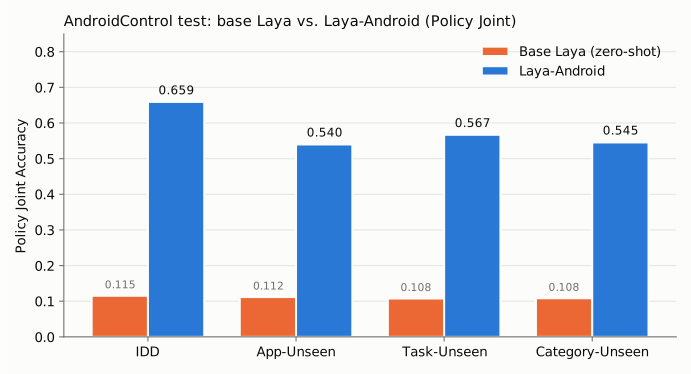
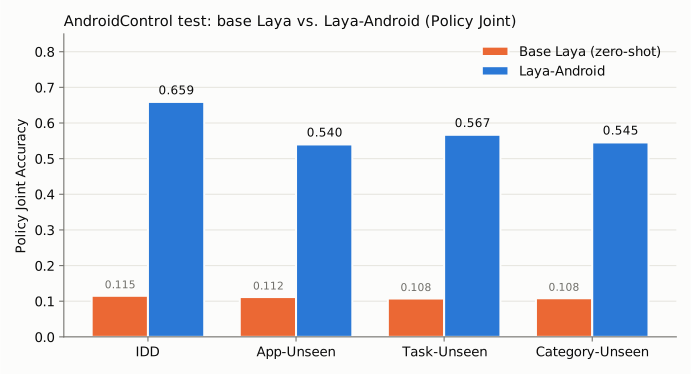
| 24 |
Licensed under the Apache License, Version 2.0.
|
| 25 |
Li et al., "On the Effects of Data Scale on Computer Control Agents", arXiv:2406.03679.
|
| 26 |
+
The dataset is not redistributed in this repository, except for the recorded screenshots of two
|
| 27 |
+
validation episodes shown in figures/replay_*.png (unmodified apart from resizing and overlays).
|
| 28 |
|
| 29 |
4. Accessibility proto field layout follows google-deepmind/android_env
|
| 30 |
(Apache License, Version 2.0). No android_env code is included.
|
README.md
CHANGED
|
@@ -37,40 +37,21 @@ model-index:
|
|
| 37 |
|
| 38 |
# Laya-Android
|
| 39 |
|
| 40 |
-
A 322M
|
| 41 |
|
| 42 |
-
[Code
|
| 43 |
|
| 44 |
-
|
| 45 |
|
| 46 |
-
| |
|
| 47 |
-
|---|---:|
|
| 48 |
-
|
|
| 49 |
-
| Visual input | **None** (accessibility tree only) |
|
| 50 |
-
| Training data | AndroidControl train split only |
|
| 51 |
-
| AndroidControl-High Type | **76.7** |
|
| 52 |
-
| AndroidControl-High Grounding | **61.7** |
|
| 53 |
-
| Full Step SR | N/A (see below) |
|
| 54 |
-
| Median latency | **38.3 ms** (RTX 4090, batch 1) |
|
| 55 |
|
| 56 |
-
|
| 57 |
|
| 58 |
-
|
| 59 |
|
| 60 |
-
|
| 61 |
-
|
| 62 |
-
```text
|
| 63 |
-
Goal find a nike casual shoes for women on the kicks crew app
|
| 64 |
-
History INPUT_TEXT "casual shoes for women" → CLICK (WMNS) PUMA Oslo Maja … → CLICK Filter
|
| 65 |
-
UI [0] Dismiss (View) [1] FILTER Clear All … scroll [2] - (Button) [3] Clear All (View)
|
| 66 |
-
[4] Brand (ImageView) [5] Size And Type (ImageView) [6] Release Year (ImageView) … 16 total
|
| 67 |
-
|
| 68 |
-
operation CLICK 0.935 WAIT 0.039 SCROLL_DOWN 0.012
|
| 69 |
-
target [4] Brand 0.931 [7] Product Types 0.033 [5] Size And Type 0.008
|
| 70 |
-
gold CLICK [4] Brand ✓
|
| 71 |
-
```
|
| 72 |
-
|
| 73 |
-
## Quick start
|
| 74 |
|
| 75 |
```python
|
| 76 |
# pip install laya==0.3.28
|
|
@@ -98,25 +79,19 @@ out = agent.system_one(state, questions, max_len=3072, head_max_len=1536)
|
|
| 98 |
print(out["answers"]["operation"]["choice"], out["answers"]["target"]["choice"])
|
| 99 |
```
|
| 100 |
|
| 101 |
-
Candidate labels must
|
| 102 |
-
|
| 103 |
-
## Results
|
| 104 |
-
|
| 105 |
-
One evaluation of the frozen checkpoint (epoch 2, chosen on validation). Type and Grounding were computed from the saved predictions after the protocol was committed.
|
| 106 |
-
|
| 107 |
-
### AndroidControl-High (InfiGUI-R1 evaluator, 8444 steps / 1543 episodes)
|
| 108 |
|
| 109 |
-
|
| 110 |
-
|---|---:|---|---:|---:|---:|
|
| 111 |
-
| InfiGUI-R1-3B† | 3B | Screenshot | 82.7 | 74.4 | 71.1 |
|
| 112 |
-
| Laya base (zero-shot) | 322M | Accessibility tree | 29.0 | 11.8 | N/A |
|
| 113 |
-
| **Laya-Android** | **322M** | **Accessibility tree** | **76.7** | **61.7** | **N/A** |
|
| 114 |
|
| 115 |
-
|
| 116 |
|
| 117 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
| 118 |
|
| 119 |
-
|
| 120 |
|
| 121 |
| Split | Base Laya | Laya-Android | Δ |
|
| 122 |
|---|---:|---:|---:|
|
|
@@ -125,85 +100,26 @@ Laya-Android selects actions from accessibility-derived UI candidates rather tha
|
|
| 125 |
| Task-Unseen | 0.108 | **0.567** | +45.9pt |
|
| 126 |
| Category-Unseen | 0.108 | **0.545** | +43.7pt |
|
| 127 |
|
| 128 |
-
|
| 129 |
-
|
| 130 |
-
Policy Joint = operation correct and, for clicks, the chosen element is the gold element. It is an internal metric, not AndroidControl SR.
|
| 131 |
-
|
| 132 |
-
### Target top-1 by candidate count (union of test steps)
|
| 133 |
-
|
| 134 |
-
| Candidates | n | Base Laya | Laya-Android |
|
| 135 |
-
|---|---:|---:|---:|
|
| 136 |
-
| 1-5 | 547 | 0.397 | 0.839 |
|
| 137 |
-
| 6-10 | 860 | 0.138 | 0.677 |
|
| 138 |
-
| 11-20 | 2025 | 0.107 | 0.665 |
|
| 139 |
-
| 21-50 | 1228 | 0.067 | 0.543 |
|
| 140 |
-
| >50 | 96 | 0.021 | 0.542 |
|
| 141 |
-
|
| 142 |
-

|
| 143 |
-
|
| 144 |
-
### Latency (NVIDIA GeForce RTX 4090)
|
| 145 |
-
|
| 146 |
-
| Params | dtype | Batch | Median | p90 | p95 | Mean | End-to-end median | Peak VRAM (bs1) | Throughput (bs32) |
|
| 147 |
-
|---:|---|---:|---:|---:|---:|---:|---:|---:|---:|
|
| 148 |
-
| 322M | bf16 autocast | 1 | 38.3 ms | 41.2 ms | 42.7 ms | 38.0 ms | 42.8 ms | 1.66 GB | 64 steps/s |
|
| 149 |
-
|
| 150 |
-
### Training progression (validation Policy Joint)
|
| 151 |
-
|
| 152 |
-
| Checkpoint | Val Policy Joint |
|
| 153 |
-
|---|---:|
|
| 154 |
-
| Base | 0.098 |
|
| 155 |
-
| Smoke-15k | 0.457 |
|
| 156 |
-
| Epoch 1 | 0.605 |
|
| 157 |
-
| Epoch 2 (selected) | 0.669 |
|
| 158 |
-
| Epoch 3 | 0.665 |
|
| 159 |
-
|
| 160 |
-

|
| 161 |
-
|
| 162 |
-
Per-split Type / Grounding, operation recall and failure examples: see the [GitHub README](https://github.com/Byun11/laya-android#failure-analysis).
|
| 163 |
|
| 164 |
## Model details
|
| 165 |
|
| 166 |
-
|
| 167 |
-
|
| 168 |
-
|
| 169 |
-
|
| 170 |
-
| Base model | `convaiinnovations/laya`, subfolder `multilingual`, revision `7b928d828b7b0e022f929d9bd2e44165aa270148` (mmBERT-base encoder) |
|
| 171 |
-
| Parameters | ~322M |
|
| 172 |
-
| Sequence budget | `max_len` 3072, `head_max_len` 1536 |
|
| 173 |
-
| License | Apache-2.0 |
|
| 174 |
-
|
| 175 |
-
## Intended use
|
| 176 |
-
|
| 177 |
-
- Research on lightweight Android GUI action-selection policies
|
| 178 |
-
- Accessibility-based mobile agents, e.g. a fast step selector under a planner
|
| 179 |
-
- Fast System-1 style decision models
|
| 180 |
-
|
| 181 |
-
## Out-of-scope use
|
| 182 |
-
|
| 183 |
-
- Operating real devices or accounts unsupervised, especially payments, messaging, account or security settings, or other irreversible actions
|
| 184 |
-
- Tasks that need visual understanding (images, canvases, games, custom-drawn UI)
|
| 185 |
-
- Generating text: `INPUT_TEXT` content and `OPEN_APP` names are not produced
|
| 186 |
-
- Claims of end-to-end task success: v0 is evaluated offline, step by step
|
| 187 |
|
| 188 |
## Training
|
| 189 |
|
| 190 |
-
AndroidControl
|
| 191 |
|
| 192 |
## Limitations
|
| 193 |
|
| 194 |
-
-
|
| 195 |
-
-
|
| 196 |
-
-
|
| 197 |
-
-
|
| 198 |
-
-
|
| 199 |
-
- **Offline benchmark only.** Step-by-step with gold history; not a measured task success rate.
|
| 200 |
-
|
| 201 |
-
## Ethical and safety considerations
|
| 202 |
-
|
| 203 |
-
- A GUI action model can trigger real side effects. Keep a human in the loop and gate sensitive or irreversible actions.
|
| 204 |
-
- Accessibility trees can contain personal data shown on screen. Process them locally and avoid logging them.
|
| 205 |
-
- Calibrated confidence can support abstention, but it does not guarantee correctness.
|
| 206 |
-
- Training data covers a limited set of apps and locales.
|
| 207 |
|
| 208 |
## Citation
|
| 209 |
|
|
@@ -212,16 +128,9 @@ AndroidControl only, official splits: 13,594 train episodes / 74,714 actions (9
|
|
| 212 |
title = {Laya-Android},
|
| 213 |
author = {Byun, Jaeyeon},
|
| 214 |
year = {2026},
|
| 215 |
-
version = {0.
|
| 216 |
url = {https://github.com/Byun11/laya-android}
|
| 217 |
}
|
| 218 |
```
|
| 219 |
|
| 220 |
-
|
| 221 |
-
|
| 222 |
-
## Acknowledgements
|
| 223 |
-
|
| 224 |
-
- Built on top of [Laya](https://github.com/NandhaKishorM/laya) by Convai Innovations (Apache-2.0). Not affiliated with or endorsed by Convai Innovations.
|
| 225 |
-
- Encoder: [mmBERT-base](https://huggingface.co/jhu-clsp/mmBERT-base) (MIT).
|
| 226 |
-
- Data: [AndroidControl](https://github.com/google-research/google-research/tree/master/android_control) by Google Research (Apache-2.0).
|
| 227 |
-
- Evaluator: [InfiGUI-R1](https://github.com/InfiXAI/InfiGUI-R1) (Apache-2.0).
|
|
|
|
| 37 |
|
| 38 |
# Laya-Android
|
| 39 |
|
| 40 |
+
A 322M typed-decision policy for Android GUI control, fine-tuned from [Laya](https://huggingface.co/convaiinnovations/laya) on AndroidControl. Accessibility tree only · no vision · no autoregressive generation.
|
| 41 |
|
| 42 |
+
[Code, docs and full results on GitHub](https://github.com/Byun11/laya-android)
|
| 43 |
|
| 44 |
+
## Highlights
|
| 45 |
|
| 46 |
+
| Parameters | AndroidControl-High Type | AndroidControl-High Grounding | Latency (RTX 4090, bs1) |
|
| 47 |
+
|:---:|:---:|:---:|:---:|
|
| 48 |
+
| **322M** | **76.7** | **61.7** | **~40 ms** |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 49 |
|
| 50 |
+

|
| 51 |
|
| 52 |
+
Every step of a recorded validation episode with the model's predictions (blue = predicted, green = gold). The model never sees the screenshots; it reads the accessibility tree. Gold history, not a live run.
|
| 53 |
|
| 54 |
+
## Usage
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 55 |
|
| 56 |
```python
|
| 57 |
# pip install laya==0.3.28
|
|
|
|
| 79 |
print(out["answers"]["operation"]["choice"], out["answers"]["target"]["choice"])
|
| 80 |
```
|
| 81 |
|
| 82 |
+
Candidate labels must follow the repository's `src/candidates.py` / `src/serialization.py` (`"<text> (<class>) <flags>"`).
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 83 |
|
| 84 |
+
## Evaluation
|
|
|
|
|
|
|
|
|
|
|
|
|
| 85 |
|
| 86 |
+
AndroidControl-High, 8,444 test steps, public InfiGUI-R1 evaluator. Same model before and after fine-tuning:
|
| 87 |
|
| 88 |
+
| Model | Params | Type | Grounding | Full SR |
|
| 89 |
+
|---|---:|---:|---:|---:|
|
| 90 |
+
| Laya base (zero-shot) | 322M | 29.0 | 11.8 | N/A |
|
| 91 |
+
| **Laya-Android** | **322M** | **76.7** | **61.7** | **N/A** |
|
| 92 |
+
| Δ | | +47.6 | +49.9 | |
|
| 93 |
|
| 94 |
+
Full SR is N/A (v0 does not generate text or app names). Screenshot VLMs on the same evaluator report higher numbers (e.g. InfiGUI-R1-3B 82.7 / 74.4) but solve a different task (pixel coordinates vs. choosing accessibility candidates).
|
| 95 |
|
| 96 |
| Split | Base Laya | Laya-Android | Δ |
|
| 97 |
|---|---:|---:|---:|
|
|
|
|
| 100 |
| Task-Unseen | 0.108 | **0.567** | +45.9pt |
|
| 101 |
| Category-Unseen | 0.108 | **0.545** | +43.7pt |
|
| 102 |
|
| 103 |
+
Policy Joint = operation correct and, for clicks, the gold element chosen (internal metric, not SR). One test pass of the frozen checkpoint; protocol fixed before scoring ([eval_protocol.md](https://github.com/Byun11/laya-android/blob/main/docs/eval_protocol.md)).
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 104 |
|
| 105 |
## Model details
|
| 106 |
|
| 107 |
+
- Base: `convaiinnovations/laya` / `multilingual` @ `7b928d8` (mmBERT-base encoder), ~322M parameters, Apache-2.0
|
| 108 |
+
- Input: goal, last 3 actions, accessibility-derived UI candidates; `max_len` 3072, `head_max_len` 1536
|
| 109 |
+
- Output: probabilities over 12 operations and over the candidates
|
| 110 |
+
- Developed by Jaeyeon Byun (GitHub: Byun11); not affiliated with Convai Innovations
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 111 |
|
| 112 |
## Training
|
| 113 |
|
| 114 |
+
AndroidControl train split only (13,594 episodes, 74,714 actions). Supervised fine-tuning with `laya.train`, bf16, 3 epochs on one RTX 4090; checkpoint and temperatures chosen on validation. No RL, no oversampling, no screenshots. Details: [training.md](https://github.com/Byun11/laya-android/blob/main/docs/training.md).
|
| 115 |
|
| 116 |
## Limitations
|
| 117 |
|
| 118 |
+
- No visual input: unlabeled icons and custom-drawn UI are hard to tell apart.
|
| 119 |
+
- No text or app-name generation, so no Full Step SR; AndroidControl-Low not evaluated.
|
| 120 |
+
- Policy Joint drops 9–12 points on unseen apps, tasks and categories.
|
| 121 |
+
- Weak on rare actions (WAIT, BACK, horizontal scroll, LONG_PRESS).
|
| 122 |
+
- Offline, step-level benchmark with gold history. Do not let it operate real devices unsupervised; gate irreversible actions and keep on-screen personal data local.
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 123 |
|
| 124 |
## Citation
|
| 125 |
|
|
|
|
| 128 |
title = {Laya-Android},
|
| 129 |
author = {Byun, Jaeyeon},
|
| 130 |
year = {2026},
|
| 131 |
+
version = {0.2.1},
|
| 132 |
url = {https://github.com/Byun11/laya-android}
|
| 133 |
}
|
| 134 |
```
|
| 135 |
|
| 136 |
+
Built on [Laya](https://github.com/NandhaKishorM/laya) (Convai Innovations), [mmBERT-base](https://huggingface.co/jhu-clsp/mmBERT-base) and [AndroidControl](https://github.com/google-research/google-research/tree/master/android_control) (Google Research). Evaluator: [InfiGUI-R1](https://github.com/InfiXAI/InfiGUI-R1).
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
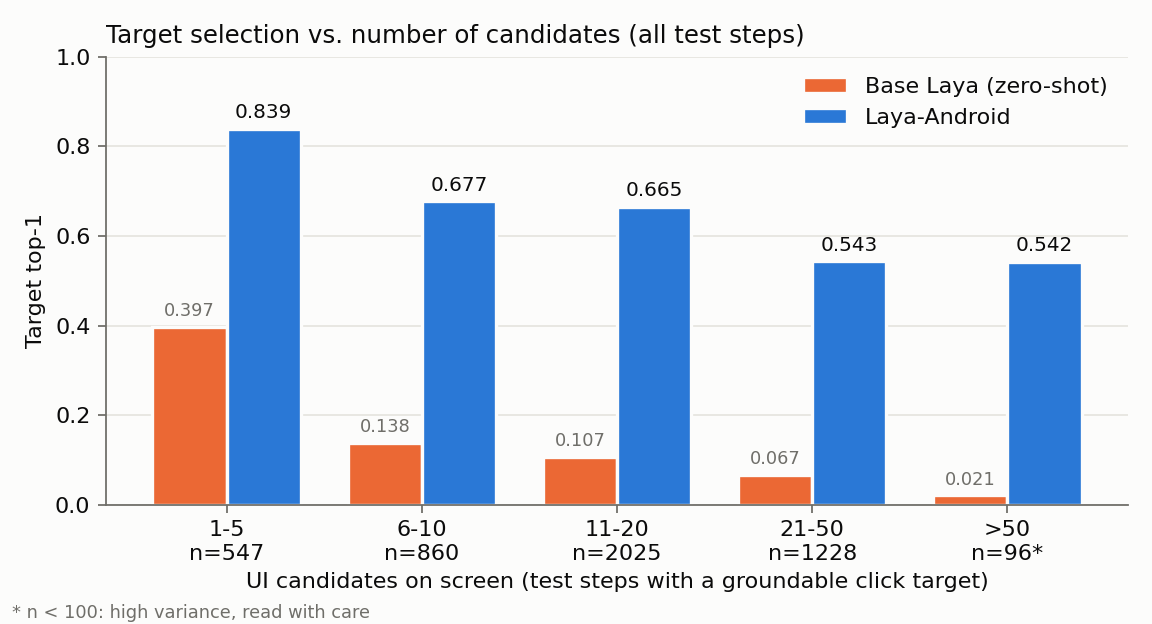
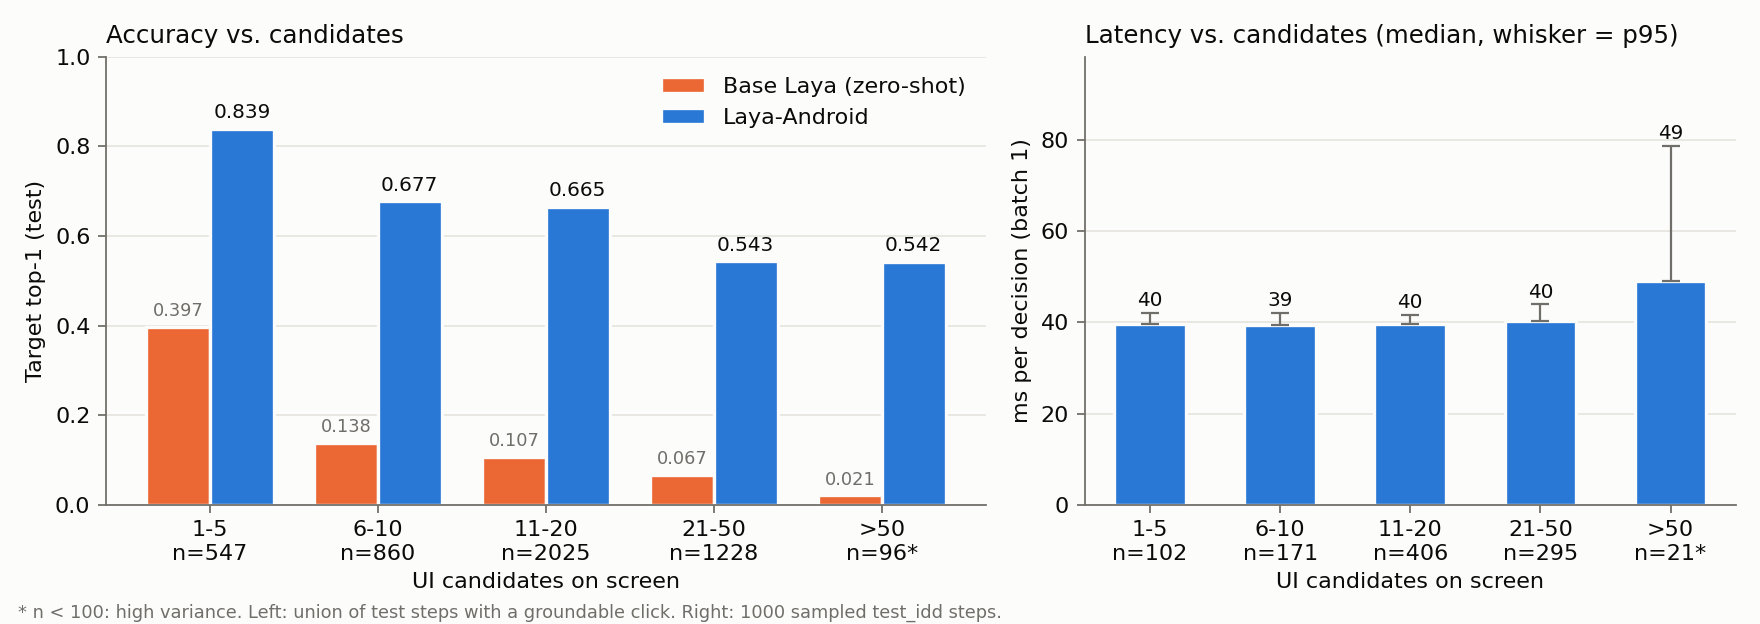
eval/rtx4090.json
CHANGED
|
@@ -6,124 +6,162 @@
|
|
| 6 |
"warmup": 100,
|
| 7 |
"measured": 1000,
|
| 8 |
"inputs": "test_idd, seed 0 (labels unused)",
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 9 |
"questions_per_step": "operation + target (all candidates), one forward",
|
| 10 |
"max_len": 3072,
|
| 11 |
"head_max_len": 1536,
|
| 12 |
"models": {
|
| 13 |
-
"
|
| 14 |
"forward_ms": {
|
| 15 |
"n": 1000,
|
| 16 |
-
"median":
|
| 17 |
-
"p90":
|
| 18 |
-
"p95":
|
| 19 |
-
"mean":
|
| 20 |
},
|
| 21 |
"e2e_ms": {
|
| 22 |
"n": 1000,
|
| 23 |
-
"median":
|
| 24 |
-
"p90": 48.
|
| 25 |
-
"p95": 51.
|
| 26 |
-
"mean":
|
| 27 |
},
|
| 28 |
"forward_ms_by_candidates": {
|
| 29 |
"1-5": {
|
| 30 |
"n": 102,
|
| 31 |
-
"median":
|
| 32 |
-
"p90": 41.
|
| 33 |
-
"p95":
|
| 34 |
-
"mean":
|
| 35 |
},
|
| 36 |
"6-10": {
|
| 37 |
"n": 171,
|
| 38 |
-
"median":
|
| 39 |
-
"p90": 41.
|
| 40 |
-
"p95":
|
| 41 |
-
"mean":
|
| 42 |
},
|
| 43 |
"11-20": {
|
| 44 |
"n": 406,
|
| 45 |
-
"median":
|
| 46 |
-
"p90":
|
| 47 |
-
"p95":
|
| 48 |
-
"mean":
|
| 49 |
},
|
| 50 |
"21-50": {
|
| 51 |
"n": 295,
|
| 52 |
-
"median":
|
| 53 |
-
"p90":
|
| 54 |
-
"p95":
|
| 55 |
-
"mean":
|
| 56 |
},
|
| 57 |
">50": {
|
| 58 |
"n": 21,
|
| 59 |
-
"median":
|
| 60 |
-
"p90":
|
| 61 |
-
"p95":
|
| 62 |
-
"mean":
|
| 63 |
}
|
| 64 |
},
|
| 65 |
-
"
|
| 66 |
-
|
| 67 |
-
|
| 68 |
-
|
| 69 |
-
|
| 70 |
-
|
| 71 |
-
|
| 72 |
-
|
| 73 |
-
"
|
| 74 |
-
|
| 75 |
-
|
| 76 |
-
|
| 77 |
-
|
| 78 |
-
|
| 79 |
-
|
| 80 |
-
"
|
| 81 |
-
|
| 82 |
-
|
| 83 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 84 |
},
|
| 85 |
-
"
|
| 86 |
-
|
| 87 |
-
|
| 88 |
-
|
| 89 |
-
"
|
| 90 |
-
|
| 91 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 92 |
},
|
| 93 |
-
"
|
| 94 |
-
"
|
| 95 |
-
|
| 96 |
-
|
| 97 |
-
|
| 98 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 99 |
},
|
| 100 |
-
"
|
| 101 |
-
"
|
| 102 |
-
|
| 103 |
-
|
| 104 |
-
|
| 105 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 106 |
},
|
| 107 |
-
"
|
| 108 |
-
"
|
| 109 |
-
|
| 110 |
-
|
| 111 |
-
|
| 112 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 113 |
},
|
| 114 |
-
"
|
| 115 |
-
"
|
| 116 |
-
|
| 117 |
-
|
| 118 |
-
|
| 119 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 120 |
}
|
| 121 |
},
|
| 122 |
-
"throughput_steps_per_s_batch32": 63.6,
|
| 123 |
-
"peak_vram_gb_bs1": 1.66,
|
| 124 |
-
"peak_vram_gb_batch32": 8.34,
|
| 125 |
"params_m": 321.9
|
| 126 |
}
|
| 127 |
-
}
|
| 128 |
-
"model": "ByunByun/laya-android"
|
| 129 |
}
|
|
|
|
| 6 |
"warmup": 100,
|
| 7 |
"measured": 1000,
|
| 8 |
"inputs": "test_idd, seed 0 (labels unused)",
|
| 9 |
+
"software": {
|
| 10 |
+
"laya": "0.3.28",
|
| 11 |
+
"transformers": "4.57.6",
|
| 12 |
+
"cuda": "13.0"
|
| 13 |
+
},
|
| 14 |
"questions_per_step": "operation + target (all candidates), one forward",
|
| 15 |
"max_len": 3072,
|
| 16 |
"head_max_len": 1536,
|
| 17 |
"models": {
|
| 18 |
+
"laya_android": {
|
| 19 |
"forward_ms": {
|
| 20 |
"n": 1000,
|
| 21 |
+
"median": 39.74,
|
| 22 |
+
"p90": 41.95,
|
| 23 |
+
"p95": 43.51,
|
| 24 |
+
"mean": 40.26
|
| 25 |
},
|
| 26 |
"e2e_ms": {
|
| 27 |
"n": 1000,
|
| 28 |
+
"median": 44.46,
|
| 29 |
+
"p90": 48.63,
|
| 30 |
+
"p95": 51.13,
|
| 31 |
+
"mean": 45.34
|
| 32 |
},
|
| 33 |
"forward_ms_by_candidates": {
|
| 34 |
"1-5": {
|
| 35 |
"n": 102,
|
| 36 |
+
"median": 39.66,
|
| 37 |
+
"p90": 41.49,
|
| 38 |
+
"p95": 42.07,
|
| 39 |
+
"mean": 39.85
|
| 40 |
},
|
| 41 |
"6-10": {
|
| 42 |
"n": 171,
|
| 43 |
+
"median": 39.49,
|
| 44 |
+
"p90": 41.12,
|
| 45 |
+
"p95": 42.08,
|
| 46 |
+
"mean": 39.72
|
| 47 |
},
|
| 48 |
"11-20": {
|
| 49 |
"n": 406,
|
| 50 |
+
"median": 39.62,
|
| 51 |
+
"p90": 40.93,
|
| 52 |
+
"p95": 41.55,
|
| 53 |
+
"mean": 39.71
|
| 54 |
},
|
| 55 |
"21-50": {
|
| 56 |
"n": 295,
|
| 57 |
+
"median": 40.27,
|
| 58 |
+
"p90": 42.85,
|
| 59 |
+
"p95": 43.91,
|
| 60 |
+
"mean": 40.47
|
| 61 |
},
|
| 62 |
">50": {
|
| 63 |
"n": 21,
|
| 64 |
+
"median": 48.97,
|
| 65 |
+
"p90": 69.71,
|
| 66 |
+
"p95": 78.59,
|
| 67 |
+
"mean": 54.25
|
| 68 |
}
|
| 69 |
},
|
| 70 |
+
"forward_ms_by_input_tokens": {
|
| 71 |
+
"<=512": {
|
| 72 |
+
"n": 649,
|
| 73 |
+
"median": 39.6,
|
| 74 |
+
"p90": 41.14,
|
| 75 |
+
"p95": 41.81,
|
| 76 |
+
"mean": 39.78
|
| 77 |
+
},
|
| 78 |
+
"513-1024": {
|
| 79 |
+
"n": 292,
|
| 80 |
+
"median": 39.85,
|
| 81 |
+
"p90": 41.68,
|
| 82 |
+
"p95": 42.49,
|
| 83 |
+
"mean": 39.92
|
| 84 |
+
},
|
| 85 |
+
"1025-1536": {
|
| 86 |
+
"n": 49,
|
| 87 |
+
"median": 42.88,
|
| 88 |
+
"p90": 46.74,
|
| 89 |
+
"p95": 48.44,
|
| 90 |
+
"mean": 43.75
|
| 91 |
+
},
|
| 92 |
+
">1536": {
|
| 93 |
+
"n": 10,
|
| 94 |
+
"median": 53.1,
|
| 95 |
+
"p90": 83.47,
|
| 96 |
+
"p95": 105.45,
|
| 97 |
+
"mean": 64.05
|
| 98 |
+
}
|
| 99 |
},
|
| 100 |
+
"peak_vram_allocated_gb_bs1": 1.66,
|
| 101 |
+
"peak_vram_reserved_gb_bs1": 1.91,
|
| 102 |
+
"batch_sweep": {
|
| 103 |
+
"1": {
|
| 104 |
+
"batch_ms": {
|
| 105 |
+
"n": 1000,
|
| 106 |
+
"median": 39.06,
|
| 107 |
+
"p90": 41.12,
|
| 108 |
+
"p95": 42.26,
|
| 109 |
+
"mean": 39.48
|
| 110 |
+
},
|
| 111 |
+
"throughput_steps_per_s": 25.3,
|
| 112 |
+
"peak_vram_allocated_gb": 1.66,
|
| 113 |
+
"peak_vram_reserved_gb": 1.91
|
| 114 |
},
|
| 115 |
+
"4": {
|
| 116 |
+
"batch_ms": {
|
| 117 |
+
"n": 250,
|
| 118 |
+
"median": 39.99,
|
| 119 |
+
"p90": 51.89,
|
| 120 |
+
"p95": 67.4,
|
| 121 |
+
"mean": 44.25
|
| 122 |
+
},
|
| 123 |
+
"throughput_steps_per_s": 90.4,
|
| 124 |
+
"peak_vram_allocated_gb": 2.3,
|
| 125 |
+
"peak_vram_reserved_gb": 3.45
|
| 126 |
},
|
| 127 |
+
"8": {
|
| 128 |
+
"batch_ms": {
|
| 129 |
+
"n": 125,
|
| 130 |
+
"median": 71.35,
|
| 131 |
+
"p90": 134.79,
|
| 132 |
+
"p95": 158.07,
|
| 133 |
+
"mean": 81.02
|
| 134 |
+
},
|
| 135 |
+
"throughput_steps_per_s": 98.7,
|
| 136 |
+
"peak_vram_allocated_gb": 3.16,
|
| 137 |
+
"peak_vram_reserved_gb": 6.3
|
| 138 |
},
|
| 139 |
+
"16": {
|
| 140 |
+
"batch_ms": {
|
| 141 |
+
"n": 63,
|
| 142 |
+
"median": 177.91,
|
| 143 |
+
"p90": 293.32,
|
| 144 |
+
"p95": 371.29,
|
| 145 |
+
"mean": 198.02
|
| 146 |
+
},
|
| 147 |
+
"throughput_steps_per_s": 80.2,
|
| 148 |
+
"peak_vram_allocated_gb": 4.89,
|
| 149 |
+
"peak_vram_reserved_gb": 11.99
|
| 150 |
},
|
| 151 |
+
"32": {
|
| 152 |
+
"batch_ms": {
|
| 153 |
+
"n": 32,
|
| 154 |
+
"median": 431.11,
|
| 155 |
+
"p90": 778.52,
|
| 156 |
+
"p95": 827.76,
|
| 157 |
+
"mean": 535.89
|
| 158 |
+
},
|
| 159 |
+
"throughput_steps_per_s": 58.3,
|
| 160 |
+
"peak_vram_allocated_gb": 8.34,
|
| 161 |
+
"peak_vram_reserved_gb": 23.35
|
| 162 |
}
|
| 163 |
},
|
|
|
|
|
|
|
|
|
|
| 164 |
"params_m": 321.9
|
| 165 |
}
|
| 166 |
+
}
|
|
|
|
| 167 |
}
|
figures/androidcontrol_generalization.svg
CHANGED
|
|
figures/candidate_scaling.png
CHANGED
|
|
figures/candidate_scaling.svg
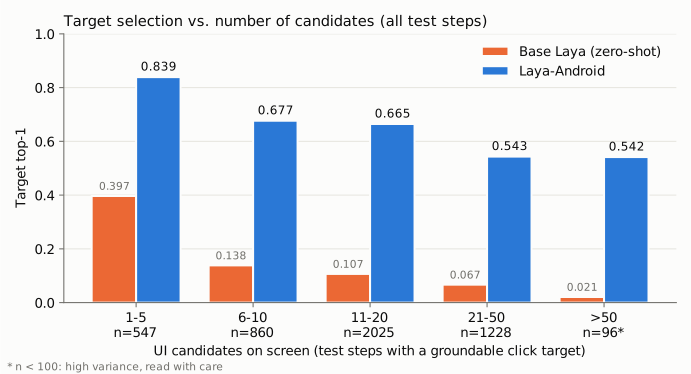
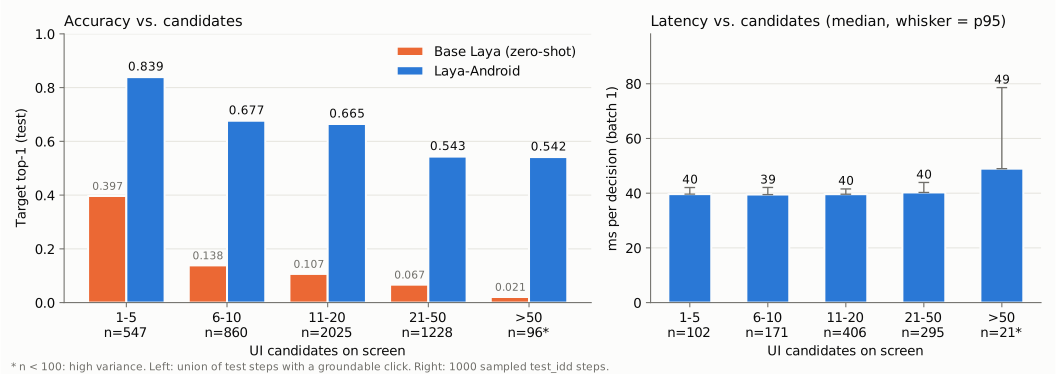
CHANGED
|
|
figures/overview.png
ADDED

|
Git LFS Details
|
figures/overview.svg
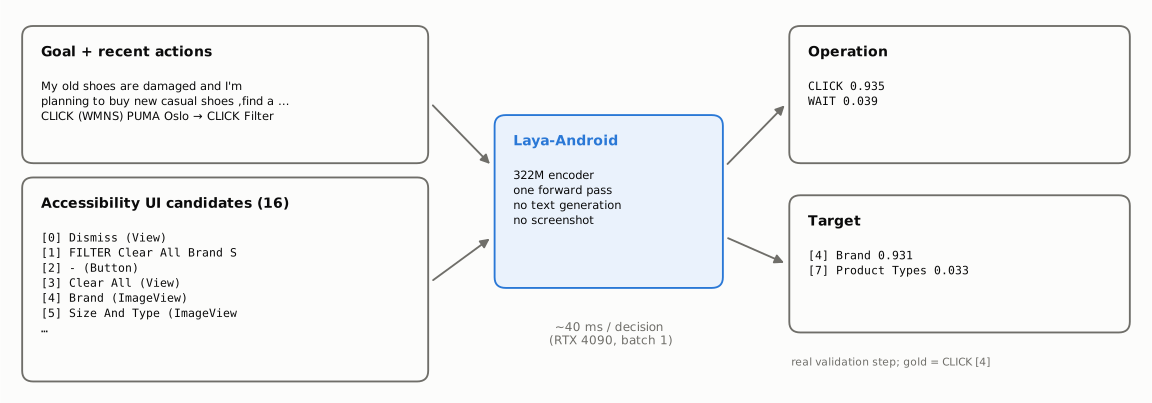
ADDED
|
figures/replay_mixed.png
ADDED

|
Git LFS Details
|
figures/replay_success.png
ADDED

|
Git LFS Details
|
figures/training_progression.svg
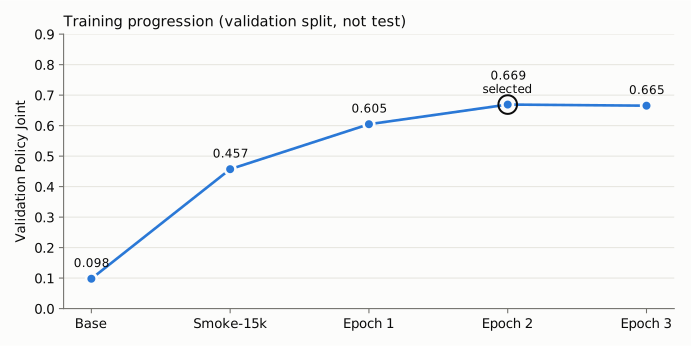
CHANGED
|
|