---
language: si
license: other
tags:
- gpt
- sinhala
- pytorch
- text-generation
- causal-lm
- rope
- swiglu
- custom-architecture
- low-resource-nlp
- from-scratch-pretraining
model-index:
- name: SinhalaLM
results: []
datasets:
- ChamaraVishwajithRajapaksha/sinhala-text-dataset
- ChamaraVishwajithRajapaksha/sinhala-question-answer-pairs
---
# 🇱🇰 SinhalaLM v0.0.1
**A GPT-style Sinhala Language Model, trained entirely from scratch**
`SinhalaLM` · `v0.0.1` · by **HelaAI**


---
## 📑 Table of contents
- [Overview](#-overview)
- [Why SinhalaLM](#-why-sinhalalm)
- [Authors](#-authors)
- [Model summary](#-model-summary)
- [Intended use](#-intended-use)
- [Architecture](#-architecture)
- [Tokenizer](#-tokenizer)
- [Training procedure](#-training-procedure)
- [Training hardware](#-training-hardware)
- [How to use](#-how-to-use)
- [Limitations and biases](#-limitations-and-biases)
- [Files in this repo](#-files-in-this-repo)
- [License](#-license)
- [Citation](#-citation)
- [Contact](#-contact)
---
## 🔎 Overview
**SinhalaLM** is a GPT-style, decoder-only causal language model trained **entirely from scratch** on a large Sinhala text corpus. Rather than adapting an existing multilingual model to Sinhala through continual pretraining, SinhalaLM was designed and sized specifically for the Sinhala language, using a compute-aware architecture built around three modern techniques:
- 🌀 **Rotary Position Embeddings (RoPE)** for relative positional encoding
- ⚡ **SwiGLU** gated feed-forward blocks instead of a plain ReLU MLP
- 🔤 A **custom byte-pair encoding (BPE) tokenizer** trained specifically on the Sinhala script (and retained English characters) present in the training corpus
This is a **custom architecture** — it is *not* a standard `transformers` (`AutoModel`) class. The full model definition ships in this repository as `modeling_sinhalalm.py` and must be imported directly. Full loading and generation instructions are provided below.
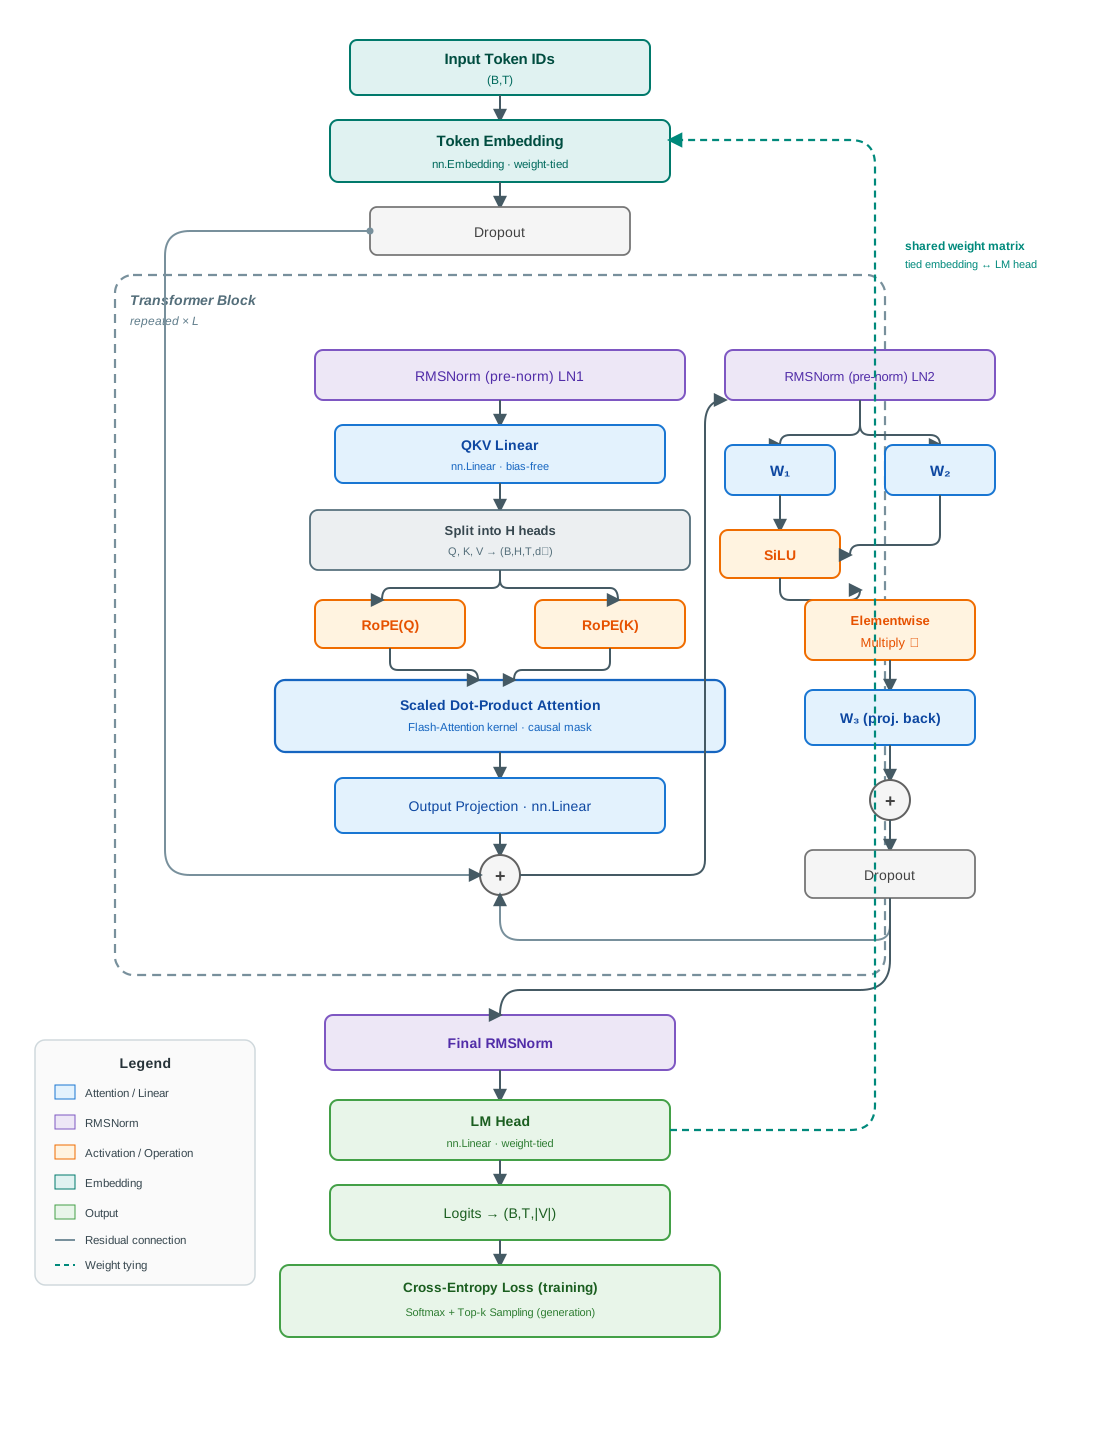
Detailed internal architecture of a single SinhalaLM decoder block — showing the QKV split, per-head RoPE application, the fused Flash-Attention kernel, both residual connections, and the SwiGLU feed-forward path with weight tying between the token embedding and the LM head.
> ⚠️ **Private repository.** Only Hugging Face accounts explicitly granted access can pull this repo. Do not share the access token.
---
## 💡 Why SinhalaLM
Sinhala is spoken by over 20 million people, yet it remains comparatively under-served by mainstream multilingual language models, which tend to prioritize languages with abundant digital text and stronger commercial incentives. The dominant strategy for extending LLM capability to low-resource languages like Sinhala has been **continual pretraining** of a large existing model (e.g. adapting an 8-billion-parameter backbone) — an approach that requires substantial GPU memory and incurs high inference cost.
SinhalaLM explores the alternative path: **building a compact model from scratch**, sized to match the pretraining data actually available for the language. At **~32.9M parameters** — roughly **240× smaller** than an 8B-parameter continually pretrained alternative — SinhalaLM is:
- 💰 **Cheap to train** — fits comfortably on a single consumer/prosumer GPU
- 🚀 **Cheap and fast to deploy** — low memory footprint, low inference latency
- 🎯 **Fully fine-tunable** — its small size allows *full* fine-tuning (updating every parameter) on a single GPU, rather than relying on low-rank adapters
---
## 👥 Authors
| Name | Affiliation | Contact |
|---|---|---|
| **Chamara Vishwajith** | University of Ruhuna, Sri Lanka | rajapaksha_rmcv_e23@engug.ruh.ac.lk, cam.chamara@giam.com |
| **Dr. Kushan Sudheera** | Dept. of Electrical and Information Engineering, University of Ruhuna, Sri Lanka | kushan@eie.ruh.ac.lk |
| **Dineth Jayakody** | Old Dominion University, United States | djaya003@odu.edu |
---
## 📋 Model summary
| | |
|---|---|
| **Model name** | SinhalaLM |
| **Version** | v0.0.1 |
| **Developed by** | HelaAI |
| **Model type** | Decoder-only causal language model (GPT-style) |
| **Language** | Sinhala (`si`), with retained English letters/punctuation |
| **Training approach** | From-scratch pretraining (not continually pretrained from an existing checkpoint) |
| **License** | Other — see [License](#-license) |
---
## 🎯 Intended use
SinhalaLM is intended for **Sinhala text generation and continuation** — research, prototyping, and experimentation with a from-scratch Sinhala language model. It has also been fine-tuned and evaluated as a base for downstream Sinhala tasks such as text classification and question answering.
**Not intended for:**
- ❌ Production use without further evaluation, safety review, and human oversight.
- ❌ Factual question-answering out of the box — the *base* model is a language model, not an instruction-tuned or fact-checked assistant, and will generate fluent but not necessarily accurate or true text.
- ❌ Any use where generated text could cause harm if biased, incoherent, or false (e.g. medical, legal, or financial guidance).
---
## 🏗️ Architecture
SinhalaLM is a decoder-only transformer, built with a pre-normalized block structure and several architectural choices intended to improve training stability, throughput, and length generalization relative to a vanilla GPT baseline.
| Component | Design choice |
|---|---|
| **Parameters** | ~32.9M |
| **Embedding dim** | 512 |
| **Attention heads** | 8 |
| **Transformer layers** | 8 |
| **Context length** | 512 tokens |
| **Vocabulary size** | 15,000 |
| **Position encoding** | Rotary (RoPE) |
| **Feed-forward** | SwiGLU (gated activation) |
| **Normalization** | RMSNorm (pre-norm, at both sublayers and final output) |
| **Attention implementation** | PyTorch `scaled_dot_product_attention` (Flash Attention where available) |
| **Weight tying** | Input token embedding tied to the output LM head |
| **Dropout** | 0.2 |
**Per-block structure:**
1. RMSNorm → causal self-attention (RoPE applied to Q/K per head, fused Flash-Attention kernel) → residual add
2. RMSNorm → SwiGLU feed-forward (three-projection gated MLP) → residual add
**Systems-level details:**
- **Attention:** Implemented with a fused scaled-dot-product-attention kernel, avoiding materialization of the full `T × T` attention matrix and improving training throughput.
- **Output layer:** Weight tying shares parameters between the token embeddings and the language-modeling head, reducing the cost of the vocabulary projection.
- **Precision & compute:** Trained in `bfloat16` mixed precision with gradient accumulation over microbatches; the model graph is compiled ahead of time for operation fusion and improved GPU utilization.
For the full annotated diagram (query/key/value split, per-head RoPE, fused attention kernel, residual paths, and the SwiGLU projections), see the architecture figure above.
---
## 🔤 Tokenizer
A custom byte-pair encoding (BPE) tokenizer, trained from scratch on the training corpus via a streaming, multi-process word-frequency counting pass (so the corpus is never fully materialized in memory), followed by an iterative greedy merge procedure.
- Preserves Sinhala script (U+0D80–U+0DFF), English letters, digits, and common punctuation — nothing outside that set survives cleaning.
- **Special tokens:** ``, ``, ``, ``.
- **Vocabulary size:** 15,000 tokens.
- The authoritative loader is the `FastBPETokenizer` class shipped in `modeling_sinhalalm.py`; HF-style `vocab.json` / `merges.txt` / `tokenizer.json` files are also included for interoperability and inspection.
- The trained tokenizer is used to pre-encode the corpus once into a flat, memory-mapped binary token cache; training and validation batches are drawn from this cache via random-offset sampling using a pinned-memory, prefetching data loader — allowing training to scale to corpora substantially larger than available system RAM.
---
## ⚙️ Training procedure
**Pretraining corpus:** ~304 million Sinhala tokens, derived from the [Sinhala Text Dataset](https://huggingface.co/datasets/ChamaraVishwajithRajapaksha/sinhala-text-dataset).
| Hyperparameter | Value |
|---|---|
| Micro batch size | 32 |
| Gradient accumulation steps | 4 |
| Effective batch size | 128 |
| Max iterations (configured) | 150,000 |
| Warm-up iterations | 3,000 |
| Peak learning rate | 3 × 10⁻⁴ |
| Min learning rate | 3 × 10⁻⁵ |
| LR schedule | Cosine decay with linear warmup |
| Weight decay | 0.15 |
| Optimizer | AdamW (β = (0.9, 0.95)) |
| Precision | `torch.bfloat16` |
| Gradient clipping | Global norm 1.0 |
**Fine-tuning:** Because SinhalaLM has only ~32.9M parameters, it can be **fully fine-tuned** (every weight updated, no low-rank adapter constraint) on a single GPU. This was used to adapt SinhalaLM for downstream Sinhala tasks using an Alpaca-style supervised prompt format that separates instruction, question, and expected response with textual markers (e.g. for question answering: an instruction line, a `### ප්රශ්නය:` question section, and a `### පිළිතුර:` answer section, wrapped in `` / ``).
| Fine-tuning hyperparameter | Value |
|---|---|
| Batch size (grad. accum.) | 8 (8) |
| Epochs | 3 |
| Peak learning rate | 1 × 10⁻⁴ |
---
## 🖥️ Training hardware
| | |
|---|---|
| Device | CUDA |
| GPU | NVIDIA GeForce RTX 5090 |
| VRAM | 33.7 GB |
| Precision | `torch.bfloat16` |
| Data loader workers | 30 |
Full training curves (train/validation loss, learning-rate schedule, throughput, perplexity, and a combined dashboard) plus raw CSV logs are included in the [`analysis/`](./analysis) folder of this repo:
- `01_train_loss.png`, `02_val_loss.png`, `03_train_vs_val_loss.png`
- `04_learning_rate.png`, `05_throughput.png`
- `06_val_loss_and_lr.png`, `07_perplexity.png`, `08_smoothed_loss.png`
- `09_dashboard.png` — all of the above in one view
- `train_loss.csv`, `val_loss.csv`, `lr_schedule.csv`, `throughput.csv`
- `training_summary.txt` / `training_summary.json`
---
## 🚀 How to use
Install dependencies:
```bash
pip install torch huggingface_hub safetensors
```
Download, load, and generate:
```python
from huggingface_hub import snapshot_download
import torch, json, sys
# 1. Download the repo (private — requires a token with read access)
local_dir = snapshot_download(repo_id="ChamaraVishwajithRajapaksha/SinhalaLM-V.0.0.1", token="YOUR_HF_TOKEN")
# 2. Import the model + tokenizer classes shipped in this repo
sys.path.insert(0, local_dir)
from modeling_sinhalalm import SinhalaGPT, FastBPETokenizer
# 3. Load config
config = json.load(open(f"{local_dir}/config.json"))
# 4. Load tokenizer
tokenizer = FastBPETokenizer.load(f"{local_dir}/bpe_vocabulary.json")
# 5. Build model + load weights
from safetensors.torch import load_file
state_dict = load_file(f"{local_dir}/model.safetensors")
model = SinhalaGPT(
vocab_size=config["vocab_size"],
embed_dim=config["n_embed"],
n_heads=config["n_heads"],
n_layers=config["n_layers"],
block_size=config["block_size"],
dropout=0.0, # no dropout at inference
)
model.load_state_dict(state_dict)
model.eval()
# 6. Generate (unconditional — starts from )
device = "cuda" if torch.cuda.is_available() else "cpu"
model.to(device)
ctx = torch.tensor([[tokenizer.stoi[""]]], dtype=torch.long, device=device)
out = model.generate(ctx, max_new_tokens=200, temperature=0.8, top_k=200)
print(tokenizer.decode(out[0].tolist()))
# 6b. Or continue a prompt instead of generating unconditionally
prompt_ids = tokenizer.encode("ආයුබෝවන්")
eos_id = tokenizer.stoi[""]
if prompt_ids and prompt_ids[-1] == eos_id:
prompt_ids = prompt_ids[:-1] # drop auto-appended before continuing
ctx = torch.tensor([prompt_ids], dtype=torch.long, device=device)
out = model.generate(ctx, max_new_tokens=200, temperature=0.8, top_k=200)
print(tokenizer.decode(out[0].tolist()))
```
### Generation parameters
| Parameter | Effect |
|---|---|
| `temperature` | Lower (e.g. 0.5–0.7) → more deterministic/repetitive. Higher (e.g. 1.0+) → more random/creative. |
| `top_k` | Restricts sampling to the *k* most likely tokens at each step. Lower = safer, less diverse. |
| `max_new_tokens` | Number of tokens to generate. Model's max context is 512 tokens total (prompt + generation; older tokens are truncated once exceeded). |
---
## ⚠️ Limitations and biases
- Trained on a general Sinhala text corpus without curated filtering for toxicity, bias, or factual accuracy — treat all outputs as **unverified**.
- As a base (non-instruction-tuned) model, the pretrained checkpoint continues text rather than following instructions or answering questions directly; instruction-following behavior requires fine-tuning.
- May produce repetitive or incoherent text for long generations, and can reflect biases present in the training data.
- **Context window is limited to 512 tokens** — not suitable for long-document tasks in its current form.
- No safety filtering or content moderation has been applied to outputs.
- SinhalaLM is **monolingual by design** and does not support multilingual or cross-lingual use cases.
---
## 📁 Files in this repo
| File | Description |
|---|---|
| `model.safetensors` | Model weights, in the safetensors format |
| `config.json` | Architecture config + model metadata |
| `bpe_vocabulary.json` | Full custom tokenizer (vocab + merges + merge priorities) — load with `FastBPETokenizer.load(...)` |
| `vocab.json`, `merges.txt`, `tokenizer.json`, `tokenizer_config.json`, `special_tokens_map.json` | HF-style tokenizer files, for interoperability/inspection (the authoritative loader is `FastBPETokenizer`) |
| `modeling_sinhalalm.py` | Full source of the `SinhalaGPT` model class and `FastBPETokenizer` |
| `images/sinhalalm_detailed_architecture.svg` | Detailed architecture diagram of a single SinhalaLM decoder block |
| `analysis/` | Training graphs, CSV logs, and text/JSON training summary |
| `generated_sinhala_text.txt` | Sample output generated at the end of training, if available |
---
## 📜 License
This model is released under a custom/other license. Update this section with your actual terms (e.g. permitted uses, redistribution, commercial use) before granting access to others.
---
## 📚 Citation
If you use this model, please cite:
```bibtex
@misc{sinhalalm001,
title = {SinhalaLM v0.0.1},
author = {Chamara Vishwajith and Dr. Kushan Sudheera and Dineth Jayakody},
year = {2026},
note = {Custom GPT-style Sinhala language model, trained from scratch with RoPE and SwiGLU}
}
```
---
## 📬 Contact
Developed by **HelaAI**. For questions or access requests, contact one of the authors listed above, or the repository owner on Hugging Face.
—— SinhalaLM v0.0.1 · HelaAI ——